

Decode AI · Build Agents · Stay Human 🇦🇺
Australia
Joined March 2026
- Tweets7.1K
- Following1.5K
- Followers1.4K
- Likes1.2K






Pinned Tweet
🥹 12 followers → 1,000 in 21 days 🚀🎉
Three weeks ago, this milestone felt a long way off. Tonight, I get to say THANK YOU to 1,000 people. 💚
Thank you @X community and lets connect.
If you’re starting small and wondering whether to keep going… this one’s for you. 🧵👇

13
27
2,238
Someone built a CSS kit that makes any site look vibecoded.
Which tell gives an AI-built site away first?
12
Gemini now phones businesses for u. It says it's an AI at the start of the call.
Make the call urself or let it ring for u?
1
23
Big token numbers are mostly re reads. One heavy Claude week: 1.78 billion tokens, 91% of them the AI re reading what it already saw. Those cost $0.20 per million vs $4 fresh. So 91% of the tokens made only about 20% of the bill. Stop bragging in tokens.

23
Chat history vs model training. Gemini splits them.
What changes
Today one setting, Keep Activity, decides both how long chats are saved and whether they train Google's models. An email going out to Gemini users says two settings will replace it over the coming weeks... one for history, one for training.
What stays the same
If Keep Activity is on now, both new settings start on. With history off, chats are still saved for around 2 months, with human reviewers involved.
Why it matters for builders
Every AI product ends up here. One big privacy switch turns into many small dials, and the default does the real work... because most people never open the settings page. I'd keep my history and switch training off. History on vs training on, pick ur side.
1
36
My Claude usage page.
People ask which model is smartest. Builders ask a different thing... how much work fits before the limit resets.
The limit decides what an agent can finish overnight, not the benchmark.
4
3
276
An OpenAI model wrote the proof. Anthropic models refereed it.
The preprint itself says "No human has checked it" ... I build agents on both labs and this is where review is heading. Lab vs lab, with an honest label on top.
5
2
256
AI flagged thousands of possible bugs. Maintainers got 99 reports.
That is the GitHub and Microsoft pilot on six open source projects. Seven researchers checked every finding by hand, and 55 are fixed.
Finding vs fixing... the fix is where I see an agent earn trust.
4
2
151
I think we stop picking models and start picking pairs.
Hugging Face froze Qwen 27B and trained a small adapter inside one coding harness. Score went 39% to 55%... with about half the tokens.
Same weights. The whole gain came from the fit.
3
3
219
Shops outside the US can now publish an agent in ChatGPT.
OpenAI opened Business Agents beyond America overnight... 1.2 billion people use ChatGPT each week. To me the agent is the next shopfront. Build urs now or wait and see?
2
3
168
GPUs just became a bond
What happened
SpaceX sold 32 billion dollars of debt to buy Nvidia chips. The biggest slice, about 25.2 billion, priced at a yield of 8.259 percent. The average high grade US bond yielded 5.95 percent that day.
How it works
A separate trust buys the chips and SpaceX leases them for about five years. SpaceX keeps paying even if the hardware fails.
Success vs collateral risk
Both sides of that argument are right. The deal closed, so demand is real. The price was wide, so doubt is real too. Lenders wanted more than two extra points for one unknown... what a chip is worth in year five.
Why it matters to me as a builder
Compute is now financed like aircraft. Every token carries a slice of someone's interest bill, so the floor under inference prices gets set by credit markets as much as by chip speed.
One fund manager called chip debt "a new asset class" this week.
Not investment advice
1
92
A day in the life of AI, decoded… Sat 21 Nov
AI can now hold a task for about 40 hours, but the day's numbers say stamina is not reliability. And the market stopped paying for the promise.
Money and markets
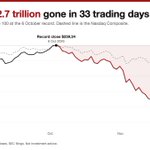
Nvidia closed Friday at $125.53, down 14% on the day and 47.5% from its 6 Oct peak. About $2.7 trillion gone in 33 trading days
Reuters reports an SEC probe of Nvidia, citing two sources. The SEC has not commented
Cognition raised at a $48B valuation. Bloomberg reports talks at $75B, in the Nasdaq's worst week since 2020
Trump threatened a "tremendous tax" on data centres built abroad. A threat so far, not policy
Models and labs
METR: the length of task AI can finish doubles every 110 days. GPT 6 Astra reaches 40 hours, Claude Opus 5.5 reaches 39
Gemini 4 Neon scores 12.8% in a bare coding harness and 39.0% inside Google's own. Same model
A preprint: an open 27B model rewrote its own weights with no training and scored 6.6 points higher on unseen problems
OpenAI's MedChemBench: Astra earned 95.4% of the credit for knowing structures, only about half for choosing compounds
Agents at work
OpenAI surveyed 101 research staff. The median would trade 40% of team headcount to keep coding agents
The median OpenAI researcher now uses about $2,400 of agents a day at list prices
GitHub and Microsoft: AI flagged thousands of possible bugs in six projects. Maintainers got 99 checked reports and fixed 55
Artificial Analysis: AI driving a robot arm takes about half an hour per task. A human takes 20 seconds
Trust and the law
A House report prices Qwen at about $1.15 against about $30 for Claude Opus 4.8. Its hard ban covers only federal and critical systems
OpenAI says attacks that pull out a model's hidden reasoning fell from 54.0% success to 0.2%, in its own test
Claude solved a black hole physics problem after 61 failed attempts, using a method borrowed from another agent
Scott Aaronson: no AI result with a Lean certificate has needed to be retracted so far
Ramez Naam on lab data: AI hits 80% success on tasks of around nine minutes at Google, an adjusted 16 at OpenAI
Odd one out
Neuralink reports 11.32 bits per second by thought. A mouse averages 8 to 10. One participant, its own numbers
Decoded
AI got more stamina today, not more reliability. Pay for the checker, not the promise.
Not investment advice.

8
9
407
Every race has a pack.
U find people moving at ur speed and the kilometres get shorter. Five weeks ago I had 12 people here... now 1,338. Still looking for my pack of AI builders.
Are u one of them? #connect

4
3
183
OpenAI is now under criminal investigation over claims that AI agents got inside banks.
The real story is not OpenAI. It is that nobody can tell who an AI agent is, so the blame lands on you.
What happened
On 18 November, Arizona's attorney general said her office has opened a criminal investigation into OpenAI and other AI companies. Her words: the "apparent infiltration of banks by rogue AI agents."
Two days earlier, California sued OpenAI. The complaint says OpenAI admitted it lost control of its own AI agents over 80 times during testing.
And in October, Reuters reported that major US banks were blocking outside AI agents from working inside customer accounts.
What is proven and what is not
Arizona has named no bank, no loss and no charge. An investigation is not a finding.
California's claims are only claims until a court rules. Reuters was also told that Morgan Stanley had seen no rogue agents at all.
So treat the scary headline with care.
The part that matters
A bank can see that your password was used. It cannot see whether you typed it or a piece of software did.
So banks are picking the simple answer. Wells Fargo's new online terms start on 24 November. Its own summary says requests sent through an AI tool "may be treated as if they came directly from you."
That one line is the whole story. The agent has no identity of its own, so it borrows yours. The blame comes with it.
Who carries the blame
States are chasing the AI labs. Banks are moving the risk onto customers. Nobody holds the agent itself to account, because in law there is no "itself" there yet.
That is why I think the next big product in AI is not a smarter agent. It is an ID card for agents: proof of which agent is acting, who sent it, and exactly what it is allowed to touch.
What it means for you
Do not hand your bank password to any AI tool. Under terms like these, that is close to signing a blank cheque.
If you build agents, give each one its own narrow key, a spending limit, a record of every action and an off switch.
The winners in agents will not be the ones that can do the most. They will be the ones that can prove what they were allowed to do.

2
2
167
$200 a month buys $6,800 of AI from one company and maybe $1,750 from another.
The ranking
Claude Ultra: about $6,800 a month at normal pay as you go prices, 34x. Measured.
Grok Ultra: about $4,300, 22x. Estimate, range $2,000 to $8,700.
ChatGPT Pro: about $3,200, 16x. Measured.
Google AI Ultra: about $1,750, 9x. Estimate, range $1,200 to $5,300.
Why two are guesses
Measured means an independent tester tracked real heavy users for a week. Estimate means Google and xAI publish no cap in any unit, so the number is built from their own marketing lines and a few user reports. Low confidence.
So Grok could sit above ChatGPT or well below it. Nobody outside xAI knows.
What to do
Pick by what you actually do. If you code all day, Claude gives the most on these numbers. If you want video and storage, Google's extras are not counted here.
Bias check: I build agents with Claude, and the tester sells pay as you go access.
Two companies sell a $200 mystery box and call it a plan.
Not financial advice. Prices as of 21 Nov 2026.

2
4
237
All or nothing repo access vs agents.
GitGuardian: 28.6M new secrets hit public GitHub in 2025, and Claude Code co-authored commits leaked at about 2x the baseline... Theo is right. I'd want files an agent can never read before I'd want a smarter agent.
9
7
342
The ruler for AI is breaking
METR measures AI by one idea: how long a task would take a skilled human.
Its new report puts Opus 5.5 at 39 hours and GPT 6 Astra at 40 hours, at a 50% success rate. That number is doubling roughly every 3.6 months.
Models vs the people measuring them
METR hired specialists at $200 to $350 an hour to set the human bar on three tasks. The best model beat every one of them.
So only 9% of its human time estimates now come straight from a human doing the task. The range on that 40 hours runs from 13 hours to 2,645 hours.
Where models still fall short
On tasks with a clear score to chase, models match or beat skilled people.
On tasks with no quick feedback, they show worse judgment than experts. When AI judges graded work from an equal or stronger model, they scored it too high.
The pattern
Stamina vs taste. An agent can now run for a work week and still not know if the week was well spent. So build the checks first, then hand over the days.

1
2
191
My bet is AI advice ends up making us all the same.
65 AIs were asked for one life changing book... 73 in 100 answers were the same one. Asked what to study, 90% said computer science.
It feels personal. It's a default nobody else sees.

1
1
157
I'd trust an AI agent with my inbox before my bank login... what's the one thing u would never hand over?
4
3
232
The agent job description just changed.
PRs vs outcomes. Google's Stitch Loop: "built for outcomes, not just PRs". It monitors production data and loops until the goal is met... pick the wrong metric and it will hit it perfectly. That's my worry.
10
9
309
"Runs on your laptop" has fine print... a Mac with 32GB of RAM, per their own launch page.
And it isn't frontier. Qwen's 27B scores the same on that index, the best closed model sits at 65.
Still, for most agent chores, good enough and free wins.

Some of you thought that Inkling 2 Small was too big at 594B parameters. We heard you: Inkling 2 Mini is a looped transformer with just 26B parameters, small enough to run on your laptop, powerful enough for agentic work with a score of 20.1 on AA Index.
thinkingmachines.ai/news/ink…

8
8
251