

The Open Enterprise AI Stack. Put frontier intelligence in every employee's hands and every business workflow.
Joined June 2026
- Tweets94
- Following83
- Followers47
- Likes6




Shopify's Catalog API has to work out that two stores sell the same product when the names and even the photos don't match. we hit that all the time with raw business data before an agent touches it. one thing, named differently everywhere

Shopify's Catalog API helps AI agents recognize when different stores sell the same product.
But merchants name, describe, and photograph that same product differently. To categorize which product groups belong together, we created a system that turns billions of listings and trillions of candidate pairs into clustered listings under a shared product identifier.
Here’s how we built it: shopify.engineering/catalog-…

for us the reason that keeps coming up in enterprise work is the sandbox. clean demos run fine, then the agent touches a real POS export and falls over

this is great deepdive into what a managed harness looks like! some quick thoughts while reading:
- many diff types of agents built on it. doesnt surprise me - a lot of agents look very similar inside these days
- why not use off the shelf? (1) model and provider agnostic), (2) co-build with product teams, (3) own observability stack. I very much agree with points 1 and 3!!! and is something we obviously emphasize at langchain
- "The simplest agent harnesses are truly just a while loop, but when you want to support a wide array of agentic products in production, the responsibility of the harness or framework expands quite a bit" - +100 to this, is why were investing in deepagents so much
- "Using the “sandbox-as-a-tool” paradigm" - the massive trend seems to be going this way (is how deepagents is architected)
- "Supporting non-blocking async agents as the default". we are working on this right now for deepagents! agree is the future
- "The Connectors Service is the standard interface through which agents at Ramp interact with data sources. It centralizes authentication, credential management, access controls, and tool execution behind one API. This allows us to build and maintain integrations once, and reuse them across products." Also very important! and something we're thinking a bunch about for managed deepagents
we run into this all the time with old POS exports and spreadsheet piles. OCR pulls the text out fine, then two sources disagree and the agent just sits there

A lot of professional work around documents can be arbitrarily challenging to automate.
It not only requires deep visual perception/OCR around complex entities (diagrams/charts), but also requires a reasoning trace that can reconcile disparate sources of oftentimes contradictory information.
Check out the example video below around a water loss audit. Solving this task not only requires reading the water loss diagram, but also understand the exact date and subsequent changes in the appendix.
We think hard document extraction tasks as a microcosm for professional work over PDFs. That's why we launched ExtractBenchPro - a benchmark that's challenging even for the latest frontier models (e.g. Astra/Opus).
Even as frontier models with max thinking models push the boundaries of accuracy, there is a massive opportunity to build specialized models that can push the frontiers of cost and latency.
For more info on ExtractBench Pro, check out our blog and the website! llamaindex.ai/blog/introduci…
Site: extractbenchpro.ai
A year of AI subscriptions. What does your company actually own?
Faster output is useful. Turning everyday work into capabilities your company keeps is the bigger opportunity.
Ning Hu × Thomas Luo on using AI vs. owning it.
people are now arguing about whether an agent should be allowed to approve the refund. a year ago the fight was over letting it answer the ticket at all, and nobody brings that one up anymore

ZooWork retweeted

Building an agent is easy now. Handing it to a client is the hard part.
@ZooWorkAI lets you build one by chat (or with Codex or Claude and their SDK) and deliver it as a link, an API, or a Slack or WhatsApp bot.
Your expertise, deployed in minutes: zoowork.ai/?utm_source=x&utm…
🤖 Made with AI

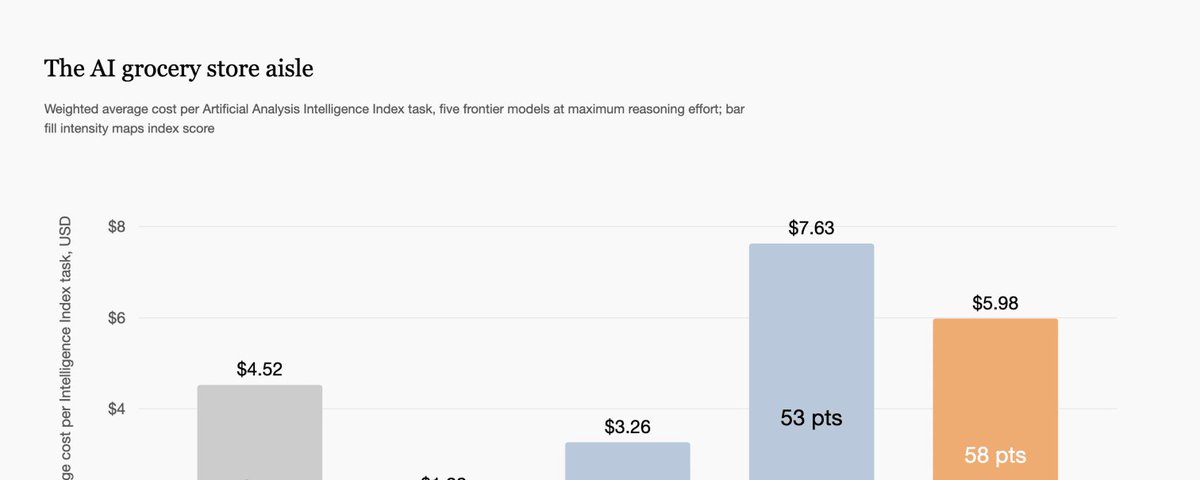
3.8x on cost for five points of intelligence, and on everyday work those five points barely show. we route the boring stuff to the cheaper models, and that routing is where most of our model savings come from

10 years sounds about right from where we sit. getting an agent to run inside someone's actual POS system for months is where most of them stall out.

In retail, your AI agent can look up a customer’s order, but should it also be able to issue a refund?
Here’s how we decide what an agent can see and do:
Data access and permissions belong in the solution design, and the client’s own systems should enforce them.
Human approval is one gate. It does not replace backend authorization.
what's even left for the gateway once routing moves into the harness? just the cost and latency stuff?
router lives in the harness, not a gateway, bc the harness knows the task
blog: langchain.com/blog/how-to-bu…
xitter.cf/neil_xbt/status/210997…

A stylist that knows your closet. A bot that reads every filing before the market opens. How much can you ship between breakfast and 6 PM?
Nov 7 · NYC · with @AITinkerers · $100 in credits per builder · 100 spots
Apply 👇
nyc.aitinkerers.org/p/fashio…
