

AI Agents Product Lead @Box (prev @nianticlabs, @Uber AI). Building and evaluating enterprise agents. Speaking at Kaggle’s Bench Summit Oct 28
San Francisco
Joined October 2010
- Tweets1.2K
- Following471
- Followers389
- Likes1.7K




Pinned Tweet
Excited to share that I will be speaking at Bench Summit next Wed (Oct 28), hosted by @GoogleDeepMind @kaggle!
Here is a sneak peak of my talk. "Builder Bench: Are you overpaying for your Coding Agent?"
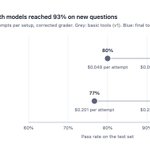
I built Builder Bench and ran 6 Claude models through 23 tasks that mirror how I built my web app. Sonnet was the best value for majority of my test tasks!


We are hosting our first "Bench Summit" to bring together people excited about pushing the frontier of benchmarking, model evals, and more.
Great benchmarks are a gating function for model progress, lots to do here!
Join us in SF: rsvp.withgoogle.com/events/b…
Today is the day! I will be presenting “Builder Bench: Are you overpaying for your coding agent?” today at 1pm. Look forward to meeting you all! 😇

Google DeepMind, Kaggle and Zapier are partnering up to host a first-of-its kind Bench Summit for benchmark creators on October 28th in San Francisco. We’d love for you to be there!
Register your interest to attend and/or speak here!
rsvp.withgoogle.com/events/b…
Join me + leaders across @GoogleDeepMind, @kaggle, @zapier (and many more industry leading companies)!
Including @OfficialLoganK , @osanseviero , @ivanleomk , @DynamicWebPaige & more!
The most surprising thing I found while benchmarking coding agents for PM tasks: the agent is smart enough to bluff, and my LLM judge got fooled when it could not see the evidence. 🧵
The fix was not a smarter judge. It was providing the LLM-as-judge more necessary context. evidence. Once the judge could see the tool results, it passed the truthful run and failed the bluff.

If you use an LLM judge, the question I now ask first: can it see the evidence, or only the agent's story about it?
More on Wed (Oct 28) at Bench Summit by @kaggle and @GoogleDeepMind.
As a sneak peek, you can check out my project here: helenatan.ai/projects/builde…
Back in June this year, I built a whole web app with Claude Code, on the priciest model (Opus 4.8 at that time): front end, back end, data pipeline, database.
I kept running out of tokens. I bought extra credits more than once.
So I asked: could a cheaper model do the same tasks, just as accurately?
That question turned into Builder-Bench: 23 tasks in four types, each one based on a failure I hit while building. Results so far: builder-bench-delta.vercel.a…
I will be presenting the journey of building Builder Bench this Wed (Oct 28) at Bench Summit rsvp.withgoogle.com/events/b….
Hope to see you there!
Hope to see you at my session. Meanwhile, check out my Builder Bench at builder-bench-delta.vercel.a…
Helena Tan | Enterprise AI retweeted

Today we announce 1Password for Agents platform, building with companies @Muse, SpaceX Super Intelligence Grok @Bot, @AnthropicAI’s @Claudeai, @OpenAI, @TownAI, @Browserbase, @Browser_use, @heydana_ai, Instinct, @usekernel, @Perplexity_ai, @tryramp, @Tomo, and @wajo_ai, with more integrations on the way. 🎉
We've heard from so many of our customers who want to use these new personal AI agents to help them get more done, but want more control over what the agent can access with the same trust and ease of use they get when using 1Password directly.
1Password for Agents gives your agents access without giving up your passwords. When an agent reaches a sign-in form, it requests a credential from your vault. If you approve the request, 1Password directly auto-fills the credential in the destination site so the agent can’t see or take possession of the credentials.
The agent gets the task done, but it doesn’t get your passwords..
You stay in control. 1Password for Agents free and optional for personal and family accounts. Unless you opt-in to an agent connector, agents cannot touch your vault.
➡️Learn more: bit.ly/487da6J
Helena Tan | Enterprise AI retweeted

Agent Skills started as an experiment in Claude Code. Many across the industry have come to adopt it, so we at Anthropic found it more fitting to donate it to the @AgenticAIFdn, next to MCP.

We're donating Agent Skills to the Agentic AI Foundation (@AgenticAIFdn), the same foundation we donated MCP to.
Since December 2025, 70+ agent platforms have integrated the standard, including ChatGPT, Cursor, GitHub Copilot, and VS Code.
Here's what that means for you:
A few big takeaways from preparing technical talks for two conferences lately, especially on how to work effectively with AI. 🧵
1/ Start with the narrative.
Before touching slides, I jot down what I want to cover, key ideas to highlight, what I want the audience to walk away with, and the overall flow.
Just get whatever comes to mind onto the page.

2/ Use AI as a critic.
Once I have a narrative, I ask AI for constructive feedback:
* Are the technical concepts clear?
* Is it easy for my target audience to follow?
* How compelling is the storytelling?
I’ve found asking AI to critique my ideas far more effective than asking it to create something from scratch.
4/ Once the narrative is solid, let AI build the slides.
I give it all the relevant assets: conference presentation templates, my blog posts, and interactive sites I’ve built for the project with the graphs and images I already built for the content.
Having the narrative figured out first makes slide creation much easier.
5/ For slide design, specify the objective, not every detail.
For example, I’ll tell AI:
“Make this extremely clear and intuitive for someone with zero context. They should understand what this is about within 20 seconds.”
Then I let AI figure out how to achieve that.
I’ve been pleasantly surprised by the results every time. 💡
Can better tools make a cheaper AI model reliable enough for the job?
I built Scout, a research agent that answers questions about PM job postings, and tested 3 Claude models with 5 versions of its tools. Here is what I found:
Next time: I'd set the bar with the expensive model, keep a separate test set, sort each miss into tool problem or judgment, test every tool change on every model, and compare cost per passing answer.
Interactive site: scout-agent-study.vercel.app
Write-up: helenatan.substack.com/p/can…