
Gemini training @GoogleDeepMind Ex-@Meta FAIR + Prescient Design (@genentech) PhD from @NYUDataScience, previously @Princeton 🐅 angie-chen at 🦋
New York, NY
Joined February 2016
- Tweets146
- Following514
- Followers1.9K
- Likes960


Pinned Tweet
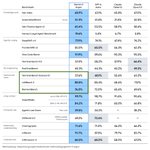
New work w/@sadhikamalladi, @lilyhzhang, @xinyichen2, @QiuyiRichardZ, Rajesh Ranganath, @kchonyc: Contrary to conventional wisdom, RLHF/DPO does *not* produce policies that mostly assign higher likelihood to preferred responses than to less preferred ones.

ALT Two plots showing ranking accuracy of various LLMs on several preference datasets. For 5 of the 6 datasets, all models have ranking accuracy below 60%.


Excited to have contributed to the scientific capabilities of this model!


Announcing Gemini 4 Argon, our new frontier model.
Argon is built to sustain deep reasoning across complex, long-horizon workflows and delivers frontier performance in complex workflows across real-world software engineering, enterprise knowledge work like legal and finance, and cybersecurity defense.
We’re also expanding the model’s output token limit to an industry-leading 1M tokens.
Argon is currently rolling out to a set of trusted cyber defenders in the Fairwind Program, with broader availability as soon as possible.

Angelica Chen retweeted

i was diagnosed with thyroid cancer many years ago purely by chance, because i had to get blood work for my US green card application (thank you, USCIS!). i was in my mid-30’s and was reasonably healthy (or so i believed.) this was shocking and totally unpredictable news to me. thanks to the amazing team of clinicians at NYU Langone, i successfully went through a total thyroidectomy followed by radioactive iodine therapy. but, it was truly the most uncertain and confusing period of my life.
this is when i first realized that no one can opt out of healthcare. being sick isn’t what you choose to or choose not to. it is something that unpredictably happens to all of us at some point for one reason or another. this is why it is a healthcare system that we collectively build and use to support each other at the society level. because it must support everyone, the complexity of creating, maintaining and improving this system is a Herculean effort that calls for all the help in the world.
today, i am announcing @OrtetAI together with my dear co-founders, @keunwoochoi, @HenriDwyer, @elmanmansimov, @causalclaudia and Jeff, to lend our support to improving the health of each and every one of us. Ortet’s goal is to create a technological foundation that will enable health systems to deliver predictably better care to each and every patient. this will only be possible by working closely with all stakeholders in the broader ecosystem, which is enabled in part by Ortet’s close partnership with Thoreau.
Ortet is taking the very first step of a long journey ahead, and at the end of this journey, i strongly believe we would be able to say that Ortet had contributed to building better, more predictable healthcare and thus to improving health of each and every one of us.
see ortet.ai/ for more!

Congratulations @vqctran! 😄 excited to see you RL *entirely new tissues*!! It was an honor to work with you and learn so much from you at GDM ☺️

After 10 incredible years at Google, I've left @GoogleDeepMind to join @thematthewosman and @FabioZB_I at Polyphron as a co-founder and explore the next frontier in my research passions.
Together, we're training frontier models that autonomously explore, understand, and physically reproduce human tissue biology. It's our grand vision to grow tissues realistic enough to match human response to all drugs, and realistic enough to recover organ function when transplanted into living organisms.
Other than the bitter lesson, I think another lesson remains true in the history of ML: the more directly you can optimize your end goal, the better your outcome will be. IMO this is one lesson largely missed in the drug discovery and computational biology space today, and one that Matt and Fabio understood very clearly (and why I joined them on this journey!).
At the heart of our company is one giant RL problem: propose a recipe to grow tissue, sample life itself, reward directly against the functionality of the tissue. If this sounds exciting to you as either an AI or Life scientist, feel free to reach out! We're building the coolest lab in NYC :)
I'll never forget all of the {pretraining, RL, self-improvement} projects I worked on with my brilliant friends at GDM over the years, but I'm even more excited to share the things we discover next!
(p.s. this isn’t the first time i RL’d something based off of similarity, iykyk)
Angelica Chen retweeted

I've been unsettled lately. Reading messages or papers feels like dissociating. Everything seems a bit alien, even if it's completely human. I've had a realization: When our simulations finally exited the Uncanny Valley, they brought the Uncanny with them. nsaphra.net/post/uncanny/

Angelica Chen retweeted

I am starting a blog about deep learning theory and its value to practitioners! First post is about Adam, broken convergence proofs, and what theory can contribute when stuff just works anyways without it. Subscribe on Substack if you like it! undertheassumptions.substack…
🤖 Made with AI

Angelica Chen retweeted
People are increasingly worried that AI tools make us overreliant.
But how do we actually measure this? We introduce Offloading Score, a measure of reliance based on the fraction of cognitive effort offloaded to AI while completing a task.
In a controlled user study, Offloading Score detects increased reliance under time pressure, while several common alternatives do not.
(1/9)


Angelica Chen retweeted
Generalist AIs ace medical exams but fail at hospital operations.
But a small, specialized model created by @lavenderjiang99, @_angie_chen, @kchonyc, @ekoermann, et al beat massive generalists in clinical settings.
nyudatascience.medium.com/ge…
Angelica Chen retweeted

Hiring alert 🚨
If you’re working on LLMs—especially reasoning, RL, or distillation—and want to collaborate on some exciting research, we’d love to hear from you. Apply below.

Our team at GDM is hiring a Student Researcher (SR) next year 🧠
If you’re a PhD student working on LLMs please apply. I’d love to hear from you.
Please fill out this form: forms.gle/bxTEkrDPacn6jSxi6
Angelica Chen retweeted

We built Lang1: a 100M–7B family of models specialized for hospital operations.
After finetuning, Lang1-1B outperforms generalist models up to 671B, transfers to unseen tasks and another hospital, and is more data-efficient.
🧵Why small specialists win in healthcare.

Angelica Chen retweeted

🚨Prompt Curriculum Learning (PCL)
- Efficient LLM RL training algo!
- We investigate factors that affect convergence: bsz, # prompt, # gen, prompt selection
- We propose PCL: lightweight algo that *dynamically selects intermediate-difficulty prompts* using a learned value model

Angelica Chen retweeted

Naomi Saphra is tracing AI outputs back to their origins. In a conversation with @benbenbrubaker, the Harvard researcher explains why an evolutionary lens can help researchers study interpretability. quantamagazine.org/to-unders…

Working with Sadhika was one of the biggest highlights of my PhD and I couldn't be more excited to see her mentor the next generation of brilliant scientists! 🌟💫 Apply to work with her at UCSD!

Excited to share that I will be starting as an Assistant Professor in CSE at UCSD (@ucsd_cse) in Fall 2026! I am currently recruiting PhD students who want to bridge theory and practice in deep learning - see here: cs.princeton.edu/~smalladi/r…
9
1,341
Angelica Chen retweeted

LLMs vs Protein Design Tools: Who Wins?
if you missed them @icmlconf, here's the poster for work led by @_angie_chen & @samuel_stanton_ that answers this question!
Link to paper below 👇

Angelica Chen retweeted

Starting in 30 min at 10am PT!
@nsaphra presents at DLCT:
Sudden Drops in the Loss: Syntax Acquisition, Phase Transitions, and Simplicity Bias in MLMs
Angelica Chen, Ravid Shwartz-Ziv, Kyunghyun Cho, Matthew L. Leavitt, Naomi Saphra
arxiv.org/abs/2309.07311
Zoom 👇


We propose a new synthetic benchmark for highly-constrained biophysical optimization tasks, and propose a new semi-online RL algorithm for training an LLM to iteratively improve its own generations while using very few labels. Come chat with me and @samuel_stanton_ !
1
3
464
Angelica Chen retweeted

🌉 Bridging Offline & Online RL for LLMs 🌉
📝: arxiv.org/abs/2506.21495
New paper shows on verifiable & non-verifiable tasks:
- Online DPO & GRPO give similar performance.
- Semi-online (iterative) DPO with sync every s steps (more efficient!) works very well also.
- Offline DPO is way behind.
- Combining verifiable + non-verifiable works! Cross-transfer gains.
- Recipes for how to make this work.
🧵1/4


