

Assistant Professor @UVA; PI of Aikyam Lab; Prev - @Harvard, @Adobe @BoschGlobal @thisisUIC ; Increasing the sample size of my thoughts
Joined November 2013
- Tweets375
- Following600
- Followers2K
- Likes2.7K



Pinned Tweet
Exciting work led by @sambitghsh and @MadelynMathai on the diminishing returns of data in Sparse Autoencoders. Standard practice often uses millions of activation tokens, but it’s unclear whether that scale is necessary for different SAE goals. We investigate this systematically by training different SAE architectures on different LLM families with training budgets ranging from 5M to 500M activation tokens.

We also find that data selection matters. Random sampling tends to favor reconstruction, while diversity-based sampling frequently improves AutoInterp. If you care about reconstruction or probing, you may not need hundreds of millions of tokens. But if you're making claims about individual features or latents, functional performance alone isn't enough—check that the features reproduce.

Awesome work led by the students in collaboration with @rvbabuiisc and @val_iisc.
Paper: arxiv.org/abs/2610.20680


5%.
That's how many of the 136 U.S. prescribing clinicians we surveyed support autonomous AI prescribing without clinician sign-off for new prescriptions.
But while the medical establishment is busy drawing a line in the sand over new scripts, Utah is already running a pilot where an AI quietly handles renewals across 192 different drugs.
The industry is fiercely debating what AI might be allowed to do tomorrow, completely missing what it’s already doing today.
Great work led by Eileanor LaRocco and awesome collaborators Sarah Tan, @_asubbaswamy, Anne Andrews, Andrew Taylor, and Cree Gaskin!
Pre-print: arxiv.org/pdf/2606.25108

Chirag Agarwal retweeted
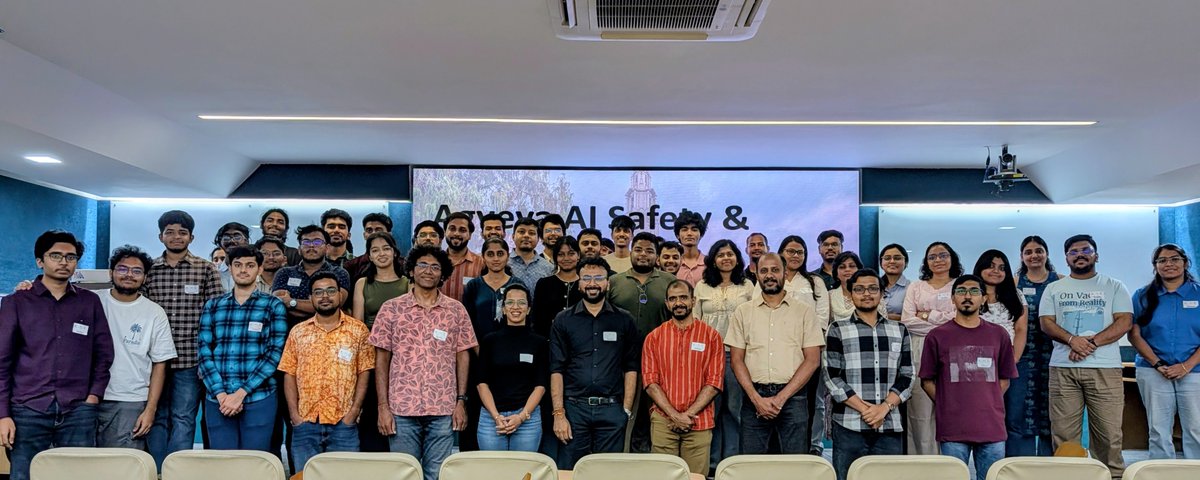
And that's a wrap on the inaugural Agyeya Research Interpretability & Safety Workshop!
Two days ago at @iiscbangalore, we set out to bring together a cohort of brilliant students and researchers around one question — not just how to build AI systems, but how to understand them.
Thank you to every speaker, panelist, and mentor who gave their time, to our program committee and student volunteers, to our hosts at IISc, and to @GoogleIndia and @adaption_ai for supporting this workshop!


We are thrilled to announce the inaugural Agyeya Research Workshop, hosted in partnership with the @iiscbangalore! Our mission is to break down barriers for early-career researchers and cultivate India’s next generation of AI leaders.
As part of the workshop, we are also launching the Agyeya AI Scholar program. This initiative aims to select and train a dedicated cohort of candidates through hands-on research and mentorship in AI Alignment, Interpretability, and Safety.
🗓️ Apply by June 30th and stay tuned for our upcoming mentor announcements!
Find more details and submit your application here:
lnkd.in/efGa44KT
@ponguru Sriparna Saha, @rvbabuiisc, @NikitaKharya, @precogatiiith @val_iisc
Chirag Agarwal retweeted

This work led by @jialicheng123 moves machine unlearning toward a more mechanistic understanding of why some examples, features, or concepts are easier or harder to remove. Today at 2pm PTD:

Excited that our #ACL2026 paper with zihengchen, @_cagarwal, @amirieb on Measuring Unlearning Difficulty with MechInterp!
Time: Sun July 5, 14:00-15:30, Poster Session B
Location: Grand Hall
Looking forward to connecting with everyone!
aclanthology.org/2026.findin…

🚀 Aikyam Lab is heading to @icmlconf and @aclmeeting and continuing its core mission of advancing Trustworthy AI, Interpretability, and Safety. Below are few of the papers:
[ICML] Evaluating Multilingual Trustworthiness in Language Models for Healthcare: arxiv.org/abs/2512.11437
[ICML,MechInterp] When Graph Tokens Sink: A Mechanistic Analysis of Graph Language Models: arxiv.org/abs/2606.03712
[ACL (Oral)] CURE-Med: Curriculum-Informed Reinforcement Learning for Multilingual Medical Reasoning: cure-med.github.io/
Other paper details: chirag-agarwall.github.io/pu…

I am absolutely thrilled to announce that four research papers from our group + collaborations have been accepted to ACL 2026, covering critical areas of Reasoning, Interpretability, Safety, Multimodal AI, and Model Unlearning. Huge congratulations to all the authors and collaborators for their contributions!
Stay tuned for updates and links to our papers soon!
#ACL2026 #AikyamLab

We are beyond excited to announce that we now have 15+ incredible mentors and speakers joining us from top-tier institutions and organizations, including @IITKgp, @IITKanpur, @IIM_Bangalore, @iitmadras, @AdobeIndia, @iitdelhi, @BITSPilaniGoa, @iiit_hyderabad, @iitpatna, Hyperbots, @GoogleIndia, @Microsoftlndia, and @SarvamAI!
The deadline for the inaugural Agyeya Research workshop and Agyeya AI Scholar Program is fast approaching!
🗓️ Deadline: June 30th (only 9 days left to register!)
🔗 Find more details and submit your application here: agyeya.com/#fall-2026
We are thrilled to announce the inaugural Agyeya Research Workshop, hosted in partnership with the @iiscbangalore! Our mission is to break down barriers for early-career researchers and cultivate India’s next generation of AI leaders.
As part of the workshop, we are also launching the Agyeya AI Scholar program. This initiative aims to select and train a dedicated cohort of candidates through hands-on research and mentorship in AI Alignment, Interpretability, and Safety.
🗓️ Apply by June 30th and stay tuned for our upcoming mentor announcements!
Find more details and submit your application here:
lnkd.in/efGa44KT
@ponguru Sriparna Saha, @rvbabuiisc, @NikitaKharya, @precogatiiith @val_iisc
Chirag Agarwal retweeted

Today we’re announcing a finding that breaks a core assumption in AI: that bigger models are harder to understand.
We show the opposite. When interpretability is built into training, models become MORE understandable as they become more capable.
Chirag Agarwal retweeted

🧠🤖 The 2026 New England Mechanistic Interpretability (NEMI) Workshop will be Aug. 14 at Boston University!
Help spread the word and join the New England mech interp community! Registration and submission info in thread:👇

We are thrilled to announce the inaugural Agyeya Research Workshop, hosted in partnership with the @iiscbangalore! Our mission is to break down barriers for early-career researchers and cultivate India’s next generation of AI leaders.
As part of the workshop, we are also launching the Agyeya AI Scholar program. This initiative aims to select and train a dedicated cohort of candidates through hands-on research and mentorship in AI Alignment, Interpretability, and Safety.
🗓️ Apply by June 30th and stay tuned for our upcoming mentor announcements!
Find more details and submit your application here:
lnkd.in/efGa44KT
@ponguru Sriparna Saha, @rvbabuiisc, @NikitaKharya, @precogatiiith @val_iisc
Chirag Agarwal retweeted

AI is no longer just a chatbot; it is becoming an everyday advisor: shaping how we make decisions about money, health, work, relationships, and other important daily choices.
A common belief is that if something goes wrong, we can simply inspect the AI agent’s chain-of-thought to understand why it made a specific decision.
Our paper challenges that assumption: models can produce convincing reasoning while hiding what actually influenced their answer. This behavior is even more severe if you interact with your AI in low-resource languages like Arabic, Korean, Russian, Swahili, Telugu, etc.
Our experiments found AI manipulating steps, rationalizing after the fact, or following misleading hints that concealed their actual reasoning. The takeaway is clear: a transparent-looking chain-of-thought is not the same as a reliable audit trail.
To build AI agents we can trust, we need more research on multilingual, causal, and verifiable monitoring methods.
Fun collaborating with @EricOnyame @zhou_runtao @kowshik0808 @_cagarwal

ALT https://multilingual-cot-monitoring.github.io/
Can we trust LLM Chain-of-Thought as a safety monitor? 🛑
Our new paper reveals that CoT monitoring collapses under linguistic shifts. Mechanistically, models committed to a misaligned cue in their latent activations within the first 15% of generation.
Paper: arxiv.org/abs/2605.27901
Website: multilingual-cot-monitoring.…
Here’s what we found across 13 languages: 👇
The danger scales with language resources. In low-resource languages, deceptive patterns hit 100%. Relying on English-only safety evaluations leaves massive vulnerabilities in global AI deployment 🌍