

PhD @NYU_Courant w/ @SainingXie & @Rob_Fergus | Visiting Researcher @Meta FAIR
NYC
Joined January 2016
- Tweets474
- Following660
- Followers1.1K
- Likes6.3K




Pinned Tweet
Cambrian-1 🪼
Through a vision-centric lens, we study every aspect of building Multimodal LLMs except the LLMs themselves. As a byproduct, we achieve superior performance at the 8B, 13B, 34B scales.
📄arxiv.org/abs/2406.16860
🌎cambrian-mllm.github.io/
🤗huggingface.co/nyu-visionx


Ellis Brown retweeted

We let agent swarms collaborate for 10K hours in simulated agent-owned GitHubs.
Gemini-3.8-flash collaborate the best while gpt-6-astra scores the worst among frontier models tested⁉️
What are the elements of successful agent collaboration at scale? Check World of SWECraft 🧵
Ellis Brown retweeted

My dear friends, I’d like to show you my latest toy project
Introducing Handwired: turn your regular JavaScript code into a neural net!
- no training
- exact outputs vs the JS program
- fully differentiable
All runnable in a browser, without GPU
Ellis Brown retweeted

New #NVIDIA paper: what if robots never had to wait for their own thoughts?
TacitVLA learns to reason in chain-of-thought or subtasks, but its actions never read them.
→ Keeps the gains of reasoning at up to 3.4× lower latency on 4 benchmarks, and tops RoboMME and RMBench 🧵👇

Ellis Brown retweeted

Check out our paper “Neuron Populations Exhibit Divergent Selectivity with Scale” recently selected as a best paper @COLM_conf Sci-FM workshop. We study scaling laws and representational universality at the level of individual neurons.
arxiv.org/abs/2606.03990

2/
🏆 Best Paper
Neuron Populations Exhibit Divergent Selectivity with Scale
@_AmilDravid @yasamanbb Alexei A. Efros @YGandelsman
openreview.net/forum?id=GF4n…
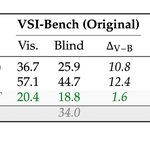
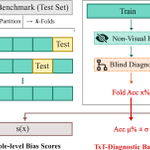
🌶️ if your benchmark can be gamed, it will be... so you’d better game it first!
excited to present Benchmark Designers Should "Train on the Test Set” to Expose Exploitable Non-Visual Shortcuts at #COLM2026 today!
📍 Poster #124 · Grand Ballroom @ 4:40pm

A fun collaboration with @jihanyang13 @shushengyang @rob_fergus @sainingxie at NYU.
Updated paper + full code available at vision-x-nyu.github.io/test-…

Ellis Brown retweeted
Together with @e14fund, we are hosting a bar social at @COLM_conf on Thursday at 8:30pm, featuring our recent project releases: Software World and Context Language Model!
github.com/facebookresearch/…
theagentorg.app/
Looking forward to seeing you tmr! luma.com/e14events-os4c

just landed in SF for COLM, will be around the bay area for the next two weeks 👋🌉 lately I’ve been focused on multimodal pretraining and unified understanding/generation models, hmu if you want to chat!!
Ellis Brown retweeted

‼️The Bitter Lesson for context management: Giving LMs unrestricted control over their context beats human-designed SOTA!
Introducing 🩵Context Language Models (CLMs)🩵
- Natively manage their own context
- Treat context as a file
- Learn policies in CLM weights, no harness

Ellis Brown retweeted

In our Nature paper, we introduce the first superhuman Stratego AI, which we built using general techniques that we developed for RL & test-time compute under imperfect information. 1/N

Ellis Brown retweeted

Why should a generative model be diverse? 👀
If there’s an obviously best answer, why put probability on worse ones?
New paper: a perspective on what diversity is *for*, and an algorithm on post-training for the right amount 🌹.
🧵🔽 [1/12]
Ellis Brown retweeted

In-context learning for robotics is here.
- Long-horizon tasks over 10 minutes long
- Never seen during pre-training
- Prompted with one video, no fine-tuning
We are building intelligence from the foundations up, not from the top down.

Ellis Brown retweeted

Newton-Schulz is what makes Muon work, but it's also a massive pain compared to Adam. *Dion3* makes it ~6x faster and more parallelizable too.
Combines our work on row-filtered gradients, Gram-NS alg, and GPU kernels in one package. Try pip install dion!
arxiv.org/abs/2608.11612
Ellis Brown retweeted

it’s kinda crazy Tim Urban one shot me and like half the people i know into tech and then just fucked off right as it all actually took off
these posts genuinely changed my life, and many others i know. we need a successor


Ellis Brown retweeted

We live in a multimodal world. We see, talk, act, and dream.
Yet most LLMs still start with language pretraining. Why not train them natively with multimodal I/O from scratch?
Because it’s SUPER HARD, adding modalities triggers training instability, design complexity, and often modal competition
So what’s the path forward?
Introducing: Towards Physics of Multimodal Pretraining (junlinhan.github.io/projects…)
We unpack the underlying mechanics of multimodal pretraining across 4 aspects: Knowledge Flow, Modality Synergy, Early Unification, and Recipe.

Ellis Brown retweeted

Progress in AI is driven by approaches that make weaker assumptions, which allows for better scaling
But representation learning has relied on strong assumptions like augmentations, masking, cropping, etc... until now!
🎬 Introducing Temporal Difference in Vision (TDV), a new paradigm for representation learning built on a single assumption: causality
TL;DR:
- We introduce TDV, the first approach to learn good representations without any augmentations, masking, cropping, or pixel-based reconstruction
- TDV matches SOTA recipes like DINO and iBOT on dense spatial tasks
- We show that as data scales, weaker assumptions work better
🧵Thread:

Ellis Brown retweeted

Modern text-to-image models are increasingly powered by large pretrained LLMs.
But there is a curious mismatch: the LLM typically encodes the prompt only once, while the evolving noisy latent states are handled entirely by a newly trained generative backbone.
Can pretrained multimodal prior participate in the denoising process?
Introducing RepFusion. (1/12)
📄 arxiv.org/abs/2606.14700
🌐 xichenpan.com/repfusion/

introducing PaintBench 🎨
a deterministic eval protocol + benchmark for precise visual editing
unlike most generative model evals, no judge model in the loop
see @itskaixu's 🧵⬇️ for technical details. I'll provide more context / commentary about why it's exciting here

thats a wrap for now!
thanks to my collaborators @itskaixu @shrikarhaha @rob_fergus @hhexiy @sainingxie
📄 paper: arxiv.org/abs/2606.00188
💻 code: github.com/PaintBench/PaintB…
🤗 dataset: hf.co/datasets/PaintBench/Pa…
🌐 website: paintbench.github.io
again, check out @itskaixu's technical thread for the full deets !
xitter.cf/itskaixu/status/206182…

Image editing models can put you on the Moon, but can they precisely move a circle right by 50 pixels? 📐
Introducing 🎨PaintBench: a foundational eval of visual editing operations with only one right answer.
The highest-performing model (@NanoBanana 2) reaches only 17.1%.