

Making robots do cool things | Prev: @rai_inst, CS PhD from @BrownUniversity 🤖 Opinions are my own
Boston, MA
Joined July 2019
- Tweets1.2K
- Following871
- Followers1.6K
- Likes1.2K




Pinned Tweet
What’s the easiest way to improve your pretrained diffusion policy?
Swap your Gaussian with a single noise vector that maximizes your downstream reward function!
✅ Keeps original policy weights! frozen
✅ No training new neural networks!
✅ No RL infrastructure needed!

🚨New paper alert 🚨 from @rai_inst!
arxiv.org/abs/2603.15757
🤖You robot policy is actually better than you think!
We find that for a given policy, ALWAYS denoising a single noise vector, which we call a ✨Golden Ticket ✨, leads to consistent performance improvements!
🧵...
Really interesting sim2real approach, and awesome videos!
The whole thread is great, I really like the way feasible holding modes are generated and used to train (via RL + distillation) a whole-body controller optimized for a range of downstream tasks!

Humanoids today mostly manipulate objects with their hands. As humans, we use much more than our hands: we brace boxes against our chests, tuck objects under our arms, and roll balls along our forearms.
Introducing Whole-Body Dexterity (WBD), turning the humanoid body into one large dexterous manipulator.
wholebodydex.com 🧵👇
Love seeing robots do manipulation outdoors, with onboarding sensing! 🥰

Excited to share our latest project on vision-based dynamic manipulation at RAI Institute! We took Spot outside the lab: it now manipulates objects at speed, fully autonomously, using only its onboard sensors and computer. 🧵
Youtube: youtube.com/watch?v=nDIWulWj…
Love the work on few-shot manipulation learning from @Ed__Johns and co. (In particular, I really love InstantPolicy and DINOBot!)
Looking forward to seeing where this goes! 👀

Today we’re out of stealth, and we’ve raised a $40m seed round co-led by @creandum and @usv, to bring Instant Robot Learning to life.
For the past few months, we‘ve been busy building a new company.
Machenta.
This follows results from a new kind of robot foundation model we’ve built, which I’m so excited to share with you today!
Usually, it takes hours/days of data collection and training to teach a robot.
We’ve built a model that learns tasks instantly: one demonstration, no further training.
A model trained entirely in simulation, without a single pixel of real-world data.
A model where teaching robots is so quick and easy, it feels like physical vibe coding.
A model for robots that learn like humans do, from someone like you.
Welcome to the era of Instant Robot Learning.
Thank you @Kathi_Wilhelm, @rebeccakaden, @hkanji, @jonno_evans and all of our angels for your support!
@Machenta_
Learn more: machenta.com/blog/instant-ro…
See below for what you can do with Instant Robot Learning!
This scissor design for a capture glove is really interesting, nicely done!

𝗛𝗼𝘄 𝗶𝘁 𝘄𝗼𝗿𝗸𝘀 ✂️
FOMI is shaped like a pair of scissors. Each handle, its sector gear and its actuation link are a single rigid piece, so contact forces at the gripper travel straight back to your hand. There is no rack-and-pinion in between, no backlash and no return spring, so what you feel comes from the object, not the mechanism.
Two meshed sector gears keep both jaws moving symmetrically, matching a Robotiq 2F-85. Across the whole opening range, the force at your hand stays at roughly half to two-thirds of the gripping force.
The same device also works as a teleoperation controller.
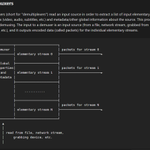
I love the @FFmpeg official documentation, specifically the ASCII diagrams are just amazing!
I'm including images from my dark-mode notes version, since the ASCII doesn't render nicely on X.
Also including a small summary introducing ffmpeg if you're curious to learn more:
---
ffmpeg is a media converter. It takes in an arbitrary number of input media sources and can convert them into output media files, with edits applied along the way like filters. A core idea is that media files are composed of streams, and that ffmpeg is applying operations to streams to do media conversion. The most efficient operations on streams involves directly copying encoded packet streams from input to output, while using encoder/decoders (i.e., a codec) is more computationally expensive but enables e.g., applying filters. Input and output streams can be indexed across sources, so that -map 2:a:3 selects the 3rd input sources 4th (a)udio stream (0 indexing).


The Boston Dynamics Spot legs have always intrigued me, specifically how the knees are actuated!
There is a great patent on this, “US20180172121A1: Screw Actuator for a Legged Robot”. The abstract captures the design quite succinctly (included below).
I got Claude to generate a rough diagram to see how the linear screw actuator can be used to control the lower leg link! I’m also including an image from the patent to compare to the real thing!
“An example robot includes: a leg having an upper leg member and a lower leg member coupled to the upper leg member at a knee joint; a screw actuator disposed within the upper leg member, where the screw actuator has a screw shaft and a nut mounted coaxial to the screw shaft such that the screw shaft is rotatable within the nut; a motor mounted at an upper portion of the upper leg member and coupled to the screw shaft; a carrier coupled and mounted coaxial to the nut such that the nut is disposed at a proximal end of the carrier; and a linkage coupled to the carrier, where the linkage is coupled to the lower leg member at the knee joint.”


Making it easy to shape tactile sensors for arbitrary surface geometries is really important for making these kind of sensors as ubiquitous as cameras!
Where you mount sensors plays a pivotal role in how useful they are for a robot. It is even more true for tactile sensors where contact is required for signal!

Your robot's shape shouldn't limit its sense of touch.
Meet OpenTac: an open ecosystem for custom tactile skins that sense normal + shear forces.
Very excited about this collaborative project! Can’t wait to see what the community builds with it. 🧵👇
opentac.github.io
Your weekly reminder that hillclimbing with real2sim can be a really useful tool for training manipulation policies!

Hard lighting cut our expert-only π0.5 checkpoint's success roughly in half. The same lights cost the full fine-tune nothing.
New from @castorhat: the fine-tuning ablations behind our IROS demo.
Really impressive human data collection demonstration, both from a hardware/software perspective, and artistic talent of the musician!

When in doubt (about MPC vs RL), vibecode it out!

Eric Rosen retweeted

Humanoid learning has a physics bug: make ground contact soft enough for gradients to behave, and your robot learns to run on a floor that acts like a mattress.
@USC /@ETH 's Bundled Contact Gradients takes the opposite bet. Keep stiff, hardware-like contacts in @nvidia Warp. When a foot impact exceeds 400 N, branch into ten nearby states, perturb foot position by 1 cm and velocity by 2 cm/s, simulate two control steps, then average the resulting states before backpropagating. Smooth the GRADIENT, not the ground.
The ablation is brutal. Policies trained with soft contact fell in all five MuJoCo transfers for each of four motions. At the stiff setting, zero falls across all four sets of five trials. Foot-penetration mismatch on Dance dropped from 13.5 mm to 2.9 mm.
Compared with PPO, the method needed over 10x fewer simulated samples. On Fight, transferred tracking error was 13.5 cm versus 34.3 cm. The team also demonstrated zero-shot motions on a real Unitree G1, though hardware success rates aren't quantified.
Caveat: foot-ground motion imitation, tuned bundling and extra GPU memory, not general manipulation.
The engineering takeaway: fix the learning signal at physical discontinuities instead of making physics less physical. @dyumanaditya
bundledcontactgradients.gith…
#HumanoidRobots #RobotLearning
Great writeup on how to optimize your robot arm design for your manipulation tasks.
A great takeaway is that the hardware design becomes especially important when you’re learning from multiple data sources.
What works fine for teleop doesn’t necessarily work well for UMI-style collection (motions may not be realizable), and the reverse is true (complicated data hands can work for UMI but hard to teleop).
Designing your robot for the space of intended tasks and environment constraints + the way you’ll collect your data is a great way to making policy learning easier!


Not only do I agree with @YuXiang_IRVL that you should understand the fundamentals of spatial algebra, but you should also adopt good notation so that it’s easy to do a sequence of operations and immediately infer parent/child relationship!
Notice how @YuXiang_IRVL makes it easy to see how T_{ce} gets constructed via subscripts cancelling out!


For students working on #robotics: Make sure you understand coordinate frames, SE(3) transformations, and robot kinematics.
Robot learning is not just about training models on data. Robot data has physical meaning, and understanding the underlying geometry is essential.
Eric Rosen retweeted

the @RoboPapers episode on SOLE-R1 is out now! we break down our recipe for training a reward model that stays robust to reward hacking as the policy actively optimizes against its zero-shot reward prediction during online RL.
check it out if you're interested in real-world reinforcement learning or general-purpose reward reasoning models!

Reinforcement learning is often seen as key to achieving scalable, highly reliable real-world robot performance, yet it requires good reward functions that can supervise the wide range of tasks that need to be performed. The obvious thing to try would be a large vision-language model (VLM), but these models often fail under common real-world conditions like partial observability and occlusion.
As a solution @Philip_MIT and @thomas_weng propose SOLE-R1, a video-language reasoning model trained to serve as a reward signal for online RL. Given real video, SOLE-R1 will reason over input video frames, generates reasoning traces, and predicts a reward signal. This allows online RL from random initialization on new manipulation tasks.
To learn more, watch Episode 111 of RoboPapers, with @micoolcho and @DJiafei!
Exciting to see how much locomanipulation can be learned from even a single human video, with no task-specific rewards!
Data augmentation and teacher-student distillation with combined RL + BC continues to be a powerful recipe.

I appreciate all forms of collecting human data for robot manipulation (from more remote-actuated approaches like trigger-driven, to no data glove at all).
Finger-driven approaches (either for revolute or prismatic motion like in this UMI design) are a middle-ground I really like!

I've been building my own UMI gripper for the past month. Papers usually skip that initial phase, so I put everything in a blog post. ginokreis.com/blog/dream-umi
Unsure whether to use ArUco tags or an encoder? Unsure how to calibrate the VR controller? Have a read!

Designing reward functions for real-world RL is a serious challenge in learning for manipulation.
Zero/few-shot reward models that “just work” is going to be a huge unlock for the entire field to go beyond behavior cloning!

Excited to share SOLE-R1 is accepted to NeurIPS 2026!
General-purpose reward models are fundamental to unlocking real-world RL.
We show SOLE-R1's zero-shot reward prediction can serve as the SOLE signal for learning over 20 unseen manipulation tasks through online RL (i.e., randomly initialized policies, 0% starting success rate).
This work provides a strong proof of concept: RL with zero-shot dense reward prediction can do more than just increase success/speed for existing tasks; it can enable robots to learn entirely new tasks from scratch, without any demonstrations or ground-truth rewards, starting from zero competence.
Very proud of this project!
Webpage: philip-mit.github.io/sole-r1…
Thank you to my coauthors @thomas_weng, @_ericrosen, @BizaOndrej.
#NeurIPS2026
Eric Rosen retweeted

Took a red-eye from SF, then straight from the airport to #IROS2026 Whew!
I’ll be presenting work with my collaborators @rai_inst at the main conference and giving workshop spotlight talks.
If you’re here, come say hi, let’s talk robots! 🤖
Also, check out our work: planpacts.github.io/