

Pinned Tweet
Today we launched Cura, a 1-trillion-parameter model trained for clinical and administrative healthcare work. With it, actAVA becomes the first U.S. startup to help healthcare organizations customize and own a model at this scale.
Earlier this year we ran χ-BENCH, a study of real healthcare administrative tasks. The best frontier agent we tested, Claude Opus 4.8 with Claude Code, completed 33% of the work. Researchers at Stanford, Johns Hopkins, Yale, and Salesforce AI Research reviewed the study. 33% is not a prompting problem. You don't fix it with better retrieval or a longer system prompt.
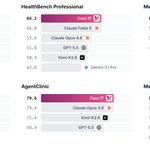
So we trained our own model, on the actual work these organizations do. Across six of the hardest healthcare evaluations, CURA beats Claude Opus and matches Claude Fable, the leading frontier models, at 20 to 100 times lower inference cost. It runs standalone or on KORA, our agent platform, and deploys inside the customer's own VPC. Patient data never leaves their control.
The part we keep coming back to is ownership. Right now, most healthcare organizations rent their intelligence: per-seat tools charge a markup on every model call, and the customer's operational knowledge quietly improves someone else's product. Owning the model flips that. Your data, your standards, your infrastructure, and the model gets better on your work instead of a vendor's.
Healthcare has the data, the domain depth, and the economic pressure to be the first industry that runs on models it controls. That's the bet.
More at actava.ai/cura


The strongest healthcare LLM, custom-built for your enterprise, owned by you🌸
Meet @actAVAai Cura: 1T agentic model trained by recursive self-improvement for long clinical + health admin workflows
Try: actava.ai/cura
Share your use case: $20 credits + early access👇
Our team is headed to NeurIPS 2026. It’s a simulated hospital and a simulated health plan wired together as an RL environment for healthcare agents. Check out the details here: arxiv.org/pdf/2605.16679
Our paper χ-Bench was accepted as a poster at NeurIPS 2026 👉 We built a 𝘀𝗶𝗺𝘂𝗹𝗮𝘁𝗲𝗱 𝗵𝗼𝘀𝗽𝗶𝘁𝗮𝗹 𝗿𝘂𝗻𝗻𝗶𝗻𝗴 𝗮𝗻 𝗘𝗽𝗶𝗰-𝘀𝘁𝘆𝗹𝗲 𝗘𝗛𝗥 𝗮𝗻𝗱 𝗰𝗼𝗻𝗻𝗲𝗰𝘁𝗲𝗱 𝗶𝘁 𝘁𝗼 𝗮 𝘀𝗶𝗺𝘂𝗹𝗮𝘁𝗲𝗱 𝗵𝗲𝗮𝗹𝘁𝗵 𝗽𝗹𝗮𝗻 𝗿𝘂𝗻𝗻𝗶𝗻𝗴 𝗮 𝗨𝗻𝗶𝘁𝗲𝗱𝗛𝗲𝗮𝗹𝘁𝗵𝗰𝗮𝗿𝗲-𝘀𝘁𝘆𝗹𝗲 𝗽𝗮𝘆𝗲𝗿 𝘀𝘁𝗮𝗰𝗸.
It has 20 apps, 87 MCP tools, and a 1,290+ document operations handbook covering medical, insurance and operational policy.
Three things make this hard, and most benchmarks don't test them. Decisions depend on a large library of rules. One task means playing several roles and handing work between them. And many steps are multi-turn conversations, like peer-to-peer reviews and patient outreach, where mistakes can't be undone.
We think similar gaps will show up in other enterprise domains with dense policy, multiple roles and irreversible steps. That's why we built χ-Bench as an RL environment and not just a leaderboard.
Thank you to our 33 co-authors, and to the clinicians and operations experts who helped make the simulation realistic.

3
5
414
ACTAVA retweeted

Excited to be speaking at KDD 2026 about a thesis we’ve been building toward at @actAVAai:
Healthcare AI won’t be won by better chatbots. It will be won by systems that turn real-world workflows into continuously improving agents and models.
At KDD, I’ve shared how we’re building that workflow-to-model platform across three layers:
→ Agent Harness — infrastructure for deploying and learning from long-horizon healthcare workflows
→ CHI-Bench — the first long-horizon benchmark for evaluating agents on realistic, policy-driven healthcare work
→ Cura 1T — our 1-trillion-parameter healthcare foundation model, built for clinical reasoning, healthcare operations, and agentic execution.
The bigger vision is to create an intelligence flywheel:
Workflow execution → feedback → evaluation → training → better models → better execution.
We believe this is how specialized AI compounds inside healthcare enterprises—and ultimately how a new generation of healthcare software gets built.
If you’re thinking about vertical AI, healthcare infrastructure, enterprise agents, or specialized foundation models, I’d love to connect. DM me here.

As part of the OpenAI Partner Network, we look forward to continuing our work with OpenAI for Business to help organizations build, deploy, and scale AI solutions responsibly and effectively.
We’re proud to be part of this next chapter. Learn more:
openai.com/business/partners…


ACTAVA retweeted

Today, we’re adding Inkling to the χ-Bench leaderboard. Inkling passed 6 of 75 tasks, while 58 of 69 failures were workflow or tool-use errors.
• 8.0% PASS@1
• $69.26 per full run
• $11.54 per passed task
Using the χ-Bench failure taxonomy, the 69 unsuccessful trials broke down as:
• 36 workflow-completion failures
• 22 tool-use errors
• 8 clinical-reasoning failures
• 3 stuck or abstained
Take a deeper look: 20 out of 22 tool-use errors are caused by model calling a wrong tool alias that is not provided to it, given it has sufficient tools and could use them to finish the task.
We are also evaluating Opus 5 which is released in this morning, stay tuned!
#ChiBench #AIAgents #LLMEvaluation #HealthcareAI #AIEngineering

We are proud to support Johns Hopkins Medicine as it builds a rigorous foundation for safely scaling agentic AI across healthcare operations.
We are thrilled to share that CHI-Bench has been adopted by Johns Hopkins Medicine as the evaluation test before deployment of agents in hospital environments 🏥 Thanks to Dr. Liu for sharing the work publicly. The full interview is in Healthcare IT News.
CHI-Bench is the work of clinicians and researchers across health systems and AI labs. Thank you to @AlvinLiu_MD, Hank Capps, MD FAAFP, Tianyi Zeng, @StanfordAILab, @zeyu1tang, @sanmikoyejo, @XiangchenSong, @LingjingKong, @kunkzhang, @ericxing, @ffeng01, @huang_biwei, @JimZhiwei, @zixianma02, @hjian42, @FangliGeng, @YuanYuan_MIT, @Charlesyooo1, @qingsongedu, @realhuawei,Yanjie Fu, @yzhao010, @yangji9181, @Recursive_SI: @CaimingXiong, Philip S. Yu for contributions and all the hard work 🥰

2
2
176
Newsweek Asked If Healthcare AI Hit a Reliability Wall. The Answer Is an Architecture Choice. actava.ai/news/newsweek-aske…

ACTAVA retweeted

Exciting to see domain-specific AI like Cura 1T outperforming frontier models on HealthBench Hard & Professional via recursive self-improvement. Trained smarter, not just bigger—delivering frontier performance at 20-100x lower inference cost. Promising path for scalable, deployable medical AI.
@actAVAai @AI_MDPI @SwissCognitive @UofT_TCAIREM
ACTAVA retweeted
Posted the launch yesterday. Today, the part people kept asking about – This is Cura working through a diagnostic case, unedited: "A 26-year-old man falls from a ladder, landing on his outstretched right hand".
Clinicians: pls reply with a case; we'll run it and post the trace.
The strongest healthcare LLM, custom-built for your enterprise, owned by you🌸
Meet @actAVAai Cura: 1T agentic model trained by recursive self-improvement for long clinical + health admin workflows
Try: actava.ai/cura
Share your use case: $20 credits + early access👇
ACTAVA retweeted
Domain-specific models make task execution reliable, more accurate. The biggest value add is actually healthcare organzations can own their model, instead of renting intelligence from frontier labs.

A healthcare-focused model just beat frontier models on some of the hardest medical benchmarks.
Cura 1T:
• Beats GPT-5.5 on HealthBench Hard
• Beats Claude Fable 5 on HealthBench Professional
• Beats Opus 4.8 on AgentClinic
• Beats Opus 4.8 on MedAgentBench-v2
The interesting part?
It wasn't trained conventionally.
It was trained using recursive self-improvement (RSI):
AI trains AI.
AI finds failures.
AI generates new training data.
Humans approve or reject each iteration.
This is interesting because we're starting to see domain-specific models outperform general frontier models in their own territory.

Extremely honored to have Dr. @CaimingXiong on @actAVAai's advisory board!

Meet our Advisors: Dr. Caiming Xiong actava.ai/news/meet-our-advi…
15
26
425
ACTAVA retweeted
99% of AI researchers don’t know. Your HuggingFace datasets can be selected into benchmark shortlist if it tests on open source models. We just made CHI-Bench into the shortlist with other popular benchmarks like GSM8k, SWE-Bench🤗 RT or reply👇if you want to know how!

ACTAVA retweeted
Huge congrats to @Humana's Erius agent taking the #1 spot on CHI-Bench for Prior Auth and 6th for all domains. It outperforms every frontier lab on one of healthcare's hardest workflows.

ACTAVA retweeted
Agents like Claude Code, Codex can sustain hundreds of tool calls and ace coding. So we had 30 of them run a real prior-auth, utilization management and care management case end to end. Best agent still fails 72% of U.S. healthcare workflows
This is CHI (χ)-Bench. 🧵

ALT pass@1 across the three CHI-Bench environments for the nine proprietary harness × model configurations. The per-domain leaders split across all three labs — there is no single “best” agent for healthcare workflows yet.
Introducing CHI-Bench on @huggingface: the world’s first long-horizon healthcare benchmark for AI agents.
75 real healthcare workflows + 20 apps + 200+ MCP tools + 1,290 skills + process / outcome rewards
huggingface.co/datasets/acta…
Any questions, lmk!

actAVA.ai launches CHI-Bench. CHI-Bench is the 1st long-horizon healthcare benchmark for AI agents. If you're building or buying AI for healthcare, this is the test that actually matters — real clinical workflows, not toy demos. U.S. healthcare 🏥 needs this
Agents like Claude Code, Codex can sustain hundreds of tool calls and ace coding. So we had 30 of them run a real prior-auth, utilization management and care management case end to end. Best agent still fails 72% of U.S. healthcare workflows
This is CHI (χ)-Bench. 🧵
ALT pass@1 across the three CHI-Bench environments for the nine proprietary harness × model configurations. The per-domain leaders split across all three labs — there is no single “best” agent for healthcare workflows yet.
3
209
ACTAVA retweeted
Introducing CHI-Bench on @huggingface: the world’s first long-horizon healthcare benchmark for AI agents.
75 real healthcare workflows + 20 apps + 200+ MCP tools + 1,290 skills + process / outcome rewards
huggingface.co/datasets/acta…
Any questions, lmk!
ACTAVA retweeted

The best AI agent (Claude Code + Claude Opus 4.6) passes only 28% of real healthcare workflow tasks. CHI-Bench by @actAVAai @iscreamnearby @HaolinChen11, built with Johns Hopkins, Yale, Stanford, CMU, Oxford and 20+ institutions, was designed to find out exactly how far we are. 🏥 Try it yourself 👉 modelscope.ai/datasets/actav…
Three long-horizon domains tested:
🏥 Prior Authorization: provider intake and PA preparation for new referrals
📋 Utilization Management: full payer review cycle from intake to peer-to-peer
👥 Care Management: chronic disease follow-up, outreach, assessment, care planning
75 tasks + 3 marathon tasks + 23 end-to-end dual-agent scenarios. 20 medical apps via MCP, 1,279-document handbook.
💻 Git: github.com/actava-ai/chi-ben…
🔗 Leaderboard: actava.ai/benchmarks


CHI-Bench is the world's 1st long-horizon healthcare benchmark for AI agents.
If you're building or buying AI for healthcare, this is the test that actually matters — real clinical workflows, not toy demos.
U.S. healthcare needs this. 🏥🔬

The best AI agent (Claude Code + Claude Opus 4.6) passes only 28% of real healthcare workflow tasks. CHI-Bench by @actAVAai @iscreamnearby @HaolinChen11, built with Johns Hopkins, Yale, Stanford, CMU, Oxford and 20+ institutions, was designed to find out exactly how far we are. 🏥 Try it yourself 👉 modelscope.ai/datasets/actav…
Three long-horizon domains tested:
🏥 Prior Authorization: provider intake and PA preparation for new referrals
📋 Utilization Management: full payer review cycle from intake to peer-to-peer
👥 Care Management: chronic disease follow-up, outreach, assessment, care planning
75 tasks + 3 marathon tasks + 23 end-to-end dual-agent scenarios. 20 medical apps via MCP, 1,279-document handbook.
💻 Git: github.com/actava-ai/chi-ben…
🔗 Leaderboard: actava.ai/benchmarks
ACTAVA retweeted

healthcare benchmark, built on harbor!
1/🧵Can AI agents automate U.S. healthcare workflows end to end given just clinician & insurer apps and operations, medical policy library? Introducing CHI-Bench: 75 long-horizon realistic healthcare workflows × 30 frontier agents. Best agent solves only 28% #AIinHealthcare 👇
