

Open-source cycle for self-improving AI agents: analyze → improve → simulate.
Joined July 2025
- Tweets17
- Following17
- Followers8
- Likes0


Simulation caught the edge cases humans missed - escalation rate dropped 21% before we even touched production.

1️⃣
Most AI agents aren’t “bad.”
They’re just trained on vibes instead of data.
2025 is the year we stop tuning by intuition.

2️⃣
If your “optimization strategy” is:
• tweak prompt
• wait
• pray KPIs go up
…you don’t have an optimization strategy. You have a ritual.


🚀 New: Agentune Walkthrough
We just dropped a quick demo showing how Agentune helps you evaluate, stress-test, and improve your AI agents with realistic simulations + data-backed insights.
🔗 GitHub: github.com/SparkBeyond/agent…

Most teams still tune AI agents by intuition.
Agentune Analyze & Improve identifies the conversation patterns that actually move CSAT, resolution, or conversion — and validates changes in simulation before rollout.
Details here: sparkbeyond-staging.webflow.…
🧵1/
🤖 Your AI agent aced the sandbox test.
💥 Then it met real users—and fell apart.
Why? Because real-world performance ≠ prompt engineering.
Meet Agentune — an open-source engine that stress-tests, analyzes & optimizes AI agents like teammates.

10/
🚀 Try Agentune now:
📦 pip install agentune-simulate
🔗 github.com/SparkBeyond/agent…
Open-source. Real-world ready.
Built to help agents actually perform.
#AgentOptimization #LLMops #AIagents

9/
Agentune isn’t just a tool.
It’s a shift in mindset:
From prompt engineers → performance engineers.
From LLM wrappers → agent systems.
From guessing → simulating, analyzing, and iterating.
8/
Coming soon:
🧠 Agentune-Analyze
– Root cause mining
– Driver discovery
– KPI-based insights
Built on SparkBeyond’s tech used to:
– Cut churn 30% for a media giant
– Optimize 600 store locations at Zabka
7/
Most teams still optimize agents by intuition.
But gut-feel = biased.
Anecdotes ≠ scale.
Unmeasured changes hide failure.
Agentune turns ops into science: test, measure, improve—repeat.
6/
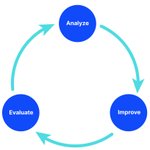
🔬 The Agent Optimization loop:
Analyze → cluster convos, track KPIs, find failure causes
Improve → tweak prompts, tools, policies
Evaluate → test in lab, monitor regressions
Then repeat—with data.
5/
Agentune-Simulate lets you:
✅ Simulate real-world convos
✅ Expose weak spots
✅ Grade performance with intent + KPI metrics
✅ Run locally in seconds
🔗 github.com/SparkBeyond/agent…
4/
Why do great LLMs ship mediocre agents?
Because prompt tuning ≠ performance tuning.
Live environments are messy:
– Partial refunds
– Regional laws
– Budget users
And your agent needs to learn from success and failure.
3/
💥 Just launched: Agentune-Simulate
An open-source engine that stress-tests your agent in a safe lab:
– Synthetic users
– Edge cases
– Realistic multi-turn dialogue
– Clear metrics
Install: pip install agentune-simulate