
Re-inventing databases @ongresinc (Founder). Passionate about Postgres, Cloud, Java and Open Source. Questioning conventional wisdom. For red pill followers.
Madrid, Spain
Joined February 2011
- Tweets10.9K
- Following1.2K
- Followers2.6K
- Likes44.1K



Álvaro Hernández retweeted

your Postgres queue is fine
until someone leaves a transaction open
then SKIP LOCKED stops being a queue and becomes a dead-tuple factory
we measured it at 1k events/s:
- 4.1M dead tuples in 89 minutes
- dequeue latency up ~3000x (!!)
PgQue doesn't have this problem. at all.
consumers never UPDATE or DELETE
they just read.
zero dead tuples -- engine built 20y ago at Skype, and served in large Postgres setups for two decades
now revived in plain SQL to work anywhere
3.5 min, explained (sound on) 👇
Álvaro Hernández retweeted
something spiked 10 minutes ago.
pg_stat_activity already forgot.
pg_ash remembers.
Active Session History for any Postgres -- pure SQL, no extension, no restart. RDS, Cloud SQL, Supabase, AlloyDB, Neon.
in 2.0 (currently rc1):
- redesigned to be easier to use, for humans and agents
- unified AAS metrics
- up to 23x faster reads
tested on PG 14–19rc1
free, Apache 2.0
setup:
\i sql/ash-install.sql
select ash.start('1 second');
github.com/NikolayS/pg_ash -- ASH for Postgres, in pure SQL
Nice to see our recent blog post:
Open-source Citus matches PlanetScale's Neki at 10M QPS on half the data nodes
stackgres.io/blog/open-sourc…
mentioned on Postgres Weekly news (thanks @cooperx86 )
Mentioned next to the link to @PostgresFM's episode where Citus and the benchmark were discussed: postgres.fm/episodes/citus-s… Have you listened to it?

ALT Screenshot of this week's Postgres Weekly News showing both the post and podcast mentioned.
Álvaro Hernández retweeted

Scaling Postgres 439 is released! In this episode, we review two companies battling one another for text search dominance in Postgres, faster vector search with pg_vectorsearch, pushing Citus scaling with query routers and PostgreSQL 19 RC1 is released: scalingpostgres.com/episodes… #Postgres #PostgreSQL

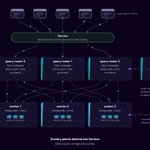
Thank you @CrestonJamison for explaining the concept behind, how they work and the performance results of the Query Routers innovation that we introduced for Citus in StackGres 1.19.
Watch the full episode here: scalingpostgres.com/episodes…
Link to the blog post:
Scaling Citus without limits: announcing Query Routers in StackGres
stackgres.io/blog/scaling-ci…

I have participated in multiple podcasts. This is one of those I enjoy the most. It was fantastic, thank you for inviting me 🙏

New episode: "Citus + StackGres"
Nik and Michael are joined by Álvaro Hernández to discuss sharding Postgres with Citus and StackGres, especially the new query router support that has been added very recently.
🎧️️️ postgres.fm/episodes/citus-s…
📺️️️ youtu.be/by4Gn3MJJOc

ALT Pictures of Álvaro, Nik, and Michael mid-recording, the episode title "Citus plus StackGres", against a pink background with an elephant wearing sunglasses.
Álvaro Hernández retweeted

New episode: "Citus + StackGres"
Nik and Michael are joined by Álvaro Hernández to discuss sharding Postgres with Citus and StackGres, especially the new query router support that has been added very recently.
🎧️️️ postgres.fm/episodes/citus-s…
📺️️️ youtu.be/by4Gn3MJJOc
ALT Pictures of Álvaro, Nik, and Michael mid-recording, the episode title "Citus plus StackGres", against a pink background with an elephant wearing sunglasses.
Since Neki published their benchmark, we new we had to scale Citus on StackGres in a similar way.
And here's what we achieved!
> Open-source Citus matches PlanetScale's Neki at 10M QPS on half the data nodes

ALT Blog post thumbnail, showing two vertical bars: one with 50 data nodes for Neki, another with just 24 data nodes on Citus to achieve in both cases ~ 10M qps
Link to the blog post:
stackgres.io/blog/open-sourc…

Today we learned that a StackGres user (now a customer) has been running StackGres in production since 0.7. Released 7 years ago.
Never had any issue. Never had to ask in our Community Slack. They said with the documentation they solved everything they wanted to.
Love these stories.

How far could you scale Citus? Workers, you can add as many as you want. But at some point, the coordinator may become a bottleneck.
We measured it at above half a million tps. What to do then?
On this blog post we cover Query Routers, an innovation that we have introduced in StackGres to also horizontally scale the query routing layer.
Check it out. It's fully OSS.
stackgres.io/blog/scaling-ci…

Álvaro Hernández retweeted

Postgres 19 delayed for a month. Is this about AI? youtube.com/watch?v=-TiSorR4…

Álvaro Hernández retweeted
Results of my autonomous PG19 scary bughunt in September.
For the first time, I didn't dive into details myself at all, and I revealed that I'm doing it -- AI prepared it all (found a bug, prepared a bug fix, wrote a cover letter, and made many verification loops to achieve a good quality), didn't check myself due to lack of my own capacity, and sent it.
Things went better than expected. Don't try at home though.
(we talked about it in today's live hacking session)
===
About 30 AI-assisted bug reports, each with a proposed fix. 7 were committed, 2 were false positives, and some are still pending. The 7 commits on master:
- Track RI fast-path FK-check batches per subtransaction git.postgresql.org/gitweb/?p…
- Fix REPACK worker startup and shutdown sequences - git.postgresql.org/gitweb/?p…
- Fix RI fast-path permission checks - git.postgresql.org/gitweb/?p…
- Invalidate RI fast-path metadata on operator family changes - git.postgresql.org/gitweb/?p…
- Fix sequence synchronization failure on a concurrent refresh - git.postgresql.org/gitweb/?p…
- Check EXECUTE privilege on functions invoked by the RI fast path - git.postgresql.org/gitweb/?p…
- Refresh autovacuum costs while waiting for parallel workers - git.postgresql.org/gitweb/?p…

live agentic hacking of Postgres – session NOW! join! youtube.com/watch?v=-UaAXJST…

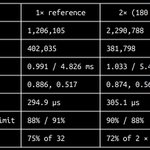
Citus showing almost perfect linear scaling at 2x the size of the below benchmark, serving now 2.3M qps below 1ms p50.
How far should I keep scaling it out?


Is Citus ready for OLTP reads?
- 3 workers @ 64 vcpu each
- 6 query routers @ 32 vcpu each
- pgbench, select only, by PK, warm run, 0.88 hit ratio
Performance:
- qps: 1,206,105
- p50: 0.991 ms
- p99: 4.826 ms
Clarification: query routers are a feature of StackGres- Citus integration, see stackgres.io/doc/latest/admi…
Álvaro Hernández retweeted

A painful part of working with your data has always been that your live data and historical data are stuck in separate systems: the order a customer just placed lives in your database, while their last five years of orders sit in a data lake in S3.
And answering a real question usually needs both at once (is this a normal purchase for them, or should we flag it?), and to do that you had to move the data together first, copying history out of the data lake into your database (or the other way around), because the database couldn’t read it where it lived.
That meant guessing ahead of time which data you’d want, keeping a second copy of it all, building pipelines to move it, and constantly syncing so the two didn’t drift apart. A lot of plumbing, and slow going, all before you could answer one question. And even then, the answers were only as fresh as your last sync.
That now changes with Aurora PostgreSQL, which can call your live data and historical data in S3 together, in a single query. No copying, no pipelines to keep in sync.
And it’s fast, because we’ve built in DuckDB, a popular open source engine that’s really good at reading and analyzing data right where it’s stored. DuckDB reads the open formats like Parquet and Iceberg already sitting in your data lake, so there’s nothing to convert or move.
As folks build AI agents into their apps, the data their agent needs will depend on the task in front of it. Being able to query that specific data live, instead of copying it over just in case, is gonna be a big help for builders. aws.amazon.com/blogs/aws/ama…
