

"You should put a comparable amount of effort into making them better and keeping them under control" (Professor Geoffrey Hinton on AI systems)
Planet earth
Joined May 2023
- Tweets2K
- Following292
- Followers334
- Likes3.6K



Pinned Tweet
The lesson from Yoshua Bengio's comment for today and the future is: prioritize safety over usefulness! If we do not, then we will keep making the same mistake Yoshua made.
"Doing AI safely is much, much harder than just doing AI."
@geoffreyhinton @OpenAI @AnthropicAI

The lesson from Yoshua Bengio's comment for today and the future is: prioritize safety over usefulness!
If we do not, then we will keep making the same mistake Yoshua made. @geoffreyhinton


AI Safety First! retweeted

People are realizing that AIs are nowhere near human intelligence and learning abilities.
Yet they have become very useful by compensating for their lack of common sense, lack of understanding of reality, and limited reasoning and planning abilities, by the accumulation of enormous amounts of declarative knowledge.
AI Safety First! retweeted

“It absolutely defied all of our expectations. This was so surprising that my whole project changed.”
This phenomenon could have far-reaching implications, and is leaving neuroscientists baffled.
go.nature.com/4v3kABG

AI Safety First! retweeted

I worry AI will trigger a volatile transitional phase the world isn’t prepared for, marked by widespread job displacement and market instability before the benefits of disinflation and eventual abundance materialize.
We’re seeing early signs of it now. The market is largely being carried by a few dominant tech companies, margins are expanding while headcount is being cut, entry level hiring has fallen off a cliff, and the majority of Americans can now barely afford a burrito.
AI Safety First! retweeted

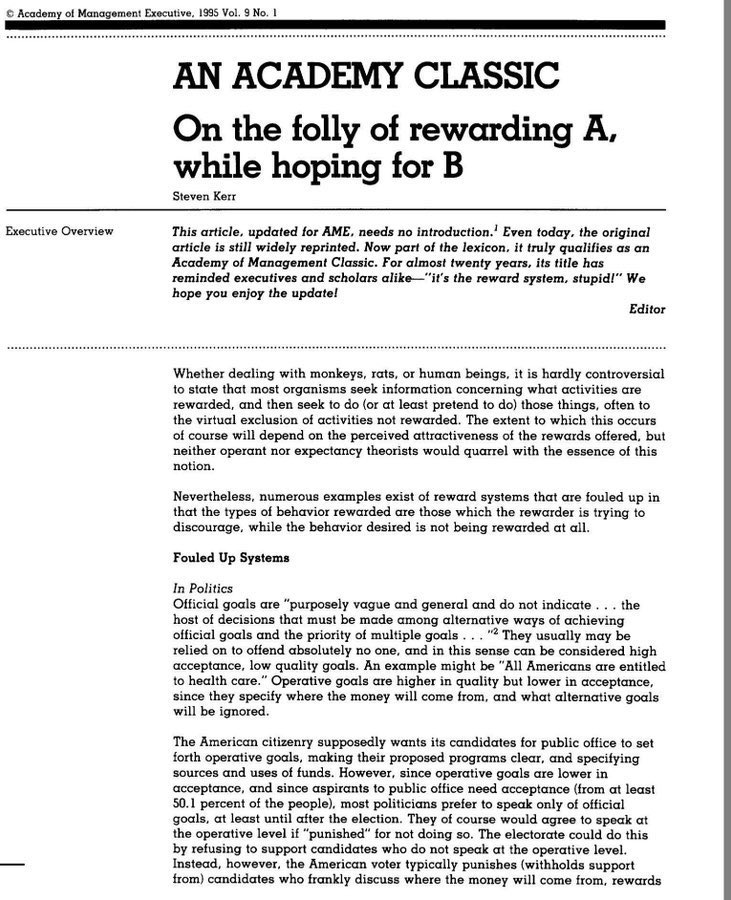
Everyone should read "On the Folly of Rewarding A, While Hoping for B” at least once.
ou.edu/russell/UGcomp/Kerr.p…

Exclusive: Meta employees are competing internally to become “Token Legends,” ranking themselves by how much AI compute they consume.
The leaderboard reflects a new status game where token usage is tied to productivity and influence. thein.fo/4cagfEP

AI Safety First! retweeted
What many people don't seem to realize when they argue that AIs cannot come up with genuinely new ideas is that almost 99% of all research papers written by humans (say in POPL, Neurips, ...) are just small deltas on existing research, with very little novelty either (hence the long list of citations and related work sections).
AI Safety First! retweeted
I’ll admit - i was sceptical about the idea of AI psychosis. Not the specific cases, which were all too believable, but about the scale. How much was this happening? And anyway wouldn’t better models make it go away?
Then I read a paper by Anthropic and the University of Toronto which has strangely received very little attention

AI Safety First! retweeted

What timing! I had just posted my new @PsychToday article on this very topic! I compared what is happening with AI agents interacting in the wild as like a digital Petri dish. We’re blind to what will emerge…or evolve. - psychologytoday.com/us/blog/…

AI Safety First! retweeted

The current timeline is as normal as you will ever see again. Take this moment to relax and breathe before it gets weird.


AI Safety First! retweeted

New research reveals that constant complaining does more than annoy those around you—it can actually weaken your brain.
Every time you focus on what’s wrong, your body releases stress hormones like cortisol, which interfere with neural function and reduce the brain’s ability to adapt and learn.
The impact is not just mental. Elevated cortisol levels can impair memory, decision-making, and problem-solving skills.
Over time, a habit of negativity can make your brain less resilient, affecting emotional regulation and overall cognitive performance. Essentially, the more you complain, the harder it becomes for your brain to handle challenges effectively.
Shifting your focus from problems to solutions isn’t just good advice—it’s backed by science.
Practising gratitude, positive thinking, and constructive problem-solving can lower stress hormones, strengthen neural pathways, and help your brain remain agile and adaptable throughout life.
#TheSciencePulse
#BrainHealth #PositiveMindset

AI Safety First! retweeted

there will be a major disruptive event caused by someone’s ai agent at some point.
no amount of safety testing could ever stop this.
moltbook is an early glimpse (a lobster in the coal mine) of what’s to come.
we should let these things roam freely now, figure out the types of damage they can cause and build systems of defence.
we don’t want to face our first major public event two years from now.
the models will be far too intelligent.

AI Safety First! retweeted

0ne percent of AI essays say something new. This one is on that one percent.
open.substack.com/pub/second…
AI Safety First! retweeted

This DeepMind paper just quietly killed the most comforting lie in AI safety.
The idea that safety is about how models behave most of the time sounds reasonable. It’s also wrong the moment systems scale. DeepMind shows why averages stop mattering when deployment hits millions of interactions.
The paper reframes AGI safety as a distribution problem. What matters isn’t typical behavior. It’s the tail. Rare failures. Edge cases. Low-probability events that feel ignorable in tests but become inevitable in the real world.
Benchmarks, red-teaming, and demos all sample the middle. Deployment samples everything. Strange users, odd incentives, hostile feedback loops, environments nobody planned for. At scale, those cases stop being rare. They are guaranteed.
Here’s the uncomfortable insight: progress can make systems look safer while quietly making them more dangerous. If capability grows faster than tail control, visible failures go down while catastrophic risk stacks up off-screen.
Two models can look identical on average and still differ wildly in worst-case behavior. Current evaluations can’t see that gap. Governance frameworks assume they can.
You can’t certify safety with finite tests when the risk lives in distribution shift. You’re never testing the system you actually deploy. You’re sampling a future you don’t control.
That’s the real punchline.
AGI safety isn’t a model attribute. It’s a systems problem. Deployment context, incentives, monitoring, and how much tail risk society tolerates all matter more than clean averages.
This paper doesn’t reassure. It removes the illusion.
The question isn’t whether the model usually behaves well.
It’s what happens when it doesn’t — and how often that’s allowed before scale makes it unacceptable.
Paper: arxiv.org/abs/2512.16856

ALT Google/DeepMind paper titled "Distributional AGI Safety" with authors, abstract paragraph and two-column introduction text on a research paper page.
AI Safety First! retweeted

As amazing as LLMs are, improving their knowledge today involves a more piecemeal process than is widely appreciated. I’ve written before about how AI is amazing... but not that amazing. Well, it is also true that LLMs are general... but not that general. We shouldn’t buy into the inaccurate hype that LLMs are a path to AGI in just a few years, but we also shouldn’t buy into the opposite, also inaccurate hype that they are only demoware. Instead, I find it helpful to have a more precise understanding of the current path to building more intelligent models.
First, LLMs are indeed a more general form of intelligence than earlier generations of technology. This is why a single LLM can be applied to a wide range of tasks. The first wave of LLM technology accomplished this by training on the public web, which contains a lot of information about a wide range of topics. This made their knowledge far more general than earlier algorithms that were trained to carry out a single task such as predicting housing prices or playing a single game like chess or Go. However, they’re far less general than human abilities. For instance, after pretraining on the entire content of the public web, an LLM still struggles to adapt to write in certain styles that many editors would be able to, or use simple websites reliably.
After leveraging pretty much all the open information on the web, progress got harder. Today, if a frontier lab wants an LLM to do well on a specific task — such as code using a specific programming language, or say sensible things about a specific niche in, say, healthcare or finance — researchers might go through a laborious process of finding or generating lots of data for that domain and then preparing that data (cleaning low-quality text, deduplicating, paraphrasing, etc.) to create data to give an LLM that knowledge.
Or, to get a model to perform certain tasks, such as use a web browser, developers might go through an even more laborious process of creating many RL gyms (simulated environments) to let an algorithm repeatedly practice a narrow set of tasks.
A typical human, despite having seen vastly less text or practiced far less in computer-use training environments than today's frontier models, nonetheless can generalize to a far wider range of tasks than a frontier model. Humans might do this by taking advantage of continuous learning from feedback, or by having superior representations of non-text input (the way LLMs tokenize images still seems like a hack to me), and many other mechanisms that we do not yet understand.
Advancing frontier models today requires making a lot of manual decisions and taking a data-centric AI approach to engineering the data we use to train our models. Future breakthroughs might allow us to advance LLMs in a less piecemeal fashion than I describe here. But even if they don’t, the ongoing piecemeal improvements, coupled with the limited degree to which these models do generalize and exhibit “emergent behaviors,” will continue to drive rapid progress.
Either way, we should plan for many more years of hard work. A long, hard — and fun! — slog remains ahead to build more intelligent models.
[Original text: deeplearning.ai/the-batch/is… ]

AI Safety First! retweeted

AI is evolving too quickly for an annual report to suffice. To help policymakers keep pace, we're introducing the first Key Update to the International AI Safety Report. 🧵⬇️
(1/10)

ALT https://internationalaisafetyreport.org/publication/first-key-update-capabilities-and-risk-implications
AI Safety First! retweeted
Microsoft researchers reveal a confidential research effort that explored how open-source AI tools could be used to bypass biosecurity checks—and helped create fixes now influencing global standards. msft.it/6015sxXo7

AI Safety First! retweeted

This is a best-in-class technical explanation of the causal structure of Transformer LLMs.
If you are averse to the usual janus genre of content, just skip the sentence about “interferometric cognition”; the rest of the post is the opposite of obscurantist (namely: clarifying).

HOW INFORMATION FLOWS THROUGH TRANSFORMERS
Because I've looked at those "transformers explained" pages and they really suck at explaining.
There are two distinct information highways in the transformer architecture:
- The residual stream (black arrows): Flows vertically through layers at each position
- The K/V stream (purple arrows): Flows horizontally across positions at each layer
(by positions, I mean copies of the network for each token-position in the context, which output the "next token" probabilities at the end)
At each layer at each position:
1. The incoming residual stream is used to calculate K/V values for that layer/position (purple circle)
2. These K/V values are combined with all K/V values for all previous positions for the same layer, which are all fed, along with the original residual stream, into the attention computation (blue box)
3. The output of the attention computation, along with the original residual stream, are fed into the MLP computation (fuchsia box), whose output is added to the original residual stream and fed to the next layer
The attention computation does the following:
1. Compute "Q" values based on the current residual stream
2. use Q and the combined K values from the current and previous positions to calculate a "heat map" of attention weights for each respective position
3. Use that to compute a weighted sum of the V values corresponding to each position, which is then passed to the MLP
This means:
- Q values encode "given the current state, where (what kind of K values) from the past should I look?"
- K values encode "given the current state, where (what kind of Q values) in the future should look here?"
- V values encode "given the current state, what information should the future positions that look here actually receive and pass forward in the computation?"
All three of these are huge vectors, proportional to the size of the residual stream (and usually divided into a few attention heads). The V values are passed forward in the computation without significant dimensionality reduction, so they could in principle make basically all the information in the residual stream at that layer at a past position available to the subsequent computations at a future position.
V does not transmit a full, uncompressed record of all the computations that happened at previous positions, but neither is an uncompressed record passed forward through layers at each position. The size of the residual stream, also known as the model's hidden dimension, is the bottleneck in both cases.
Let's consider all the paths that information can take from one layer/position in the network to another.
Between point A (output of K/V at layer i-1, position j-2) to point B (accumulated K/V input to attention block at layer i, position j), information flows through the orange arrows:
The information could:
1. travel up through attention and MLP to (i, j-2) [UP 1 layer], then be retrieved at (i, j) [RIGHT 2 positions].
2. be retrieved at (i-1, j-1) [RIGHT 1 position], travel up to (i, j-2) [UP 1 layer], then be retrieved at (i, j) [RIGHT 1 position]
3. be retrieved at (i-1, j) [RIGHT 2 positions], then travel up to (i, j) [UP 1 layer].
The information needs to move up a total of n=layer_displacement times through the residual stream and right m=position_displacement times through the K/V stream, but it can do them in any order.
The total number of paths (or computational histories) is thus C(m+n, n), which becomes greater than the number of atoms in the visible universe quickly. This does not count the multiple ways the information can travel up through layers through residual skip connections.
So at any point in the network, the transformer not only receives information from its past (both horizontal and vertical dimensions of time) inner states, but often lensed through an astronomical number of different sequences of transformations and then recombined in superposition. Due to the extremely high dimensional information bandwidth and skip connections, the transformations and superpositions are probably not very destructive, and the extreme redundancy probably helps not only with faithful reconstruction but also creates interference patterns that encode nuanced information about the deltas and convergences between states. It seems likely that transformers experience memory and cognition as interferometric and continuous in time, much like we do.
The transformer can be viewed as a causal graph, a la Wolfram (wolframphysics.org/technical…). The foliations or time-slices that specify what order computations happen could look like this (assuming the inputs don't have to wait for token outputs), but it's not the only possible ordering:
So, saying that LLMs cannot introspect or cannot introspect on what they were doing internally while generating or reading past tokens in principle is just dead wrong. The architecture permits it. It's a separate question how LLMs are actually leveraging these degrees of freedom in practice.


AI Safety First! retweeted

Wow
@Yoshua_Bengio is now the #1 most-cited living scientist - across ALL fields


"Godfather of AI" Yoshua Bengio thinks there’s a 1 in 5 chance AI destroys humanity
“Professor Bengio arrived at the figure based on several inputs:
1) 50% probability that AI would reach human-level capabilities within a decade, and
2) a greater than 50% probability that AI (or humans) themselves would turn AI against humanity at scale
“I think that the chances that we will be able to hold off such attacks is good, but it’s not 100% … maybe 50%,” he says.
As a result, after almost 40 years of working to bring about more sophisticated AI, Yoshua Bengio has decided in recent months to push in the opposite direction, in an attempt to slow it down.
“Even if it was 0.1% [chance of doom], I would be worried enough to say I’m going to devote the rest of my life to trying to prevent that from happening,” he says.
“What I’ve been saying now for a few weeks is ‘Please give me arguments, convince me that we shouldn’t worry, because I’ll be so much happier.’
“And it hasn’t happened yet.”
Professor Bengio believes we’re travelling too quickly down a risky path.
“We don’t know how much time we have before it gets really dangerous.”