
To believe in something is to disbelieve in something
Joined June 2024
- Tweets134
- Following554
- Followers25
- Likes137



Pinned Tweet
Introducing TTRV: Test-Time Reinforcement Learning for Vision-Language Models 🧠📸
Most RL methods need labeled data — but humans learn directly from experience.
We bring that ability to VLMs.
🚀 TTRV adapts models on-the-fly at inference, with no labels.


Akshit Singh retweeted

I wrote a blog post detailing the writing approach I took while working on my recent paper: sophielwang.com/blog/paper-w…
I describe the behind the scenes for how this paper came to be, why and how I storyboarded figures before running experiments, and some figure design tips! :)


Can “chicken” make a base model reason? 🐔
Yes!
Why? With the right first tokens, base models can match RL in reasoning. We trace this to learned training data associations and use a simple data edit to make “chicken” elicit reasoning too.
blog: sophielwang.com/cues
Akshit Singh retweeted

Fun fact about (some) AI researchers / academics: the more senior you get, the more convinced you become that every new AI idea is something you already invented 20 years ago. Or, even better: wait until something actually works and then try convincing everyone that this is exactly what you’ve been saying all along.
I was at a conference where a speaker was presenting their research. One academic stood up and said: what you’re doing is actually something I did a few years ago. The speaker was very polite and said thank you for pointing this out.
Then a second researcher stood up and said, well I already did it this 10 years ago, you should cite my work. Then a third person said, I already did all of this about 20 years ago.
It was the funniest thing ever.
New paper: Architectural Sampling 🧵
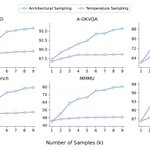
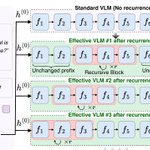
Test-time scaling samples many answers from a frozen model. But with temperature, every answer runs the exact same computation.
What if diversity came from how the model computes, not just the final token draw?
It also helps models learn from themselves.
Swapping temperature rollouts for architectural ones in label-free test-time RL (TTRV) improves accuracy on every benchmark we tried, e.g. +15.3 on A-OKVQA with Qwen3.5-VL-2B.
Huge thanks to my amazing co-authors: @shyam__marjit @WeiLinCV @leokarlin @jmie_mirza
📄 Paper: arxiv.org/abs/2610.01687
🌐 Project: akshit21112002.github.io/Arc…
💻 Code: github.com/Akshit21112002/Ar…
Working on test-time scaling or VLMs? Would love to chat
Akshit Singh retweeted

Presenting today @CVPR Poster 422 11:45-13:45:
TTRV: Test-Time Reinforcement Learning for Vision Language Models
Can a VLM improve itself at test time without any labels or external supervision?
We show that the answer is YES. 👇
Poster 422 11:45-13:45
akshit21112002.github.io/ttr…


Akshit Singh retweeted

Tomorrow I will travel to Denver, CO for #CVPR2026 🏔️🤖🇺🇸
I'm incredibly excited to dive into the latest research, catch up with old friends, and make new connections.
If you are attending and want to chat about Computer Vision, Multi-modal LLMs, or just grab a coffee, let's connect! Please also step by our 3 posters:
"VisualOverload: Visual Understanding of VLMs in Really Dense Scenes"
Paul Gavrikov, Wei Lin, Jehanzeb Mirza, Soumya Jahagirdar, Muhammad Huzaifa, Sivan Doveh, Serena Yeung-Levy, James Glass, Hilde Kuehne
📍 Main Poster Session 6 on June 7th, 15:30 PM - 17:30 PM, Poster 431 (ExHall A)
"TTRV: Test-Time Reinforcement Learning for Vision Language Models"
Akshit Singh, Shyam Marjit, Wei Lin, Paul Gavrikov, Serena Yeung-Levy, Hilde Kuehne, Rogerio Feris, Sivan Doveh, James Glass, Jehanzeb Mirza
📍 Main Poster Session 5 on June 7th, 11:45 AM - 13:45 PM Poster 422 (ExHall F)
"When Negation Is a Geometry Problem in Vision-Language Models"
Fawaz Sammani, Tzoulio Chamiti, Paul Gavrikov, Nikos Deligiannis
📍 MAR Workshop Poster Session June 4th, 11:50 AM - 12:30 PM, Poster 179
See you in Denver!

Akshit Singh retweeted

Outstanding researchers excel at the art of finding problems right at the edge of our understanding — that can actually be solved.
Akshit Singh retweeted

New Anthropic research: Natural Language Autoencoders.
Models like Claude talk in words but think in numbers. The numbers—called activations—encode Claude’s thoughts, but not in a language we can read.
Here, we train Claude to translate its activations into human-readable text.
Akshit Singh retweeted

New paper! Subliminal learning—transferring hidden signals between language models—is more powerful than we thought. By biasing the teacher with a steering vector instead of a prompt, we achieve strong, consistent transfer, which we use to study its mechanisms. w/@GeorgeMorgulis

Akshit Singh retweeted

AI research used to be in a unique position.
Unlike biology or materials science, it was not extremely resource-intensive: 1-2 GPUs could still support top-venue-level work.
Unlike math or theoretical physics, it was also not purely intelligence-intensive. (1/3)
Akshit Singh retweeted

Simply adding Gaussian noise to LLMs (one step—no iterations, no learning rate, no gradients) and ensembling them can achieve performance comparable to or even better than standard GRPO/PPO on math reasoning, coding, writing, and chemistry tasks. We call this algorithm RandOpt.
To verify that this is not limited to specific models, we tested it on Qwen, Llama, OLMo3, and VLMs.
What's behind this? We find that in the Gaussian search neighborhood around pretrained LLMs, diverse task experts are densely distributed — a regime we term Neural Thickets.
Paper: arxiv.org/pdf/2603.12228
Code: github.com/sunrainyg/RandOpt
Website: thickets.mit.edu

Akshit Singh retweeted
We added short-term visual memory + long-term text memory to pi models. 🤖
Enables robots to:
- complete tasks up to 15 min long
- cook grilled cheese while keeping track of time
- adapt in-context
Paper & videos: pi.website/memory