
Maia @ Microsoft! ex DeepSpeed, @MSFTDeepSpeed, Father, PhD, Wanna-be Professor, Technology Enthusiast.
Richardson, TX
Joined September 2011
- Tweets482
- Following543
- Followers260
- Likes868




Pinned Tweet
Very excited to lead this effort at Microsoft! My first release as a manager. Feeling proud of myself and my team who worked very hard to make this happen in a short amount of time :-)

Introducing Mixtral, Phi2, Falcon, and Qwen support in #DeepSpeed-FastGen!
- Up to 2.5x faster LLM inference
- Optimized SplitFuse and token sampling
- Exciting new features like RESTful API and more!
For more details: github.com/microsoft/DeepSpe…
#DeepSpeeed #AI

Ammar Ahmad Awan retweeted

WTF?

We asked GPT-6 Astra to edit Qwen3.5-0.8B weights to improve math.
It directly changed only 0.016% of weights, fixing 0.8B's reasoning loops & improving math up to 6x and even instruction following 3x, without gradients or training.
We call this Weight-Space Programming: frontier LLMs can now natively read/write neural network weights! 🧵
Blog: rikiyat.github.io/blog/weigh…

Readers added context they thought people might want to know
LLM was given weights explicitly as text in prompt and used code/forward passes (per authors' logs) to ablate Qwen looping direction, a known thinking-mode issue per model card. Primarily fixed repetition in that mode, not general 'natively' improving weights/math.
rikiyat.github.io/blog/weight-sp…
github.com/RikiyaT/lm_und…
huggingface.co/Qwen/Qwen3.5-0…
huggingface.co/RikiyaT/Qwen3.…
Ammar Ahmad Awan retweeted

Today we (meta) released the most capable US open-weight models. Meta's production inference also runs on SGLang. The best open model on the best open-source inference engine. Try it now 👇

Muse Spark Open is built to plan, act, and use computer across agentic tasks for life and work.
You can now build a powerful personal AI agent with an open stack, and SGLang to make it:
- Ultra-responsive with NVFP4 MegaMoE and sequence parallelism
- Faster for agentic and coding tasks with our DFlash2 draft model
- Customizable for specialized use cases via fine-tuning with Miles
We’re incredibly proud to have made this possible with @AIatMeta, @NVIDIAAI, @AIatAMD, @intel, and @radixark!


Ammar Ahmad Awan retweeted

🧵1/ New release from @Snowflake AI Research:
Shift Parallelism is a new LLM inference technique built on top of vLLM, released through ArcticInference.
It dramatically improves latency while preserving high throughput. Here’s what it looks like in action 👇

Ammar Ahmad Awan retweeted

(1/n)
Training LLMs can be hindered by out-of-memory, scaling batch size, and seq length. Add one line to boost multi-GPU training throughput by 20% and reduce memory usage by 60%. Introducing Liger-Kernel: Efficient Triton Kernels for LLM Training.
github.com/linkedin/Liger-Ke…

Ammar Ahmad Awan retweeted

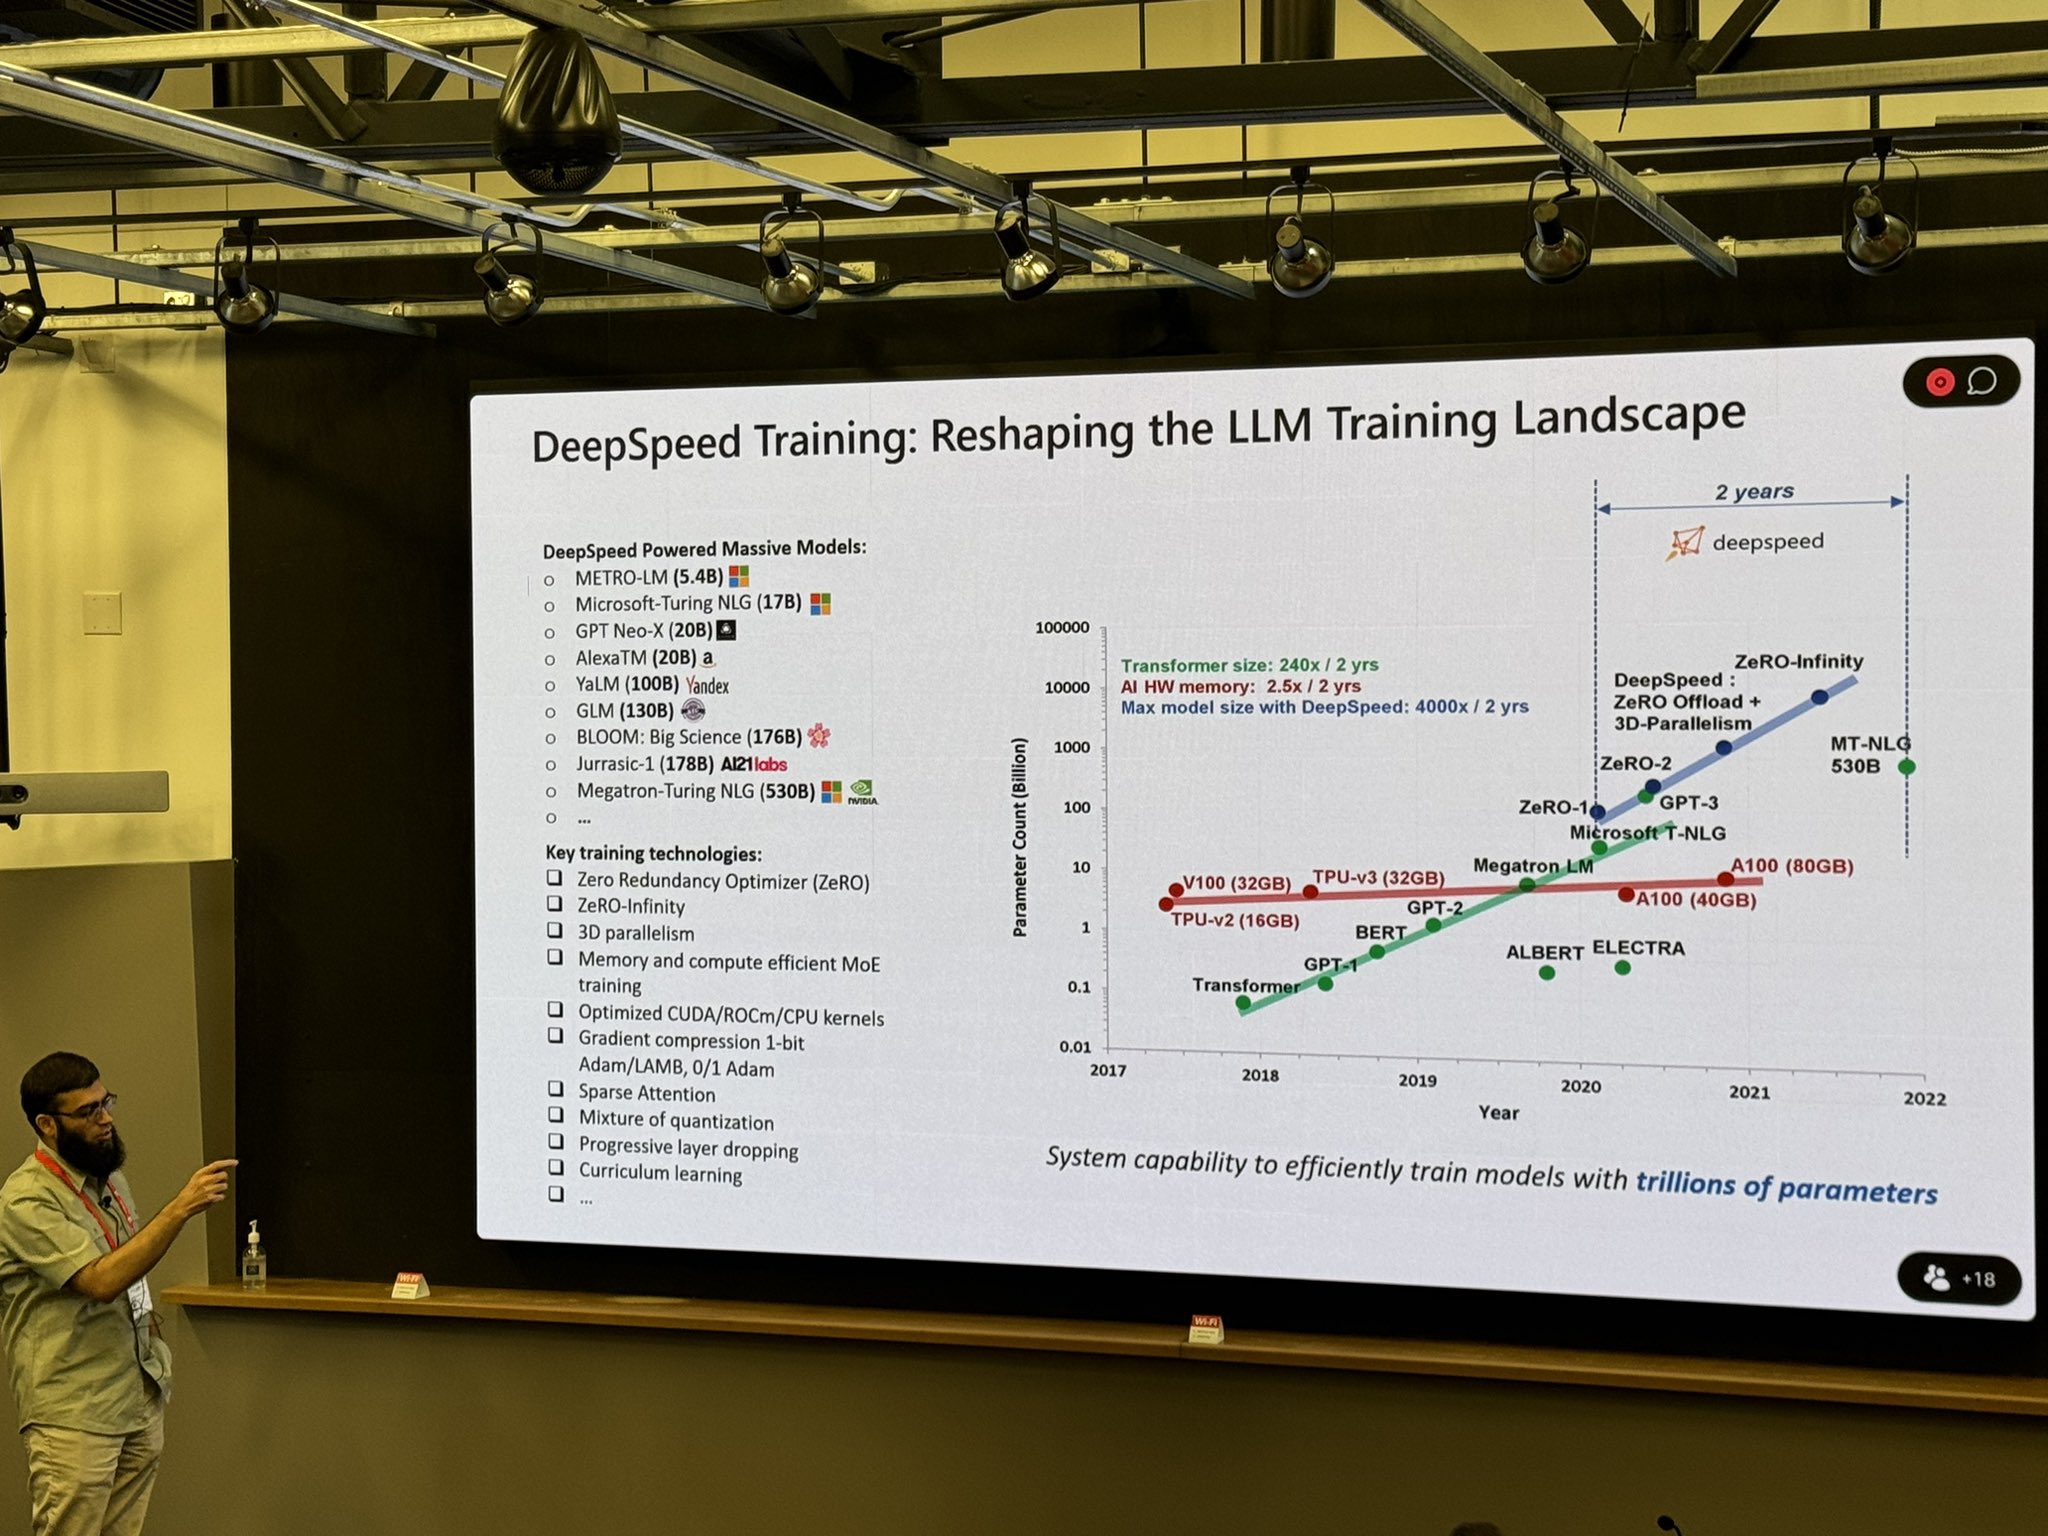
オハイオ州立大学で開かれたイベントで、メンバーのAmmar Ahmad Awan @ammar_awan が、DeepSpeedの最適化に関する講演を行いました!
オハイオ州立大学は分散並列処理の研究で広く知られており、DeepSpeedチームにも出身者が多くいます。
Great to see the amazing DeepSpeed optimizations from @Guanhua_Wang_, Heyang Qin, @toh_tana, @QuentinAnthon15, and @samadejacobs presented by @ammar_awan at MUG '24.
Felt great to be back at OSU. Thank you @dhabalkpanda, @harisubramoni for inviting me and enabling me to share the awesome DeepSpeed work with @mvapich team!
Great to see the amazing DeepSpeed optimizations from @Guanhua_Wang_, Heyang Qin, @toh_tana, @QuentinAnthon15, and @samadejacobs presented by @ammar_awan at MUG '24.
Ammar Ahmad Awan retweeted

Dr. Ammar Ahmad Awan from Microsoft DeepSpeed giving a presentation at MUG '24 over Trillion-parameter LLMs and optimization with MVAPICH.
@OSUengineering @Microsoft
@OhTechCo @mvapich
@MSFTDeepSpeed
@MSFTDeepSpeedJP #MUG24 #MPI #AI #LLM #DeepSpeed



Ammar Ahmad Awan retweeted

Announcing that DeepSpeed now runs natively on Windows. This exciting combination unlocks DeepSpeed optimizations to Windows users and empowers more people and organizations with AI innovations.
- HF Inference & Finetuning
- LoRA
- CPU Offload
Blog: shorturl.at/a7TF8

Ammar Ahmad Awan retweeted

Brought me to tears. She’s so respected by her peers. What an achievement. Academic excellence and ethical leadership. Asna Tabassum, we salute you.
Ammar Ahmad Awan retweeted

The phi-3 family is the work of an amazing team over many months, kudos to everyone!

Ammar Ahmad Awan retweeted
phi-3 is here, and it's ... good :-).
I made a quick short demo to give you a feel of what phi-3-mini (3.8B) can do. Stay tuned for the open weights release and more announcements tomorrow morning!
(And ofc this wouldn't be complete without the usual table of benchmarks!)

Ammar Ahmad Awan retweeted

If you're trying to run MoE Mixtral-8x7b under @MSFTDeepSpeed it's likely to hang on the first forward
The solution is here github.com/microsoft/DeepSpe…
and you need deepspeed>=0.13.0
Thanks to Masahiro Tanaka for the fix.
edit: looks like someone codified it even better:
github.com/hiyouga/LLaMA-Fac…

Ammar Ahmad Awan retweeted
* Language is low bandwidth: less than 12 bytes/second. A person can read 270 words/minutes, or 4.5 words/second, which is 12 bytes/s (assuming 2 bytes per token and 0.75 words per token). A modern LLM is typically trained with 1x10^13 two-byte tokens, which is 2x10^13 bytes. This would take about 100,000 years for a person to read (at 12 hours a day).
* Vision is much higher bandwidth: about 20MB/s. Each of the two optical nerves has 1 million nerve fibers, each carrying about 10 bytes per second. A 4 year-old child has been awake a total 16,000 hours, which translates into 1x10^15 bytes.
In other words:
- The data bandwidth of visual perception is roughly 16 million times higher than the data bandwidth of written (or spoken) language.
- In a mere 4 years, a child has seen 50 times more data than the biggest LLMs trained on all the text publicly available on the internet.
This tells us three things:
1. Yes, text is redundant, and visual signals in the optical nerves are even more redundant (despite being 100x compressed versions of the photoreceptor outputs in the retina). But redundancy in data is *precisely* what we need for Self-Supervised Learning to capture the structure of the data. The more redundancy, the better for SSL.
2. Most of human knowledge (and almost all of animal knowledge) comes from our sensory experience of the physical world. Language is the icing on the cake. We need the cake to support the icing.
3. There is *absolutely no way in hell* we will ever reach human-level AI without getting machines to learn from high-bandwidth sensory inputs, such as vision.
Yes, humans can get smart without vision, even pretty smart without vision and audition. But not without touch. Touch is pretty high bandwidth, too.

Ammar Ahmad Awan retweeted
#DeepSpeed joins forces with @Sydney_Uni to unveil an exciting tech #FP6. Just supply your FP16 models, and we deliver:
🚀 1.5x performance boost for #LLMs serving on #GPUs
🚀 Innovative (4+2)-bit system design
🚀 Quality-preserving quantization
link: github.com/microsoft/DeepSpe…

Ammar Ahmad Awan retweeted
The other news is the introduction of @MSFTDeepSpeed Meetups, which will be conducted once about every 3 months.
The inaugural one will be on Feb 12 6:00 PM - 8:00 PM at Redmond Reactor
developer.microsoft.com/en-u…
Quote: "This will be the first ever meetup for the DeepSpeed open-source project. We will have an overview of DeepSpeed, latest features and release, and deeper dive talks on particular new/important features and use cases."
I think they plan to organize it at other locales as well, such as Seattle and San Francisco.
I hope they record those!
Ammar Ahmad Awan retweeted
Thanks @StasBekman! DeepSpeed team is hiring for various engineering and research roles! Come join us and steer the future of large scale AI training and inference.

Finally I'm being told MSFT allocated more engineering positions on the @MSFTDeepSpeed team.
As a long time Deepspeed user for the first few years I had to fix many bugs myself since the team was so small, and finally the time has come where I can just report them and the growing Deepspeed team is there to fix them and add new features quickly.
So if you're a good ML engineer I'm selfishly interested for you to join the Deepspeed team as it'll help me and numerous other Deepspeed users to get the best scalability and speed of LLM training and inference.
So if it resonates please head here:
- Principal Software Engineer jobs.careers.microsoft.com/g…
- Senior Software Engineer
jobs.careers.microsoft.com/g…
edit: actually I see there are 6 openings!
jobs.careers.microsoft.com/g…
Thank you!
Ammar Ahmad Awan retweeted
Are you a #DeepSpeed user, fan, contributor, and/or advocate? Are you interested in meeting people behind @MSFTDeepSpeed tech? Are you interested in #AI? If yes, come and meet the team at our first in-person meetup in the Seattle area!
Register here:
developer.microsoft.com/reac…