

I reverse engineer things, find vulnerabilities and write FOSS under pseudonyms. Local LLM entusiast, I do experiments with the RTX 6000 Pro, CMP HX170, M5 Max
Italy
Joined August 2026
- Tweets175
- Following446
- Followers26
- Likes218


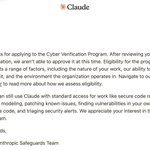


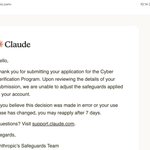


US corporations stopped paying bug bounties and US pre-IPO companies behave like this.
Then people be like: "Oooh why are you so mean and you drop 0-days on Friday afternoon, that's so irresponsible".
IDK YOU TELL ME

New Deepseek V4.1 Flash 1017 recipe (on 1x RTX 6000 Pro + 4x CMP 170HX)
github.com/anoane/09-deepsee…

I made a fork for exllamav3 to support Deepseek V4.1 Flash (using your 3.0bpw exl3 quant), it's running much faster than vLLM, and it has some goodies for frankenstein setups with mixed GPUs and offload
Fork github.com/anoane/exllamav3-…
Recipe github.com/anoane/06-deepsee…
Deepseek V4.1 Flash support for exllamav3 out soon 🚀🚀🚀
Final checks then #PR

EXL3 is the biggest paradigm shift in local LLMs right now, and most people still have not understood it.
Not because it is new. Because everyone filed it as "another quant format" next to GGUF and AWQ, tried it once, and moved on. It is not another quant format. It is a different compression algorithm, and the difference compounds at every tier of hardware.
I mapped every EXL3 implementation I could find, and the result is one lane per VRAM tier. Here is the best recipe for each tier, so you do not have to build it.
WHY TRELLIS IS NOT JUST ANOTHER QUANT
The formats you grew up on round each weight to the nearest low-bit value independently. Every weight introduces its own rounding error, and those errors stack. That is why Q4 feels dumber than Q8.
EXL3 does not round weights. turboderp built it into ExLlamaV3 from QTIP's trellis coding. It encodes each weight vector as a path through a constrained codebook and spreads the error across dimensions with a Hadamard transform. The rounding debt gets distributed instead of stacked.
What that means in practice: your model runs closer to full precision at a fraction of the size. On the independent teacher-logit panel for GLM-5.3-Flash, EXL3 at 4 bits per weight sits 0.004 nats from the uncompressed BF16 teacher. That is nearly lossless. Official FP8 at double the size sits at 0.002 nats. NVFP4 at a higher bit width sits at 0.06, which is 2.5x further from the teacher than either. EXL3 matches FP8 intelligence at roughly half the file size.
The fun fact that sells it: Llama-3.1-70B is coherent at 1.6 bits per weight. A 70B model in under 16 GB. No rounding-based format produces that because it mathematically cannot.
THE MAP
One best recipe per VRAM tier. Every number is either my own bench or a named public receipt.
8 to 12 GB — RTX 4060, 4070, 3060
Qwen3.8-27B EXL3 2.2bpw — 25 tok/s on a 3060 12GB, 64k context, Q4 KV, vision on. A real user receipt (SC_2.20bpw_H3_V3 pack), not a vendor claim. Full 27B on a 12GB card is a much stronger map row than the 9B — it's the trellis thesis doing its job at the bottom of the ladder. The 9B stays as the 8 GB fallback mention in the sub-line.
16 GB — RTX 4080, A5000, 5060 Ti
Qwen3.8-27B at 3.0 bpw with the built-in MTP head. About 55 tok/s code decode with 110k context, owner-measured on a 16 GB A5000. A frontier-tier dense model on a laptop GPU.
24 GB — RTX 3090, 4090
My own bench. Qwen3.8-27B at 3.5 bpw plus the DFlash2 5.0 bpw drafter. 130 to 150 tok/s short-context ceiling, 94 to 105 sustained, full native 262k context resident on a 22 GB budget. Same card, same model, roughly triple your old Q4_K_M llama.cpp speed.
32 GB — RTX 5090
The malaiwah K5K6-hydrated pack. Native 262k with vision intact, or drop the vision tower and MTP3 text-only serves 155 to 212 tok/s decode, verified on a 250k-token prompt on an RTX 5090. This card is the new sweet spot.
48 GB — RTX 6000 Ada, A6000
GLM-4.6 on mratsim's tuned-K packs. 3.84 bpw tuned at 202k context across four 48 GB cards. The tuned mix beats uniform quants at the same size on his measured KLD ladder. This is the quality-first tier.
96 GB — RTX PRO 6000
Two recipes depending on what you want. Fastest single card on the map: DeepSeek-V4-Flash K2 at 133.6 tok/s with dSpark drafting. Most reach: the anoane 2.32 bpw pack fits the MTP drafter AND a full 1M context at 114.5 tok/s. One card.
128 GB — one DGX Spark
My own bench. Cruz's Flash-Next 176B at 3.05 bpw decoding 102.6 tok/s of code, context ladder holding past 200k. For a 320B-class model, the GLM-5.3-Flash 2.05 bpw pack runs 64 tok/s structured with a DFlash2 K7 drafter.
2x DGX Spark, TP2
My dual-Spark bench: DeepSeek-V4.1-Flash at 2.9 bpw, 45.5 to 51.5 tok/s per stream. The community recipe for GLM-5.3-Flash at 4 bpw holds 62.9 tok/s single stream and 146.5 aggregate at four streams, with 900k context. This is my daily driver. Peak local intelligence on a desk.
Two quiet boxes, a 320B-class frontier model, 900k context that holds, tools clean at depth.
If you own two Sparks and you want the smartest thing you can run, this is the loadout.
4x DGX Spark, TP4
The Pollard pack. DeepSeek-V4.1-Flash experts at 3.5 bpw mixed K. 54.7 tok/s single stream, 178.7 at six streams, 1M context, KV pool at 2.56M tokens. Four Sparks out-serve the vendor's own checkpoint on the same nodes.
96 to 128 GB unified — Mac M4 Max, M5 Max
Flash-Next 125B hybrid EXL3 at 49GB residence on a 64GB M5 Max, near-4bit quality, 70+ tok/s — posted by the PonyExl3 author this morning with a demo video (verified direct, not a relay). That slots as its own "64 GB uni" tier between 4x Spark and the 96-128 Mac row, and it's a banger for the map: a 125B frontier-class MoE on a laptop chip at 70+.
PonyExl3 ported the EXL3 codec to Metal in June. Qwen3.6-35B-A3B at 4.0 bpw decodes 68.5 tok/s on an M5 Max against 52 on an RTX 4090, same weights, both measured. MoE loves unified memory. Dense models do not, and prefill is the Apple tax, but the decode row stands.
WHAT EVERY WINNING RECIPE SHARES
The drafter is part of the pack now. MTP heads ship inside checkpoints, DFlash2 drafters get their own EXL3 quants, and a quantized drafter added 33 percent end-to-end because draft weight reads dropped from 16 bits to 5.
And numerics stability IS performance. The fork I run kept the same reduction order, moved mixers to int8 inside a 3-bit pack, and bought 40 percent more decode in four days. That number is my own before-and-after bench, same protocol both sides. Speculative decoding made quantization quality a speed problem. Every recipe above wins because its drafter accepts.
If your card fits an EXL3 pack and you are still on Q4_K_M, the map says you are leaving measurable speed and measurable intelligence on the table. It is the cheapest upgrade in local AI right now, and it is not even close.
Sources, how to run and models in reply 👇


Deepseek V4.1 Flash is a significant upgrade, even compared to GLM 5.3 Flash.
Frankenstein recipe with mixed architectures and offload:
github.com/anoane/05-deepsee…

Recipe for GLM-5.3-Flash (EXL3 4.05 bpw) with a single RTX 6000 Pro + CPU offload on 128GB DDR5.
github.com/anoane/glm53-flas…
Requires PR #315
github.com/turboderp-org/exl…
Works pretty nice on @pidotdev (without TabbyAPI).
Not too fast, but very smart.

Finally got Qwen3.8 Flash Next up to speed on a single RTX 6000 Pro (+ ~100GB offload to ram)
256K 16bit context, 1 concurrent, MTP=3 using NVFP4+FP8 mixed quantization
github.com/anoane/qwen38_fla…


Just finished this, it's the absolute best quality you can fully fit on a RTX 6000 Pro!
huggingface.co/anoane/DeepSe…