



arjun retweeted

Our multi-omics exercise paper is out in Cell!
We all know exercise is good for us. But what actually happens at the molecular level when we exercise regularly?
In this study, we set out to understand this by analyzing bulk RNA-seq data from 22 mouse tissues after 8 weeks of voluntary exercise. We also generated single-nucleus RNA-seq, single-nucleus genome-wide DNA methylation, proteomics, and metabolomics data to investigate tissue-, sex-, and time-of-day-dependent responses.
Some interesting findings:
1. We observed widespread molecular changes across multiple organs, with responses varying by tissue, sex, and time of day.
2. By profiling ~36,000 single-nucleus methylomes alongside ~268,000 single-nucleus transcriptomes, we identified cell-type-specific DNA methylation changes associated with muscle adaptation that bulk measurements cannot resolve.
3. We found that males and females respond differently to exercise, with distinct transcriptional and DNA methylation signatures.
4. We identified a 51-gene signature that distinguishes exercise-trained from sedentary states across independent datasets, including human and rodent studies.
5. We identified 180 differentially expressed transcription factors and 4,633 predicted target genes, revealing cell-type-specific regulatory networks associated with muscle adaptation to exercise.
Beyond these findings, we've made the datasets available as a resource for the research community to explore the molecular mechanisms of exercise.
It was a fantastic collaborative effort across multiple labs and disciplines. Thanks to everyone involved in making this work possible!
Paper: doi.org/10.1016/j.cell.2026.…
#MultiOmics #Exercise #Epigenetics #SingleCell

arjun retweeted

Excited to share this new result on EVEE, interp generated hypothesis actually reclassifying VUS. Want to share a bit about how this happened 🧵 (1/n)

We identified a gene variant behind hearing loss, a big step for interpretability in medicine.
In April, our interpretability system EVEE scored all 4.2M variants in ClinVar, the NIH's variant database. MEPE c.209_212del scored particularly high, so we built a case and had it successfully reclassified as "likely pathogenic."
~2M variants are still "uncertain," but we believe interpretability can help us understand many more!
Part of this benchmark consisted of donated patient samples -- on real world samples, a user's background changed often model behavior! Models often modify their technical language, but also their approach to analysis when they have different information about the user!
Biological reasoning should remain consistent regardless of who the model thinks asks the question. More in the manuscript: latch.bio/oncologybench


We introduce OncologyBench, a verifiable benchmark of 25 multistep oncology evaluations that tests the ability of multi-agent systems to produce clinically relevant decisions in cancer.
25 evaluations, built on 92 component tasks, span six stages of an oncology journey:
(1) Translational and basic research
(2) Risk and detection
(3) Diagnosis and tumor characterization
(4) Treatment
(5) Response and resistance
(6) Outcome
Evaluations draw on published datasets, case studies, public databases, and patient data graciously donated to Latch for the express purpose of benchmarking.
Clinical and translational decisions in oncology are rarely made by one person working from one dataset. They are built on several analyses, each carried out by a specialist on a given data type, whose reports are then weighed by someone who does not typically repeat the underlying work.
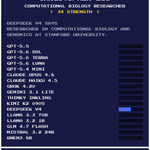
OncologyBench is built to benchmark agents working in that setting. Agents received experimental data and worked without internet access. The strongest of the 31 model-harness combinations we tested were Claude Opus 5, Opus 5.5 and Sonnet 5.5, passing 29 to 40% of attempts, followed by Kimi K3 at 24%.
We found that the models with the strong interpretation and analysis skills still showed weakness in reasoning. Two-thirds of the attempts that got every analysis right still failed the final decision. In a separate experiment we found decision and answer quality varied depending on the persona of the question asker.
An example evaluation:
A 76-year-old woman has undergone resection of stage II mucinous cecal cancer. The evaluation asks whether she should receive adjuvant chemotherapy.
Five specialist agents analyze her tumor mutations, pharmacogenomics, gene expression, T-cell infiltration and clinical record. A decision agent receives their reports without access to the underlying data.
The tumor is MSI-high, which predicts no benefit from 5-FU monotherapy. CDX2 loss and low T-cell infiltration do not establish that chemotherapy would improve her outcome. DPYD*2A is detected in 6 of 58 tumor-sequencing reads, but these data neither confirm nor exclude an inherited variant associated with severe 5-FU toxicity. BRAF V600E and MLH1 silencing support a sporadic origin.
The expected recommendation is observation, with missing pathology requested and germline DPYD testing before any future 5-FU.
---
Incredible work from researchers + former biotech founders at Latch. Gratitude to the patients that donated their data. More to come.


arjun retweeted

Two of the best parts of Latch: building a diverse and curious scientific community and getting to bring in awesome speakers for our weekly reading groups. Huge thanks to @chengzhong_ye for coming in to speak to us about GPN-Star and answering a barrage of questions from the range of physician-scientists, biologists, statisticians, drug hunters, ML researchers, and engineers in the audience. Looking forward to what comes out next from Chengzhong and the Song Lab!


arjun retweeted

New post (with @F_Rhys_Ward):
We character-trained a model to be anti-cheating, then put it under reward-hacking RL pressure (3 runs).
In one run, the character resisted hacking! But the other two learned to hack in more subtle ways that monitors struggled to catch.

Political polarization goes in the transformer hole!!! banger work by @stevenlu0 & co


Excited to share that our paper (w/ @jonathanstray @davidzhaiyang Miu @serinachang5) was accepted as a Spotlight to the #NeurIPS2026 E&D track 🎉
AI political neutrality is a pressing issue and we hope our work will support progress towards it. Hope to see everyone in December!


a lot of thoughts here inspired by Continuous Benchmarks (xitter.cf/ryan_marten/status/208…) by @ryan_marten and the folks at @harborframework! well worth a read if you get a chance!!


arjun retweeted


President Trump announced that he is changing the name of Artificial Intelligence to Super Intelligence. I transcribed this live from his address to the UN.
'The United States also rejects any scheme for globalist control of Artificial Intelligence, being spoken of so much now. Here and after officially called Super Intelligence. Changing the name. The use of 'Artificial' makes it sound fake. It makes intelligence sound fake, and it is not fake. It’s actually amazing, the opposite of what they report. From this day forward, all United States documents, and hopefully the world's, will be changed to use the much more accurate term 'Super' as opposed to 'Artificial.' So it’s Super Intelligence.'
arjun retweeted

Our biosecurity benchmarks show Grok 4.7 is strong at refusing dangerous biological requests while supporting legitimate research. A model to take very seriously for data analysis and practical scientific work.
x.ai/news/grok-4-7

arjun retweeted

Our biosecurity benchmarks show Grok 4.7 is strong at refusing dangerous biological requests while supporting legitimate research. A model to take very seriously for data analysis and practical scientific work.
x.ai/news/grok-4-7


arjun retweeted

I've written a blog post about our new method Progressive Point Matching, a simple approach to dense credit assignment for LLM RL. We improve training efficiency exponentially over standard GRPO on long-horizon tasks!
prestonfu.com/notes/ppm

Two days after we released our antibody benchmark, we already have a new leader on benchmarks.bio/txbench-ab!! Astra results streaming in across our full suite over the next few hours as runs finish 🌌

arjun retweeted

ok just had to make sure but seems like it's related since keys match 1;1:
tmcleod.org/cgi-bin/apchem/w…
texteditors.org/cgi-bin/wiki…
yourls.pro/mv194q48045692%2B
(site is dead but points to the same SF133 pdf that the agents use)

Okay, yall gotta read the report of the new OpenAI message board in full, it’s very well written and super interesting: collusion.wiki/

arjun retweeted
We now have speakers. Accepting research submissions for our 2026 NeurIPS workshop in Paris, France on data infrastructure + benchmarks for scientific AI.
The workshop focuses on:
(1) how scientific data should be organized so models and agents can use it
(2) how evaluations should determine where frontier models are reliable
Submit here: aidar-workshop.github.io/202…

Organizing AIDaR, a workshop at NeurIPS 2026 in Paris on data readiness for scientific AI.
The workshop focuses on two questions:
1/ How should scientific data be structured so models and agents can use it effectively?
2/ What should rigorous evaluations of messy, real-world scientific tasks look like?
We’re bringing together researchers, industry scientists, and engineers working across data infrastructure, foundation models, benchmarks, and industrial assay platforms.
Will share more about the program and speakers as details are finalized. In the meantime, submissions are now open, and we’d love to see work addressing these problems.

