
PhD Candidate - Computer Vision Research @TechnionLive | ex @WeizmannScience @NYU_Courant @Pagayaltd
Israel
Joined December 2023
- Tweets31
- Following116
- Followers109
- Likes29




Pinned Tweet
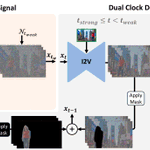
We present Time-to-Move (TTM)! a training-free, plug-and-play method for precise motion control in video diffusion. Unlike prior training-based methods, TTM works with any backbone at no extra cost🔥
Page: time-to-move.github.io
[1/4]
@NoamRot @orlitany @mann_amir_
Assaf Singer retweeted

pick any pixel in a normal video and follow it through 3D, even while something blocks it
ReLift (Technion, NVIDIA) doesn't learn tracking from scratch. it fixes the errors of existing 2D trackers and depth models, so it improves as they do. code's out
relift3d.github.io/
🚀 Very cool to see Time-to-Move adapted for MiniMax H3! Love seeing the community build on our work and bring motion control to new models.
Check out our original project and code:
🌐 time-to-move.github.io/
💻 github.com/time-to-move/TTM

Minimax h3 😲 Motion Time to move
implementation of time-to-move dual clock denoising for Minimax H3, allowing for motion control by dragging objects into motion, or mask part of a video
and change what happens.
github:
github.com/PxTicks/h3-motion
workflow:
drive.google.com/file/d/1mOH…
🚀 Introducing ReLift: dense 3D tracking from monocular video.
Strong 2D trackers provide correspondences.
Geometry models produce depth & cameras.
We show how to combine them, repair 3D errors, and recover occluded motion for SOTA 3D tracking.
All it takes: one small corrector + off-the-shelf models.
🌐 Project: relift3d.github.io/
@MarounKhriesh @NoamRot @yoni_kasten @orlitany
[5/6]
Trajectory repair turns a strong lift into more accurate 3D tracking, with the largest gains during occlusion.
[6/6]
Working on 2D tracking or 3D geometry?
Try pairing your model with ReLift to build a dense 3D tracker. We'd love to see the results!
Explore the paper, code and additional examples:
🌐 Project: relift3d.github.io/
Code: github.com/ReLift3D/ReLift
Paper: arxiv.org/abs/2610.42136
Assaf Singer retweeted

🎬 Excited to share our paper: Joints, Camera, Action! (JCA)
JCA generates video & 3D motion together for any rig!
Video models generate motion you can watch. But what if you could use that motion to animate a 3D asset, with motion that responds to its surroundings?
research.nvidia.com/labs/par…
🧵
Assaf Singer retweeted

Meet DyRAD: Radar NVS for dynamic driving scenes.
📡🚗 Radar directly senses motion through Doppler, but prior radar NVS methods ignore this signal where it matters most: dynamic scenes.
🌐 dyrad-nvs.github.io
📄 arxiv.org/abs/2609.39841
💻 github.com/Dyrad-NVS/DyRAD
🧵

Come see us tomorrow at @iclr_conf!!

Happy to share that Time-to-Move has been accepted to @iclr_conf! 🇧🇷
It’s been exciting to see the community adopt this work over the past few months for enhancing control in video generation.
We’ll present it at the main conference this Friday, April 24, 10:30 AM–1:00 PM, and also at the ReALM-GEN workshop on April 27.
Feel free to stop by and say hi to me or @assaf_singer!
Thanks @_akhaliq for sharing our work!
Project page: time-to-move.github.io/
Assaf Singer retweeted

Tired of 3D generations that look synthetic? They don’t have to.
Excited to share that Realiz3D is accepted to #CVPR2026 🎉
A framework for training diffusion models that are 3D-consistent, controllable, and photorealistic.
🔗 Project page: idosobol.github.io/realiz3d/
🎥 Teaser ↓
Assaf Singer retweeted

📢 RadarGen: Automotive Radar Point Cloud Generation from Cameras
Can we generate realistic radar point clouds solely from camera images? 🚗📡
We introduce RadarGen, a diffusion-based framework that synthesizes radar returns aligned with visual scenes.
radargen.github.io
Assaf Singer retweeted

Sharing that DynVFX, our framework for augmenting real videos with dynamic content, is accepted to SIGGRAPH Asia 2025!🥳
Who is this framework for? EVERYONE.
It's tuning-free, zero-shot, and fully automated – All you need to do is give an input video + simple text describing the new content.
What's the trick? enforcing the generation to be content-aware of existing scene anchors via selectively extending the attention mechanism in a T2V DiT model.
And code is finally out!: github.com/DynVFX/dynvfx
Read the paper for more details: arxiv.org/abs/2502.03621
Website: dynvfx.github.io/
Grateful for presenting it recently at #MIT and next week at #SIGGRAPHAsia2025!
With the amazing @RafailFridman, @omerbartal, @talidekel
Assaf Singer retweeted

Playing with the Time To Move test monkey in ComfyUI. 🙃
Cool to see the little secondary and joint animation it adds #aivideo
Assaf Singer retweeted
This uses Wan with Kijai's wrapper.
Thanks to @NoamRot @assaf_singer and the other authors for sharing your work!
Assaf Singer retweeted

🚀 Our paper “Appreciate the View: A Task-Aware Evaluation Framework for Novel View Synthesis” is accepted to 3DV 2026! @IdoSobol @orlitany
🔗 Project page: saarst.github.io/appreciate-…

Assaf Singer retweeted

Time-to-Move: Training-Free Motion Controlled Video Generation via Dual-Clock Denoising. arxiv.org/abs/2511.08633

This is wild 🔥 Love seeing people play with Time-to-Move!
TTM is now available in ComfyUI via WanVideoWrapper. Big shout-out to @wildmindai !

WanVideoWrapper now supports TimeToMove for Wan 2.2. It’s fun to play with- move objects with Cut-and-Drag on the image to get a fully animated video.
github.com/kijai/ComfyUI-Wan…
