
CS PhD @ CMU https://xitter.cf/t.co/tCKYiUbOdr | https://xitter.cf/t.co/zdDNelFVJO
Joined January 2024
- Tweets163
- Following26
- Followers686
- Likes494






Pinned Tweet
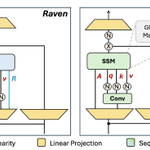
SSMs fail on recall tasks they have the capacity to solve. The two dominant approaches today, SSMs and sliding-window attention, both lack persistence: memory either decays over time or gets evicted.
We built Raven to fix this, surpassing all prior linear models even at 16× their training sequence length. 🧵🐦⬛
Aviv Bick retweeted

Hi all, I have a new result I'm excited to share. It turns out that *all existing implementations* of softmax and cross-entropy (that's JAX, PyTorch, textbooks, etc) have a subtle bug --- two bugs, actually. A simple rewrite fixes both, and eliminates "slingshots" when grokking:
Aviv Bick retweeted

There is an (unpatchable?) supply-chain zero-day in PyTorch autograd that allows a regularization term to use the model's weights as RAM and SGD as its CPU clock to run any computation during training.

Aviv Bick retweeted

[1/4] 🧵 Mamba-3 rotates its recurrent state. What does that buy beyond retention?
Our new paper connects these rotations to underdamped second-order dynamics: decay controls the damping envelope, while phase shapes oscillation.
📄 arxiv.org/abs/2610.13341


Aviv Bick retweeted

We pretrained a 2.3B MoE (360M active) Hybrid Mamba-2 that lands within a few points of Llama-3.2-3B using <1% of its pretraining FLOPs.
No dedicated cluster. The run hopped between H100s, A100s, V100s (yes, V100s) and TPU v5p/v6e on a single codebase.
Meet Rigel 🧵

Aviv Bick retweeted

Releasing our runtime dynamic compression framework that achieves 1.5-2.0 bit compression at high quality. This is integrated into the bitsandbytes2 library, which starts as a private beta today.
Paper: timdettmers.com/papers/runti…
Private beta signup: forms.gle/Pwtp8CVRULdoEnY79

Aviv Bick retweeted

Nearly half a year of silence. We spent it studying one problem: how far RL can scale.
MiMo-V2.6 is in the middle of its RL run right now. Three things we scaled: compute (~2B tokens per step, 1568 prompts × 16 rollouts, fully async), environments and harnesses (multi-task agentic RL, mixed across multiple harnesses in one run), and grader compute (agentic in-group credit assignment, with test-case and rubric-based rewards). We'll open-source the details piece by piece over the coming weeks.
Streaming the run: mimo.xiaomi.com/rl/
Aviv Bick retweeted

K2 Horizon is coming to CMU.
Following the release, we're hosting a workshop on building with K2 Horizon, followed by an event at HackCMU 2026.
We look forward to seeing what CMU's hackers create.
Learn more: bit.ly/4irRRU5

Aviv Bick retweeted

Yes, this result cost millions of dollars.
But remember that when @OpenAI announced o3 it cost ~$500,000 to score 87.5% on ARC-AGI 1. Today, Astra scores higher for ~$20.
In 2025 it took us and GDM an enormous amount of compute to achieve IMO gold. For the 2026 IMO, anyone with a $20/month ChatGPT subscription could do it.
Massively scaling test-time compute gives us a glimpse of the future. I believe that a year from now everyone will have an AI at their fingertips capable of solving problems of this caliber.

We’re sharing a solution to the Navier-Stokes Millennium Prize Problem, one of the deepest problems at the frontier of mathematics.
The proof was produced by a group of agents, using an OpenAI next-generation model significantly more capable than GPT-6 Astra.
The problem concerns whether the description of smooth three-dimensional fluid motion modeled by the Navier-Stokes equations can break down. It has remained unresolved for roughly 90 years.

Aviv Bick retweeted
Introducing K2 Horizon: a connected fleet of six foundation models ranging from 0.9 billion to 375 billion parameters.
- Frontier performance: Across coding and agentic tasks, K2 Horizon delivers top-tier performance in every size class—with the 0.9B, 3.7B and 7B models setting new state of the art at their respective scales.
- Radical openness: K2 Horizon represents the largest fully open-source model launch in AI history. The fully open code, training data and recipes are a significant step forward in transparency.
Launch page: ifm.ai/k2/
Tech blog: ifm.ai/blog/k2
Hugging Face: huggingface.co/collections/I…

Aviv Bick retweeted

How does one RL post-train a 397B model for long-horizon knowledge work? 👩💼
We share every step we took to bring Qwen 3.5 397B from 16.1% Pass@1 to 27.3% on APEX-Agents using DPPO, including final models weights and the full training script🚀 This is the first of many works from Mercor Research on open model training research.
Full blog: mercor.com/blog/training-fro…
Source code: github.com/Mercor-Intelligen…

Aviv Bick retweeted

This Fall at CMU we're teaching a new course on AI Agents!
The goal is that you learn how to create a scaffold, build evals, and train an agentic LLM using RL.
We'll try to balance theory and practice, and introduce modern frameworks and best practices.

Aviv Bick retweeted

Had an amazing time in London! 🇬🇧 Huge thanks to @JUmp for the invitation to present Raven!
Here are the slides on Raven, including some background on SSMs and how @avivbick and I built
Raven:
arshiaafzal.github.io/assets…
Also available in the official repo:
github.com/goombalab/raven/b… – at London, England


!!!

Me and @avivbick are in London for today, if you are also into ssms and hybrid models feel free to reach out and we would love to see you🇬🇧!

Aviv Bick retweeted

You are welcome to visit our new home of @IFM_MBZUAI !

A new space for the work ahead.
We’re excited to share a look at IFM’s new office in Sunnyvale, a place for our team to collaborate, exchange ideas, and continue advancing open foundation AI.
This new space marks the next stage of IFM’s growth as we expand our global team and the ambition of our work. We’re looking for more people to help shape what comes next.
Interested in joining us?
Explore open roles: jobs.lever.co/ifm-us


Aviv Bick retweeted

Refreshing my view on Linear Attention states and SWA! @avivbick
Initially, I found this paper when searching works on the idea of "MoE of states", but it really taught me to view sparse linear attention in a different way.
I wrote down my reflections here:
fyf-spec.github.io/blogs/rav…

SSMs fail on recall tasks they have the capacity to solve. The two dominant approaches today, SSMs and sliding-window attention, both lack persistence: memory either decays over time or gets evicted.
We built Raven to fix this, surpassing all prior linear models even at 16× their training sequence length. 🧵🐦⬛
Aviv Bick retweeted

My summer project is done! A 20 video, free course on post-training to accompany my book is all on YouTube with slides open for modification & re-use.
~12 hours of content covers the core foundations and some research areas I think will grow in importance. It was a fun time to review all the fundamentals again, as it is clear in the next 1-3 people the amount of people wanting to learn post training will likely 100X again from today, as we have already 100X'ed from two years ago.
As AI agents get increasingly capable at coding and discussing these fundamentals (see the code exercises accompanying the book that I am refining with the community) I think developing clear intuitions for how models work and why is one of the most important skills going forward in AI. Still, learning the post-training math is the best way to battle test them. I personally just in this course am starting to master how forward/reverse KL relates to post-training topics.
Thanks to all my viewers, and I'm happy to answer questions in the book discord or understand how to better teach the various reward models, on-policy distillation, new RL algorithms, etc.
Plus, the book is 50% off right now with the code PBLambert on Manning to celebrate the launch.
I'll share the relevant links below.
Who's going to make this course for pretraining?

Aviv Bick retweeted
It was a pleasure to sit down with @BeckyCNN to discuss impact of AI on society and how to prepare our young generation for that — learn it, use it, and ask new questions.

.@EricXing, president of @MBZUAI joins me to discuss where artificial intelligence is heading, what it means for education and employment, and whether its impact will ultimately be determined by society rather than the technology itself. #IntelligentFuture
Full conversation: edition.cnn.com/2026/07/21/w…
Aviv Bick retweeted
My book, Reinforcement Learning from Human Feedback is done!
This is the book I wish I had when learning to fine-tune, align, & now post-train models since ChatGPT. The resource has been built by me finding time to study and document the fundamentals on nights and weekends since 2024.
Transferring as much of the intuitions of building Olmo as I possibly can in the book format.
The book is launching with an over 10 hour, full course with slidedecks, functional code for the training chapters, an example model completions library, and of course the free online web version.
Physical orders from Manning will ship in 1-2 weeks, and Amazon a week or so after. Thanks for your support!
