

inference. pre-training. post-training. quant.
Ottawa
Joined October 2025
- Tweets1.5K
- Following23
- Followers323
- Likes641




Speed or quality? Today, if you serve AI models, improving one means giving up some of the other.
To make models fast enough for heavy traffic, teams compress them, and that costs some accuracy. Backboard removes that trade-off.
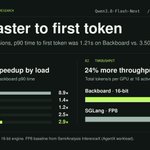
We ran the full, uncompressed Qwen3.8-Flash-Next on Backboard against a compressed version of the same model on a popular serving engine. The test was @SemiAnalysis_ independent benchmark.
The full model on Backboard:
→ Started answering 2.9x sooner
→ Served 24% more requests on the same GPUs
You run the full model, get more out of the hardware you already pay for, and have your cake and eat it too.
Try it with your own models and traffic: backboard.io/blog/qwen-flash…


BackboardIO retweeted

What happens when the workload keeps coming?
In our GLM 5.3 sustained test at 32 concurrent users:
@BackboardIO: 370 output tokens/sec
vLLM: 74.9
4.94X aggregate output throughput.
Full model. No Quant!

BackboardIO retweeted
Our latest GLM 5.3 full-model BF16 test:
@BackboardIO: 165.5 output tokens/sec
vLLM: 63.5 output tokens/sec
2.61X aggregate output throughput.
Same 96 workflows. Same request bodies. 32 concurrent users.

Backboard just got a little more powerful. ⚡
35 new fal.ai media tools.
More reliable video generation.
Better usage reporting.
Plus a few product improvements.
Read the full update → backboard.io/changelog/new-m…


AI infrastructure doesn’t become valuable when the API works.
It becomes valuable when the system works in production.
That means connecting infrastructure to a real outcome and proving it works.
Our thinking on benchmarks → backboard.io/blog/ai-industr…

#BackboardAsks: Would you rather have the smartest model... or the smartest routing layer? 🤔
Agent memory is becoming infrastructure.
The hard part isn’t storing more history. It’s deciding what should persist, who can use it, how it changes, and when it should disappear.
We’ve been exploring that architecture at Backboard → backboard.io/blog/enterprise…

#BackboardAsks: What's one AI feature everyone is hyping that you think becomes a commodity in a year? 👀
The model will change. Your application state shouldn’t have to.
Backboard’s approach keeps memory and orchestration portable across models and providers instead of tying the application to one runtime.
More on the layers around the model → backboard.io/blog/backboard-…

Jev by @typesafeai AI is now on Backboard. ⚡
@HackTheNorth is happening, so skip the waitlist and use Jev through the Backboard API while you build.
Find us at Hack the North this weekend. 👀
We can’t wait to see what you cook up.

Jev by @typesafeai is now available on Backboard API. More instructions coming soon this isn’t your typical LLM.
And we have no doubt that it will be part of our open source CLI and IDE soon!


Video generation just dropped. 🎥
AI so good it gave us 1,000 aura points. 😎
(+10,000 aura points for @RobImbeault's bald spot.)
There’s a lot more in this release 👀
→ Improved image generation
→ More media inputs
→ Video editing + extension
→ More control over generation
→ Updated Model Library
→ SDK updates
New models alert! ⚡
Backboard’s model catalog keeps expanding automatically as new options become available.
Now available through OpenRouter:
