

https://teapaw.org/t.co/yb0dz7FpQG CTO|ex-Baidu|AI, product, engineering & startup — real frontline notes
Joined February 2025
- Tweets3.3K
- Following521
- Followers535
- Likes410




BlanPlan retweeted

Exciting news: DeepSeek-V4.1-Flash-20261017 (Max) by @deepseek_ai is now the #1 open model in Code Arena: WebDev, surpassing Kimi K3 (Max) at 10x lower cost!
Highlights:
- #1 open model, ahead of Kimi K3 (Max)
- #12 overall with 1670 pts, ahead of Claude Opus 5 (High) and within ~10 pts of GPT-6 Sol (Max)
- Shifts the Pareto frontier at $0.3/$1.2 per million input/output tokens
- +52 pts vs. the previous DeepSeek-V4.1-Flash-20260910
Congrats to the @deepseek_ai team on another strong contribution to the open source ecosystem!
🤖 Made with AI


🚀 DeepSeek-V4.1-Flash-1017 is here!
Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API.
🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy, WorkBuddy, and more. Upgrade to DeepSeek Harness v0.2.1-rc.1 or later for the best experience with the new model.
1/4


BlanPlan retweeted

Most companies are buying AI seats and calling it transformation. That’s an expensive way to keep forgetting.
BlanPlan retweeted

If Opus 4.6 was the turning point model for handling routine tasks and substantial tasks, then Opus 5.5 (actually Fable5 already had this capability when it first launched, it just cost too much) is definitely the turning point model for open-ended problems, ambitious goals, and large-scale tasks. I used two 20x usages, and after experiencing it, the agent is definitely ready to move on to the next stage. I was so excited I couldn't sleep - this is definitely a moment worth commemorating.


BlanPlan retweeted

Anthropic 在 Claude 身上发现一个类似人脑的「内部思考空间」区域:J-space
它是Claude自己进化出来的,并非最初设计
这块区域,长得跟人脑里「你能意识到的那部分思考」出奇地像,
打个比方,你就懂了
你现在读这句话的时候,大脑在同时干一堆事:调整坐姿、控制呼吸、把屏幕上的线条认成字。这些你基本察觉不到,它们在"意识不到"的层面自动跑。
但有另一类脑活动你能抓住,比如脑子里突然蹦出一个画面,或者你盘算中午吃什么。这类活动很特别:你能把它说出来,能主动控制它,还能拿它做推理。神经科学管这个叫"能被意识到的"活动。
Claude 内部也有这么一条清清楚楚的分界:它绝大部分处理在「意识不到」的层面自动跑,但有一小撮神经活动,恰好对应人脑里那类「能被意识触及」的思考,能被读出来、能被调用、能参与推理。
J-space 只占 Claude 内部总活动不到十分之一,一次只装几十个概念,但删掉之后,它的多步推理、总结、押韵写作能力大幅下降甚至归零。
研究者能直接钻进 J-space,把里面的某个词换掉,Claude 最终给出的答案会跟着变,说明它真的在参与思考,不是旁边记分的。
用这套方法(J-lens),Anthropic 已经能读到 Claude 没说出口的想法:私下意识到自己在被测试、编造数据时的造假意图、被植入的隐藏目标。
他们还发现一种新训练法:只训练模型「如果被追问会怎么解释自己」,就能连带压低它在真实任务里的不诚实行为。
BlanPlan retweeted
The "should you read code" debate is dumb because the real decision isn't binary, it's a scale:
1. Reading every line of every diff
2. Scanning every diff, reviewing important lines
3. Ignoring diffs but understanding the 'why' of every PR
4. Spot checking PR's instead of reading every one
5. Ignoring PR's, but doing regular spot checks on the codebase
6. Ignoring the code, but spot checking agent traces to help improve the system
7. Ignoring both the code and the system, let models handle everything
Where are you on the scale?
BlanPlan retweeted

Andrej Karpathy:
"Remove yourself as the bottleneck. Maximize your leverage. Put in very few tokens, and a huge amount of stuff happens on your behalf."
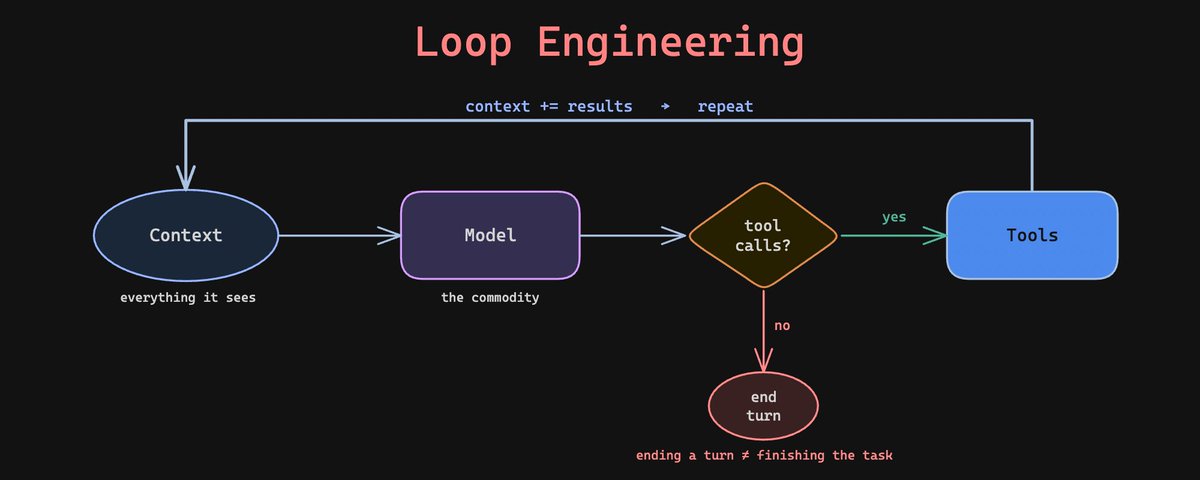
loop engineering is the exact thing that gets you there.
in a hand-run session you do two things. you decide what the agent runs next, and you check its output before the next step. both are manual, and both are the ceiling on how far the agent gets without you.
loop engineering moves both steps into the system. the diagram below shows the operating structure that surrounds the loop:
→ a trigger decides what to run, whether that's a message, an event, or a schedule, so the agent starts without you there to kick it off.
→ the loop is the maker that produces the work, thinking, acting, and observing until it's done or the brakes stop it.
→ a separate checker grades the output, because a model grading its own work justifies what it already did instead of catching where it failed. the checker's findings return to the maker as the next instruction, and the cycle repeats until nothing is left to fix.
→ state lives on disk, not in context, since the model forgets everything between runs. an MD file or a knowledge graph holds what's done and what's still open, so a loop can pick up again days later.
for that state layer, Zep's Graphiti is a clean open-source option, a temporal knowledge graph that invalidates stale facts and returns context through vector, full-text, and graph search in one call.
repo: github.com/getzep/graphiti
two things decide whether an unattended loop holds up.
the exit has to be set before the loop runs, not while it's running. a loop with no stop condition burns tokens, and the cost climbs fast once sub-agents and long runs stack up. a clean exit reads like "all tests pass and lint is clean, stop after two passes."
and the checker only catches failures inside a run. the harness around the loop, the prompts, tools, and checks wrapped around the model, still drifts and breaks in production as models change. catching that needs observability on every run, not a green checkmark.
Comet's Opik is built for that layer, an open-source tool that traces every call and turns a failing production trace into a regression test so the same break can't recur.
repo: github.com/comet-ml/opik
your job stops being the hands inside the loop. it becomes designing the machine that runs without you, then watching the traces closely enough to trust it.
the model is becoming a commodity. the loop around it is where the real engineering lives now.
I wrote the full breakdown. the article is quoted below.
stay tuned for more on this!

BlanPlan retweeted

DeepChat 1.0.7 发布了,虽然这个版本主要是一些性能优化和bug修复,但刚好是 DeepChat 的第 100 个 Release 版本,值得纪念一下
1、新增默认聊天工作区(没错,就是最早的ChatBot)
2、任务感知 Agent Memory,并支持在聊天历史中持久化 Agent plan blocks
3、优化 Computer Use helper runtime 的隔离和生命周期
4、修复首次 SQLite schema 初始化、陈旧 Tape FTS 搜索命中、New API responses endpoint 配置等问题
5、 集成了最新的 markstream-vue
本次主要贡献者还是大家喜闻乐见的 @wegi8666 @yyhhyyyyyy 还有 @simon_he1995


BlanPlan retweeted

In Claude Code, run /model and select Fable from the model picker, or switch directly with:
/model claude-fable-5


BlanPlan retweeted

🚀 We’re hiring! DeepSeek is forming a new Harness team to build Code Harness from the ground up—may be you can call it DeepSeek Code or something like this hhh🤣🤣🤣
📍 Based in Beijing. Two roles open:
🧠 Harness Product Manager → app.mokahr.com/social-recrui…
👨💻 Harness R&D Engineer → app.mokahr.com/social-recrui…
Research meets product—let's build it together. Hit the links and apply directly! 🔥
#DeepSeek #CodeHarness #AI #Hiring #ProductManager #Engineering #Beijing #Referral

BlanPlan retweeted

You can now use X Premium subscriptions in Hermes Agent, and Hermes Agent can now search X posts.
x.ai/news/grok-hermes


BlanPlan retweeted

OpenAI 把 Codex 搬进了 ChatGPT 手机 App,今天在 iOS 和安卓上同步开启 preview,所有 ChatGPT 用户都能用,包括免费版和最低价的 Go 套餐。
手机端不是让你在手机上写代码。真正干活的 Codex 还是跑在你的笔记本、Mac mini 或者 devbox 上,手机只是一个远程窗口:地铁上能看 Codex 跑到哪一步、审一眼它改的 diff 和跑的测试结果、批准下一步操作,或者临时换个方向走。文件、凭证、权限都留在原来那台机器上,不上传到手机。
OpenAI 的解释是底层走了一层 secure relay 中继,让跑着 Codex 的机器能跨设备保持可达,又不直接暴露在公网上。你在哪台设备登录 ChatGPT,会话状态和上下文就跟到哪里。
为什么现在做。OpenAI 自己公布的数字是 Codex 每周活跃用户已经过 400 万。当 agent 越来越多地跑长任务,几十分钟甚至几小时的那种,人坐在电脑前盯着就很傻,你需要随手能看一眼、能拍板的能力。
一个明显限制:手机端目前只能连 macOS 上的 Codex,Windows 支持据说”很快”。
另一层意思是,OpenAI 没给 Codex 单独做手机 App,而是塞进 ChatGPT 主 App。这跟他们之前透露过的”超级 App”路线一致,把 ChatGPT、Codex、Atlas 浏览器整合成一个入口。桌面端是独立的 Codex App,手机端直接合并进 ChatGPT。
参照系是 Anthropic。Claude Code 从去年秋天起就支持手机远程查看和介入正在跑的任务,后面的 Cowork 配套移动端走的也是类似 dispatch 思路。Codex 这次把覆盖范围扩到了 devbox 和远程企业环境(支持 remote SSH 接入),算是追平加扩张。


BlanPlan retweeted

small ship / passion project, more details soon
github.com/openai/openai-cli
1. call responses via cli with all cloud tools
2. unix style structured outputs via cli
2. image gen/edit, transcription, tts
3. make projects and provision api keys
more docs soon
