
AI-native builder. Windows. Security-first. Formerly Microsoft Exchange/M365. Building in public. https://teapaw.org/t.co/Abrrd5BbyL | https://teapaw.org/t.co/1mRGaBRkEF
San Francisco, CA
Joined June 2008
- Tweets6.5K
- Following161
- Followers1.2K
- Likes1.8K



Pinned Tweet
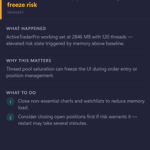
Built a Windows process monitoring agent this morning. First real-world run surfaced a textbook degradation pattern on a mission-critical app:
🔴 Sustained memory leak — private bytes growing unbounded across sessions
🔴 CPU thrashing correlated with memory pressure (burst spikes to 371%) 🔴 Zombie process — paged out, idle, but holding 3.6GB of committed private memory the OS can never reclaim
The interesting part: the failure signature is consistent and predictable well before the process becomes unresponsive. Working set oscillates while private bytes climb monotonically — classic unmanaged heap leak, GC fighting a losing battle against its own allocations.
Building this into a production-grade Windows monitoring agent — event log correlation, ETW telemetry, process health profiling, and an LLM layer that turns raw signals into plain-English diagnosis and actionable remediation steps. Targeted at power users on critical systems who can't afford unplanned downtime.
Early access interest? Questions? DM @bsuneja. Will share when it takes shape.
3
569
Satellite internet sounds cool and exciting.
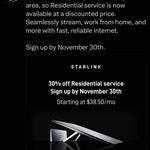
Starlink's pitch makes it sound even better: up to 400+ Mbps on Residential Max ($130/mo, free kit rental), or 30% off Residential starting at $38.50/mo for 100 Mbps.
The real-world U.S. medians (Ookla, 2026):
- Starlink: ~120 Mbps down, ~21 up, ~30–40ms
- 5G home: ~125–225 Mbps down, ~10–18 up, 46ms+
- Fiber: 1–5 Gbps plans, symmetrical, <10ms
Starlink Max promises "up to 400+ Mbps across multiple devices." That's a best case, not a typical speed. Across all plans, the U.S. median is about 120 Mbps.
The discount ad itself says "capacity available in your area." Satellite capacity is shared. Your speed depends on how many people in your area sign up.
Fiber now reaches 60%+ of U.S. homes. If you can get it, no satellite plan comes close at any price.
Starlink earns its place for rural homes, RVs, boats, travel and as the backup to your backup. That's a real market. It's just not most of us.


62
Bharat Suneja retweeted

PowerShell7 is going to ship in Windows!!!!
From the outside, something like this seems like it should be a simple decision.
But when you ship software to a billion people, nothing is a simple decision.
The PowerShell team has been working towards this team for a VERY long time.
You would be shocked to understand how much effort was involved.
I keep encouraging with the original spirit of PowerShell v1:
If there is ANY hoop you are unwilling to jump through, you will not succeed.
Jump through the hoop and there will be another.
And another. And another.
And if you jump through enough, you'll succeed.
MAD RESPECT for the team's fortitude is making this happen.
devblogs.microsoft.com/power…

Bought a tiny position in $ANT today to mark the IPO.
I build on Claude, and I’ve been vocal when Anthropic broke things on me. Now I own a piece of what I depend on.
Congrats to the team, @AnthropicAI.
Coming to Linux from Windows and #PowerShell? Paths are case-sensitive, so ls /opt/music/ten + Tab won't find "Ten Summoner's Tales".
Make Tab completion ignore case:
echo "bind 'set completion-ignore-case on'" >> ~/.bashrc
Type lowercase, hit Tab, and bash fixes the case for you. 🐧
1
58
As a Claude Max 20x subscriber, no 5-hour limit for Ultra is a real upgrade.
The pricing card says 10x Pro usage every week, while Max 20x was 20x per session. @claudeai, did the weekly allowance change?


We’re renaming our Max plans:
Max 5x → Max
Max 20x → Ultra
Max is still $100/month, and Ultra is still $200. If you’re a subscriber, there’s nothing you need to do.
We’re also removing the 5-hour limit for verified Ultra accounts, starting today with most existing subscribers. Newer accounts keep a temporary limit until they’re verified, which helps us prevent fraud and abuse. You'll get an email when it's removed.
Weekly limits remain unchanged. View our plans here: claude.com/pricing

90
No, your iPhone isn't hoarding 31,000 photos of your face.
Per Apple, Face ID images are discarded once converted to a math template locked in the Secure Enclave. Not in backups, not readable by apps.
Don't run the "prompt" from that post.
support.apple.com/guide/secu…
51
Went in to patch PHP2Shell on my WordPress blog. The patch was one container pull.
What Claude found around it mattered more: a pinned PHP image frozen since March, DB root password in the container env, origin reachable around Cloudflare.
Most of the time was waiting on Docker's patched image.
#PHP2Shell
1
1
133
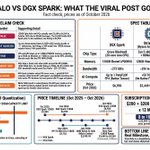
$AMD vs $NVDA: Every major claim in this Strix Halo thread is wrong.
1. Price: You are not getting 128GB of LPDDR5x in a Strix Halo box for $1,499. The RAM alone costs more than that (4x32 GB around $2000, 2x64 GB almost double). The 128GB dev systems are ~$3,500–$4,300.
2. Math: A 235B model requires ~140GB+ at Q4 weights alone before context/KV cache. It does not fit into a 128GB unified pool without extreme, Lobotomy-tier quantization.
3. Benchmarks: Claiming it’s "3x faster than an RTX 5080" on DeepSeek R1 is a sleight of hand. A 5080 only has 16GB VRAM. It didn't lose on compute; it ran out of memory and fell off a PCIe cliff into system RAM.
4. Architecture: Strix Halo's direct competitor here isn't a NVDA PCIe card. It’s the DGX Spark (GB10). Both share the exact same 128GB LPDDR5x shared memory architecture at ~270 GB/s bandwidth, but GB10 packs 1 PFLOP of native FP4 tensor compute and ConnectX networking.
Strix Halo is a real x86 milestone for local AI. The math around it is pure engagement farming.


AMD CEO Lisa Su just went after Nvidia's $4,000 AI box using a $1,499 machine the size of a lunchbox.
Holding it up on stage with one hand, she ran a model with 235 billion parameters live, with no data center, cloud or rented GPU behind it.
The surprise is the chip. Inside is AMD's Ryzen AI Max+ 395, which became the first x86 processor whose CPU and GPU draw from one shared pool of 128GB of memory. That one design choice lets a desktop handle models that once needed a server rack.
On Linux, 110GB of that pool can go to the GPU. An RTX 5090 offers 32GB. A 4090 offers 24GB. So this box has more than three times either card, in a case about as thick as a paperback.
The number that stunned the room: on DeepSeek R1 inference, the chip ran more than 3x faster than an Nvidia RTX 5080. A $1,499 desktop beating a $1,000 graphics card on real AI work. For a decade, Nvidia told the world that serious AI meant Nvidia hardware. AMD just made it a desktop item at half the cost.
Now the math. A heavy AI user today might pay for Claude Code Max ($200), ChatGPT Pro ($200), Cursor ($20) and Gemini ($20). That adds up to $5,280 a year. At that rate, the box covers its cost within months, then keeps running at no extra charge.
The setup: install Ollama, pull Qwen3 235B, and aim Claude Code at localhost. The interface stays the same. But nothing leaves the machine, there is no per-request bill, and no provider slows you down at 3am when you finally sit down to build.
This is where every AI subscription starts to look optional. Lawyers worry less about leaks to OpenAI. Developers stop staring at the token counter. Founders stop renting H100s for prototypes they abandon because of the bill.
Whoever gets there among the first thousand will own private AI consulting for the next two years.
If you're new here, @GeniusGTX is a gallery for the greatest minds in economics, psychology, and history. Follow along for more similar content.
Readers added context they thought people might want to know
The machine demonstrated (AMD Ryzen AI Max+ 395 / "Halo" platform with 128GB unified memory) retails for ~$3,300–$5,500 currently (AMD reference platform $3,999); $1,499 pricing applied to older/lower-RAM configs or promotions, not this spec.
liliputing.com/amd-ryzen-ai-h…
computingforgeeks.com/ryzen-ai-max-3…
techradar.com/pro/slowly-goi…
169
Now that AI is renamed to Super Intelligence by executive order, can we please update the pricing metric too?
Cost per token made sense when it was autocomplete. Now that it's officially Super Intelligence, I want my invoice in Cost Per Intelligence (CPI).
Who do I call at OpenAI? Wait, is it still called OpenAI?
108
Got the Sonnet 5.5 drop email, sat down to run evals, and immediately crashed into auth errors. Looks like every single builder had the same plan this morning.
We all share one collective brain cell.


77
Skip killing msedge.exe from #PowerShell or Task Manager when troubleshooting.
It tells Edge "The browser crashed". Triggers crash recovery semantics. Leaves behind stale locks. Can corrupt session files.
Instead, type this in the address bar:
edge://restart
Clean, graceful process recycle. Full session state preserved across all windows and tabs. Zero session loss.
@MSEdgeDev #Windows

70
If someone's AI agent actually turned $15 into $16,000 while they slept, they'd be running a private fund, not writing multi-tweet creative writing essays begging for bookmarks.
Engagement farming in the AI era.
1
5
99
Rented A100 GPUs over the weekend. 6-year-old data center cards, still being rented at a premium.
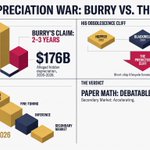
Burry's thesis: hyperscalers are depreciating GPUs over 5-6 years when real useful life is 2-3 years, hiding $176B in costs.
Maybe. But the market for older compute is telling a different story. A100s still in demand. 3090s and 4090s on the desktop side priced insanely. Apple Mac Studios sold out.
These AI factories with older machines are still producing tokens that make money. That doesn't look like 2-3 year obsolescence to me.
$NVDA

1
5
119
A recent bug in #ClaudeDesktop on Windows makes it stay always-on-top of every other app. No setting to disable it.
Root cause is identified, multiple reproductions, fix direction is clear. Still open (#85891).
A PowerShell workaround clears WS_EX_TOPMOST for that session. Flag comes back on every relaunch. Not a fix (few workarounds are). It's a tax you pay every restart.
Building on Claude Desktop daily. A main window you can't move behind other apps is a workflow blocker, not just a minor annoyance.
@AnthropicAI - would love to see this prioritized.
github.com/anthropics/claude…
1
82
Correct link to bug on GitHub:
github.com/anthropics/claude…

1
34
Bharat Suneja retweeted

Jensen Huang says the rule for shipping AI is the same rule as shipping an omelet
"And in doing so, if it's not ready, just hold it back. You should go as fast as you can, but no faster than that."
"At the moment, the incidents are related to products not ready to be released. This is no different than, you know, an omelet's not ready to be released, or a car's not ready to be released, an airplane engine not ready to be released. You should properly test it, you have rigorous testing systems."
"The testing lab should be contained and products should not be released to the public until it's ready to be used by the public."
"And that's engineering, good old-fashioned engineering. It's not more than that, it's not less than that. And so we have to just go back to core engineering, make sure that we have the rigor of testing these products properly before we release it to the public."
_______
Link and more from AI-safety related conversations: firesidealpha.substack.com/p…

Sachin Katti says OpenAI had Astra optimize its own inference on NVIDIA's Rubin chip, adding another 2x in 72 hours
"It's a testament to NVIDIA's hardware that out of the box we got a 3x improvement in throughput. We literally took the same code that we had optimized for Blackwell, ran it on Rubin, got 3x improvement."
"Then, can we actually make Astra run agents using Astra as the base model, go optimize this inference of Astra itself on Rubin? It's a recursive loop. The model is figuring out how to optimize its own inference serving on Rubin chips, and over 72 hours the model produced another 2x improvement on the throughput."
"Things that would take weeks, if not months, to optimize in the past, we now are getting models that are very capable of actually producing over a weekend."
_______
Link and more from Sachin Katti's conversation: firesidealpha.substack.com/p…
Microsoft's Graph #PowerShell module is dropping Windows PowerShell 5.1 in v3.0 (Q4 2026).
PS 5.1 itself isn't going away, but it's been effectively frozen since 2016. Nearly 10 years with no new features.
Finally the forcing function I needed. Had almost 20 years of scripts (remember #Monad?) to migrate and kept putting it off.
Claude took 30 minutes. Updated everything. Modular PS 7.x profile, scripts, custom PS modules. Seamless.
Lovely time to be alive in this AI bubble.
72
Bharat Suneja retweeted

"LLMs are real, AI is fake" pluralistic.net/2026/09/12/g… @doctorow // @CNN @jaketapper please take note of this post for the next time you describe OAI/HF.
Explaining the issues of the "agents" and all the nonsense is weeks old already but still being incorrectly repeated.
