

Founder @Onehousehq — Data Infra for Agents. Creator of @apachehudi, built the first #DataLakehouse @Uber. Databases, Dist. Systems. LinkedIn, Confluent.
Joined April 2009
- Tweets1.5K
- Following235
- Followers1.9K
- Likes841





It's similar to how Snowflake or Databricks buy/reserve compute for years on hyperscalers, then resell as platform credits, right? As long as demand sticks, it works out?

Snowflake and Databricks arguing about AI revenue. Finally just something inexpensive from both companies: free entertainment. 🍿

Spark on Kubernetes is hard to run well. Our live session on the these hard parts had a great turnout. If you missed it, here's the full written guide.
Running Spark on Kubernetes looks deceptively easy. Most teams moving Spark from YARN to Kubernetes underestimate what YARN gave them for free. In reality, it's full of interesting problem solving on resource management and failure-handling.
Here's what the guide covers:
⚙️ Basics around how the driver, executors, and the K8s scheduler work together, pod mapping
🏛️ Why teams are moving from YARN: unifying all compute on k8s for deploys, access controls, chargebacks, and autoscaling
🧩 spark-submit vs. operators, and where adding YuniKorn or Volcano can help
💥 Production lessons from running this at Onehouse: OOM kills, shuffle storage without an external shuffle service, and driver failures
It starts small with SparkPi on a local kind cluster and builds up to what actually breaks at scale.
We hope you find it useful. Guide link in the comments 👇


While we are at it, can you all please also publish your numbers on closed vs open formats.
release all the numbers.
does 80% yoy become 65% when you remove passthru inference?
what does it become when you remove ai natives?
and how much of it is from one time software license --> service transition?
fcf, RPO, cRPO?
op margin non-gaap, gaap? dilution?
curious ppls want to know
ps: @alighodsi happy for your success. the world is big and life long.
teapaw.org/bhorowitz/status/21150…
If you want spare EC2 capacity, look at your Apache Spark clusters and then go give quanton.dev a shot.


Spark on Kubernetes at scale is hard. Onehouse runs a lot of it, and tomorrow we're sharing what we've learned.
In most places, the knowledge required to get all of this right lives across the data team and the Kubernetes/infra team.
We've collected a list of things that looked simple at first, but hard in production:
- OOM kills
- Shuffle storage
- Spot interruptions
- Autoscaling
- Long-running drivers
- Cluster upgrades
- Keeping streaming jobs alive while the infra underneath changes
Most of it lives in the gap between the data team and the infra team.
Webinar tomorrow. Bring your worst production problem.
Link in comments.

sign up link: onehouse.ai/events/webinars/…


Last week, I posted on why warehouses still default to closed formats. What I learned: they won't flip the default. Open formats are opt-in.
So the fix is with the users. Give every open format (Delta, Hudi, Lance, Vortex, ClickHouse, DuckLake) the same consideration on performance and flexibility that you give the closed ones.
Your data will thank you.
Back to building on open formats.

ALT A man in a field checks his watch repeatedly, while a skeleton lies nearby, humorously illustrating waiting for open file formats.
I like that the ChatGPT Mac app has a built-in markdown editor. It definitely reduces friction in review cycles.
Last week, Databricks CEO Ali Ghodsi and I debated Iceberg and open table formats on a post. Then I caught myself.
Why are we debating each other while Snowflake, BigQuery and Redshift still default customers to closed formats?
Two years of Iceberg announcements. Still no public retirement date for their closed formats.
Open-source projects get scrutinized for interoperability on every release. The largest warehouses should meet the same bar.
We’ve spent a decade building open formats and data lakes. I think it’s time we asked.

ALT Anakin and Padmé meme. Snowflake, BigQuery and Redshift in 2024: “The future is open. Use Iceberg.” Data community: “So you’ll retire your closed formats?” The same warehouses in 2026 say nothing, and the data community asks: “You’re still planning to retire them... right?
My thoughts and receipts are in the blog onehouse.ai/blog/snowflake-b…

To squeeze the performance out of our runtime components, we implemented a good amount of concepts from - SEDA: an architecture for well-conditioned, scalable internet services dl.acm.org/doi/10.1145/50205…
The seminal work at MIT around writing high-performance server software and the gift that keeps on giving.


Muse, Dots, Grok bot.
Eagerly awaiting the consumer AI/agent app explosion, to watch agents melt our databases at scale.


🙄 This is just confusing at so many levels.
First: historical data is several times larger than live data. How would a single-node SQL engine crunch all that data volume? Amazon itself sells three distributed SQL engines, last time I checked
Second: you can easily have your agent hit both Aurora and Athena and solve this problem today. What's broken?

A painful part of working with your data has always been that your live data and historical data are stuck in separate systems: the order a customer just placed lives in your database, while their last five years of orders sit in a data lake in S3.
And answering a real question usually needs both at once (is this a normal purchase for them, or should we flag it?), and to do that you had to move the data together first, copying history out of the data lake into your database (or the other way around), because the database couldn’t read it where it lived.
That meant guessing ahead of time which data you’d want, keeping a second copy of it all, building pipelines to move it, and constantly syncing so the two didn’t drift apart. A lot of plumbing, and slow going, all before you could answer one question. And even then, the answers were only as fresh as your last sync.
That now changes with Aurora PostgreSQL, which can call your live data and historical data in S3 together, in a single query. No copying, no pipelines to keep in sync.
And it’s fast, because we’ve built in DuckDB, a popular open source engine that’s really good at reading and analyzing data right where it’s stored. DuckDB reads the open formats like Parquet and Iceberg already sitting in your data lake, so there’s nothing to convert or move.
As folks build AI agents into their apps, the data their agent needs will depend on the task in front of it. Being able to query that specific data live, instead of copying it over just in case, is gonna be a big help for builders. aws.amazon.com/blogs/aws/ama…

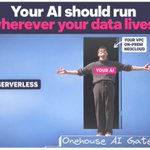
🚀 Introducing the Onehouse AI Gateway: model routing + MCP tool governance, without lock-in, wherever your data lives.
🔧 What is it?
A unified inference + MCP gateway with shared access controls and built-in observability at no extra-costs. Get blazing-fast SQL tool access to any open table. Swap models, connect any catalog, and deploy the gateway right next to your data or your agents.
💡 Why it matters
Snowflake’s Cortex AI Gateway routes only to Snowflake-hosted models. Databricks supports external providers, then charges $0.10/GB for inference logs and usage tracking. With Onehouse, you can use any model provider and store traces in open formats on infrastructure you control.
⚙️ How you use it
Add provider credentials (OpenAI, Anthropic, etc.), define model aliases, set fallback and traffic-splitting rules, and apply user/group access controls. Then point Claude Code or Codex at the gateway and go.
📊 We’re already running it on our own data lake. The blog has the full details.

