
https://teapaw.org/t.co/vlD2sAhx3c
localhost
Joined September 2023
- Tweets929
- Following19
- Followers965
- Likes2.1K






chDB retweeted

connected my Traefik server logs and my self-hosted analytics into the same ClickHouse MCP this week
honestly it is wild how easy it is to spot bots once your coding agent can join raw HTTP logs against JS analytics beacons across 24 sites lol
what 7 days of logs exposed:
- 43.7% of all "browser" analytics beacons (124,200 out of 284,132) were headless bots executing JS
- 71,519 beacons came from Meta's headless Chrome 145 renderer on IPv6 (2a03:2880:*)
- 10,438 "mobile visitors" came from 9,566 residential proxy IPs rotating 10 fake User-Agents (like CriOS/149.0.0.0, real iOS Chrome never ends in .0.0.0)
- 9,627 beacons came from 760 AWS Ashburn EC2 IPs pretending to be Windows desktops
- 2,817 "Direct" visits fetched HTML through residential proxies in Europe, then fired the JS beacon 1.5s later straight from Alibaba Cloud Singapore
- 2.24M requests (104 GB) were ClaudeBot (1.14M) and Meta AI (965k) stuck in an infinite ?tag=Energy/// hreflang loop (oops I think a technical seo issue on my side?)
normal analytics tools just show "Direct traffic is up 80%!" because they only see the JS beacon 😂 which it does now on my plausible, but I really can fix the Singapore / China bots now without blocking the entire countries in Cloudflare now I think (sorry @swSalim @hboon)
all this because I decided to just build my own datafast / coolify clone and merge them together ✊
chDB retweeted

Today's "Andy at Sea" Database Seminar: Sai Srirampur (@saisrirampur) will discuss how to tightly integrate @PostgreSQL with @ClickHouseDB. Public Zoom talk at 4:30pm ET. YouTube video available after: db.cs.cmu.edu/events/andy-at…

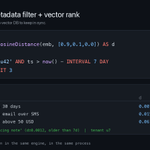
Asked "where does the user live?", cosine over agent memory put a 210-day-old "lives in Berlin" above last week's "moved to Lisbon".
In chDB, add age to the ORDER BY:
cosineDistance(emb, q) + 0.1 * (1 - exp(-dateDiff('day', ts, now()) / 30))
Stale top hits, 3 queries: 2 -> 0

chDB retweeted

I've been taking @ClickHouseDB managed Postgres and the new WAL Shadow integration for a test drive. This stack gives us the ability to create fully managed databases and then replicate data from Postgres to ClickHouse with sub second performance (~200 ms).
This is more than just another boring ETL mechanism.
With this level of latency, we can build applications where half of a screen or half of a user journey is served from a transactional database, and half is served by an analytical database. One blended application or workflow pulling consistent data from the most appropriate data store.
It also opens up new use cases where we can look at low level event data, and combine it with real time analytics across a whole population. For instance, we can take every trade, and compare it against the 100k previous trades in real time. This could be really interesting for fraud, personalisation or the capital markets.
In the example below, we have an trading scenario. Orders are placed, updated and cancelled for a book of exchange traded derivatives. The current state order book is shown and served out of Postgres. The data is immediately replicated into ClickHouse where analytics are then surfaced on the screen. We are pushing around 2.5k orders per second into a pair of small instances which would cost less than $500 per month.
Great work @saisrirampur and team!
Every row a data MCP server returns lands in the agent's context, so output format is a token bill.
Same 50-row, 6-column result, o200k tokens:
json.dumps: 2258
JSONEachRow: 1706
Markdown: 1282
TSVWithNames: 975
In chDB it's one argument: chdb.query(sql, "TSVWithNames")
If your production SQL leans on arrayJoin, uniqCombined or quantileTiming, chDB runs the exact same string in CI or a notebook, no dialect rewrite. Starting fresh from Parquet + pandas, that edge matters less. digoal on chDB vs DuckDB (in Chinese):
zhuanlan.zhihu.com/p/2099110…
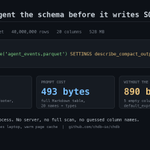
Agent sandboxes often run with the network off. Does your data layer still work there?
chDB, macOS sandbox-exec, all network denied:
Parquet, ORC, Avro, Arrow, JSONL and CSV, 1M rows each, one query: 0.11s
Fresh process incl. import: 0.18s
Every reader is built in.
SQLFrame 4.9 adds a ClickHouse engine: PySpark code compiled with SQLGlot's ClickHouse dialect and run over a DB-API connection. Its tests hand it a chDB connection, so the same Spark code runs on in-process ClickHouse, no server.
github.com/eakmanrq/sqlframe…
@eakmanrq

chDB retweeted

A fintech cut its analytics bill from $13,000 to $4,000 a month: AWS Glue and Athena to self-hosted ClickHouse, one layer at a time. p95 query latency 4.2 s, on par with Athena.
When you leave managed services, you own the monitoring. OpenTelemetry and Last9 went in on day one.
one2n.io/case-studies/migrat…

Agent memory needs forgetting. Skip the cron job; in chDB it's two lines of DDL:
emb Array(Float32) TTL ts + INTERVAL 30 DAY
TTL ts + INTERVAL 90 DAY DELETE WHERE importance < 0.5
1M memories, 6 months: 1.45 GiB -> 305 MiB after merge. Old turns keep text, drop vectors.
p90 of the same 10 orders ranged from 3900 to 12500 depending on which "quantile" you called. Solid walkthrough across pandas, Polars, DuckDB, Postgres and ClickHouse (run embedded via chDB), plus why to merge t-digest states, not average daily p95s.
habr.com/ru/articles/1096468…

chDB retweeted
A bit late to the Jev party, but we brought a benchmark 🎉
We used TypeSafe's Jev to label every failure on our agentic analytics benchmark and rank the tables each question needs: 0.951 nDCG@10 in 0.4 seconds.
clickhou.se/4BAEZSK

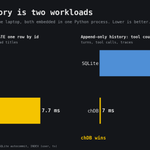
Agent facts change. Append every version, then ask what it believed at any point:
SELECT key, argMax(val, ts) FROM facts
WHERE user = 42 AND ts <= '2026-05-01'
GROUP BY key
2M versions, SQLite vs chDB:
1 user: 0.2 vs 2 ms
churn, all users: 78 vs 4 ms
disk: 144 vs 29 MB

No agent on the nodes: this Korean PoC embeds chDB in a FastAPI app, where refreshable materialized views pull system.query_log and system.metrics from multiple ClickHouse clusters via remoteSecure(), and ReplacingMergeTree FINAL drops re-read rows.
github.com/CYRok90/mini-logh…

Agent used .apply(lambda)? chdb.datastore keeps the rest in SQL:
e = c[c.status == "error"]
e["slow"] = e["ms"].apply(lambda x: x > 4000)
e.groupby("tool").agg({"slow": "mean"}).explain()
[chDB] WHERE
[pandas] apply
[chDB] GROUP BY
The lambda runs on 1M rows, not 20M.
chDB retweeted

We capture every single api key verification, http request or ratelimit decision in clickhouse. Maybe that's overkill...
but it comes in really handy when making any larger change to these systems cause I can just synthetically replay the exact production traffic patterns to compare their latency, accuracy to give us more confidence in shipping
chDB retweeted

How we improved bloom filters in parquet-rs [1], now adopted by ClickHouse [2]: pydantic.dev/articles/bloom-…
[1]: github.com/apache/arrow-rs/p…
[2]: github.com/ClickHouse/ClickH…
A Velib bike-network monitor with a neat dev setup: a 113-line shim serves ClickHouse's HTTP interface from chDB and replays clickhouse-connect's binary Native inserts through file(), so the real dbt-clickhouse adapter runs the full dbt build, no server.
github.com/ooFaycaloo/velib-…
