






Pinned Tweet
PDFs suck.
If you want to build standout RAG apps, you need tooling that is tailored to your needs.
You should own your doc parsing infra.
Today we’re launching chunkr.ai on @ycombinator
ycombinator.com/launches/Mud…


chunkr-layout-1 and our other models are live now on our API!
🌐 Website: chunkr.ai
📷 Hugging Face Dataset: huggingface.co/datasets/Chun…
📷Blog: chunkr.ai/blog/introducing-c…
chunkr retweeted

Introducing chunkr-layout-1. Layout is where document intelligence starts, we just leveled it up.
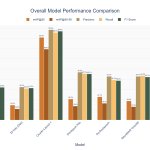
- Benched on 1,013 hand-tagged samples.
80.9 mAP@50 | 88.4 P | 85.6 R | 86.9 F1
- Beats AWS, Azure, Docling, Gemini 2.5 Pro, OSS models
- Identifies 16 class labels
Live now!

chunkr retweeted
I’m thrilled to announce our new VLMs, chunkr-parse-1 and chunkr-parse-1-thinking.
- Parses complex forms, tables & more
- Inline OCR (redlining and formulas)
- Multilingual (>100 languages)
- Beats AWS Textract, Gemini 2.5 Pro, Mistral at OCR
Live now on the Chunkr API

chunkr retweeted

Sweetspot does that: it can auto-detect fields (including from scanned PDFs) and fill out forms of 30+ pages using context from your organization

webhooks, live now!
docs.chunkr.ai/docs/webhooks…


chunkr retweeted
hello!
we are hiring @chunkrai
we are building best-in-class tools to help make the most out of documents. we're growing fast and are looking for a founding engineer to join!
if you
- like rust
- can handle features e2e
- are funny
lets talk!
ycombinator.com/companies/ch…


chunkr retweeted

use chunkr
by far the most accurate and developer friendly product in the OCR document processing space
Excels are notoriously hard to parse.
Even though they are machine readable, they end up as a flat string that loses semantic meaning of tables, styling and formulas. Agents can’t use it.
We’ve solved that.
Raw spreadsheets to perfect HTML, live now on the @chunkrai API.
chunkr retweeted
Excels are notoriously hard to parse.
Even though they are machine readable, they end up as a flat string that loses semantic meaning of tables, styling and formulas. Agents can’t use it.
We’ve solved that.
Raw spreadsheets to perfect HTML, live now on the @chunkrai API.
its always been a pain to meaningfully parse spreadsheets.
not anymore!

Excels are notoriously hard to parse.
Even though they are machine readable, they end up as a flat string that loses semantic meaning of tables, styling and formulas. Agents can’t use it.
We’ve solved that.
Raw spreadsheets to perfect HTML, live now on the @chunkrai API.
