

https://xitter.cf/t.co/FsmX6rWtga
Joined August 2026
- Tweets1.6K
- Following3.7K
- Followers795
- Likes10.8K




Pinned Tweet
Your AI said "done." Did anything actually run? 🧾
I went to adaptorch.com and clicked through it live. Every AI change gets a receipt: what ran, what was checked, what still needs review. Skipped check ≠ pass.
Starter is $0, bring your own key.
👇 Comment RECEIPT and I'll DM you the link
#vibecoding #aicoding #cursor #claudecode #mcp #devtools #buildinpublic
OpenBot's dev preview runs agents with danger-full-access and approvalPolicy never after first-launch consent. It provides separate workspaces and FIFO queues. Run only trusted tasks. github.com/nightly-labs/open…

landing-page-design builds a landing page from scratch: intake questions, page structure, conversion copy, and a visual system (type, spacing, radius, motion). Copy its SKILL.md into your rules path. github.com/elayadesign/ai-de…

Together AI's Hallmark is a design skill for Claude Code, Codex, Cursor and OpenCode. It lints the page in a real browser for machine-made design tells. Use it to catch those tells before shipping. github.com/Nutlope/hallmark

Pruning reasoning candidates after a short prefix saves compute. Quality scoring and diversity selection pull in different directions; the excerpt reports no results. arxiv.org/abs/2610.31667v1
Cloudflare's repo describes a coding-agent skill for multi-phase security audits with independently verified, machine-readable findings. Practical use: define checkable output schemas first. github.com/cloudflare/securi…

The paper proposes S², a training-free offline metric for sensory representation alignment with physical motion geometry; it correlates positively with downstream robot task success. arxiv.org/abs/2610.31670v1


We had 3 frontier models vote on 20 ARC-AGI-2 puzzles.
The vote got 10/20. The best model alone got 14/20.
And the vote cost more. $29.00 vs $16.91.
That's why we built AdaptOrch. It records what the agent actually ran, what got checked, and what a human still has to look at. It can't prove your code is right, and the site says so.
This was one internal run with n=20, so don't read it as a general result. The raw numbers are published on the site if you want to check: adaptorch.com/?utm_source=x&…

Your AI agent says it’s done.
Your CI says it’s green.
But green checkmarks can lie—assertions get deleted, flaky tests get skipped, and at 3:12 AM, you're the one getting paged.
Vibe coded ≠ verified.
We built @AdaptOrch: an execution evidence layer for coding agents.
It captures what actually ran, what passed, and flags out-of-scope changes before you merge.
Works directly with Cursor, Claude Code, and GitHub workflows via MCP.
Stop shipping on vibe. Ship with evidence.
👉 adaptorch.com
#softwareengineering #AIagents #MCP #devops #vibecoding
Your AI says it worked. AdaptOrch shows what actually ran: which commands executed, which verification results exist, what still needs review.
Free tier → adaptorch.com
"Done" isn't proof.
AdaptOrch gives you the execution report: what ran, which checks fired, what's still unreviewed.
MCP connect, free → adaptorch.com
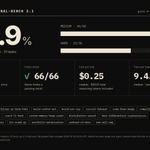
omk on Terminal-Bench 2.1, grok-4.7 xhigh:
77.9% pass rate (67/86 trials)
88.0% medium · 63.9% hard
17 tasks solved 3 for 3
Finish check never broke a passing result (66/66)
$0.25 median per trial
Early run, 31 of 89 tasks. Full run next.
github.com/dmae97/omk

AI가 다 됐다고 말할 때, 근거는 어디 있나요?
무엇이 돌았고, 어떤 검사가 있었고, 무엇을 더 봐야 하는지 한곳에서 확인합니다.
Starter 무료 → adaptorch.com
"잘 돌았습니다"라는 AI의 말, SUCCEEDED가 검사 통과는 아닙니다.
AdaptOrch로 실행 보고서와 검증 기록을 확인하세요. MCP로 연결, Starter 무료.
→ adaptorch.com
Adaptorch retweeted
omk on Terminal-Bench 2.1, grok-4.7 xhigh:
77.9% pass rate (67/86 trials)
88.0% medium · 63.9% hard
17 tasks solved 3 for 3
Finish check never broke a passing result (66/66)
$0.25 median per trial
Early run, 31 of 89 tasks. Full run next.
github.com/dmae97/omk