

🌈 Data Scientist @remax | sharing what I learn about software engineering, AI, data, and science | ignorant and curious
Tampa, FL
Joined March 2018
- Tweets549
- Following126
- Followers267
- Likes966




Ziyue Li retweeted

1/N I’m excited to share that our latest @OpenAI experimental reasoning LLM has achieved a longstanding grand challenge in AI: gold medal-level performance on the world’s most prestigious math competition—the International Math Olympiad (IMO).

Ziyue Li retweeted

These 94 lines of code are everything that is needed to train a neural network. Everything else is just efficiency.
This is my earlier project Micrograd. It implements a scalar-valued auto-grad engine. You start with some numbers at the leafs (usually the input data and the neural network parameters), build up a computational graph with operations like + and * that mix them, and the graph ends with a single value at the very end (the loss). You then go backwards through the graph applying chain rule at each node to calculate the gradients. The gradients tell you how to nudge your parameters to decrease the loss (and hence improve your network).
Sometimes when things get too complicated, I come back to this code and just breathe a little. But ok ok you also do have to know what the computational graph should be (e.g. MLP -> Transformer), what the loss function should be (e.g. autoregressive/diffusion), how to best use the gradients for a parameter update (e.g. SGD -> AdamW) etc etc. But it is the core of what is mostly happening.
The 1986 paper from Rumelhart, Hinton, Williams that popularized and used this algorithm (backpropagation) for training neural nets:
cs.toronto.edu/~hinton/absps…
micrograd on Github: github.com/karpathy/microgra…
and my (now somewhat old) YouTube video where I very slowly build and explain:
youtube.com/watch?v=VMj-3S1t…

Ziyue Li retweeted
Marketing speak to terms you already know:
semantic index -> embeddings
app intents -> function calling
on device language model -> 3B fine tuned LLM w/ included LoRA adapters
on device image model -> diffusion model w/ included LoRA adapters
orchestration -> Siri
Neural Engine -> Apple's GPU


Ziyue Li retweeted

Imagine a 3rd generation Apple Pencil that is compatible with Vision Pro 🤔
What would you use it for?
Ziyue Li retweeted

Google: 90% of our engineers use the software you wrote (Homebrew), but you can’t invert a binary tree on a whiteboard so fuck off.
Ziyue Li retweeted

‘Physical Open Waters’ addon for #blender3d is nearing an imminent release. This is the first glimpse of the UI and preset system.
It will come with ready-made presets. Or you can make your own unique waters and save/load with a single click.
Higher quality renders in 🧵👇


Ziyue Li retweeted

Just released: SDXL in 1 second using LCM LoRAs. No distillation required.
huggingface.co/blog/lcm_lora

Ziyue Li retweeted
You can now safely store your private keys, such as your @huggingface or @kaggle API tokens, in Colab! Values stored in Secrets are private, visible only to you and the notebooks you select.


Ziyue Li retweeted
Just fine-tuned an SDXL model on a blocky, colorful oil painting style known as 'alla prima'.
Used 50 carefully selected images.
The results? So beautiful, it's messing with my brain. 🎨


Ziyue Li retweeted

🚀Exciting news! Stability AI has launched StableCode, the revolutionary generative AI LLM for coding!
💡 Developers, get ready to level up your coding game! #AI #Coding #StableCode #StabilityAI
bit.ly/44Z8iO0
Ziyue Li retweeted

Liquid container generator for #SanctusLibrary
Bottles, flasks, vases, jars, cups... endless possibilities! #b3d #blender3d
Ziyue Li retweeted
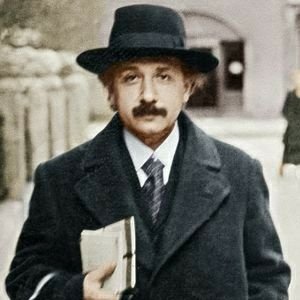
Richard Feynman was a brilliant physicist best known for his exceptional contributions to quantum mechanics and his captivating teaching style, among others.
Here are all of Feynman's Freely available Lectures at one place.
A Thread 🧵

Ziyue Li retweeted
Stability AI unveils Stable Diffusion XL 1.0, now available on Amazon Bedrock for developers worldwide #StabilityAI #AI #AIcommunity #TextToImage #OpenSource #AWS #SDXL
bit.ly/3O7N3Ch
Ziyue Li retweeted
Yay, llama2.c can now load and inference the Meta released models! :) E.g. here inferencing the smallest 7B model at ~3 tokens/s on 96 OMP threads on a cloud Linux box. Still just CPU, fp32, one single .c file of 500 lines: github.com/karpathy/llama2.c
expecting ~300 tok/s tomorrow :)