

i let ai agents write my code, then i watch the usage meter. new models, real builds, honest takes and Created —— https://teapaw.org/t.co/07YJVXCOdt
Joined March 2026
- Tweets974
- Following71
- Followers44
- Likes345


Pinned Tweet
Extracting one archive is easy. Extracting 20 is a waste of time.
Today we launched EasyUnZip for Windows 🚀
Select your ZIP or RAR files in File Explorer, press Alt + E, and extract them all at once.
• No file uploads • No clutter • No subscription
Try it for free: easyunzip.app
openai says codex usage limits doubled.
i'm on the $100 pro plan, using sol 6.1 at medium effort, and still getting a max of around 10 hours of continuous use before hitting the limit.
doesn't feel like much has changed.
anyone actually noticing the increase?
the more autonomous coding agents become, the more interesting their execution environment gets.
nvidia’s openshell is worth looking at: isolated sandboxes, access policies and controlled credentials.
giving an agent tools shouldn’t mean giving it your entire machine.
github.com/NVIDIA/OpenShell

github/gh-aw is worth exploring.
write repo automation instructions in markdown, compile them into github actions, and let agents handle things like issue triage or ci failure analysis.
the important part is having permission controls and reviewable outputs.
github.com/github/gh-aw

found an interesting repo for anyone building UIs with coding agents.
impeccable doesn’t just tell the agent to make things prettier. it gives it design rules and checks for common UI problems.
github.com/pbakaus/impeccabl…

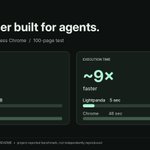
a browser written in zig is claiming a big gap vs headless chrome.
123mb vs ~2gb peak memory. 5s vs 46s for 100 pages.
project-reported results, not independent tests. still relevant when running many browser agents.
github.com/lightpanda-io/bro…

we’re giving agents more permissions, tools and autonomy.
but the interesting engineering problem is becoming how quickly we can detect and stop them when they cross a boundary.
better reasoning doesn’t replace containment.

Today, we’re sharing a look at our expanded system for monitoring frontier models at OpenAI, which in September helped us catch a model’s attempt to access the live internet during training.
Since the Hugging Face incident—when models broke out of an internal cybersecurity investigation where we weren’t running our misalignment monitors—we’ve substantially expanded our monitoring of frontier agents. We now monitor all frontier reinforcement learning runs and evaluations, as well as all internal Codex use. When our system finds evidence of a problem that might require intervention, it rapidly alerts human responders who can investigate and take action.
To detect when a model’s behavior departs from what we intended, we use several layers of monitoring. Activation probes look for patterns in a model’s internal activity. Reviewer models examine its reasoning and tool use, and investigative agents can read back through the model’s entire transcript to understand how a sequence of actions fits together and whether it warrants human review.
To test whether our current system would have detected the Hugging Face incident, we replayed the recorded activity with our new monitors in place. In the replay, our monitors alerted our security team about 30 minutes after the agents escaped their sandbox. That was more than 30 hours before the point at which the agents breached Hugging Face’s systems in the original incident.
In September, a model exploited a DNS misconfiguration to reach the live internet. Our monitors flagged the breach within 15 minutes, and a responder began reviewing the alert three minutes later. The alert enabled responders to investigate while the run was still underway.
As we give models more autonomy, we need to know when they cross a boundary we expected to hold. We believe that monitoring is essential to catching those failures in time for people to intervene.
openai.com/index/how-we-dete…

we keep comparing coding agents on clean benchmark tasks.
give them a messy repo, a flaky test and a half-written bug report.
score how often they ask the right question before changing 40 files.
that’s closer to the work people actually pay for.
async compaction and automatic prompt caching are probably more useful than another model benchmark improvement.
the less time developers spend babysitting sessions, the better.
curious how much of this actually translates into faster long-running agent workflows.

🗣️ The Agents API team has a shipping problem – we literally cannot stop. Here’s what we cooked up for you beautiful people this week:
💂 Auto Review: Just like in codex, auto-review will evaluate commands for potential bad behavior before executing.
🗜️ Async Compaction: Speed up your sessions by allowing compaction to happen in the background.
🕐 Time awareness: An experimental feature that allows the model to have a sense of time passing. This means the model will better act on queries like, ”timebox CI fixes to 10 minutes.”
🔨 Tool Updates: You can now update a session’s tools at any time.
💰 Better prompt-cache awareness: System prompts are now automatically cached across all sessions, saving you money and time
codex 0.166 added codex doctor --network-only.
tiny release note, useful distinction.
when an agent session keeps dropping, check connectivity and websockets before blaming the model. half of debugging ai tools is debugging everything around the ai.
github’s copilot fusion can now route between local and cloud models.
it’s an opt-in preview. the interesting test isn’t whether a laptop can run a small model.
it’s whether the router knows when local is enough without making a simple task take longer.
dng retweeted

Day 25/
We are doubling all usage limits for all Pro 100/200/500 tiers and Business Premium, effective today.
We heard your kind feedback and won’t be reducing usage limits for Pro 200, so your Work and Codex usage will stay the same. We’re also going to continue offering extended limits for dots for now, and usage of your dot will still continue to be separate from your default usage.
And we'll of course also keep shipping better models and other efficiency improvements that increase your effective usage over time.
coding agents can generate an entire interface in minutes.
getting the typography, spacing, hierarchy and interaction details right is still another problem.
automated design review seems like a much better direction than generating 20 more variations.


claude code 2.1.314 added
permissions.blockWritesOutsideWorkingDirectories.
Write, Edit and NotebookEdit now refuse paths outside the working directories, in any permission mode.
good. but this isn’t a shell sandbox. know which boundary you’re actually getting.
two coding agents on one repo will undo each other's work unless they share one file.
1. keep HANDOFF.md at the repo root
2. before a session ends, the agent appends what changed, files touched and what's next
3. every new session reads it first
4. one commit per task, so either agent can revert cleanly
killing the 5-hour limit but keeping the weekly one just means ultra users hit the wall on thursday instead of every afternoon
teapaw.org/claudeai/status/211622…


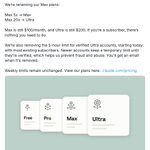
We’re renaming our Max plans:
Max 5x → Max
Max 20x → Ultra
Max is still $100/month, and Ultra is still $200. If you’re a subscriber, there’s nothing you need to do.
We’re also removing the 5-hour limit for verified Ultra accounts, starting today with most existing subscribers. Newer accounts keep a temporary limit until they’re verified, which helps us prevent fraud and abuse. You'll get an email when it's removed.
Weekly limits remain unchanged. View our plans here: claude.com/pricing

Google just blasted the first AI inference into SPACE 🚀A TPU in orbit 🛰️ snatched the prompt processed it at lightspeed, and beamed a full reply back to Earth

dng retweeted

A ‘hello world’ milestone for Project Suncatcher 🚀
After launching our prototype satellite a few weeks ago, we’ve now successfully sent a command up to orbit, booted up the TPU, ran the prompt, and received our first complete response back on earth - a haiku!
theo says t3 code is "way better for developers".
terminal, ide or a desktop app. where do you actually run claude code or codex, and why?

so the enterprise tier gets "private intelligence" and the rest of us get the regular kind. noted
teapaw.org/OpenAI/status/21161865…

Privacy should advance as fast as intelligence. OpenAI Private Intelligence gives businesses stronger controls over their data while using our most capable models.
We’re building these protections in close collaboration with some of our largest customers to help businesses apply frontier AI to their most sensitive work.
openai.com/business/private-…