

Where developers learn, build, and share. Your source for hands-on demos, cheat sheets, explainers and more.
Global
Joined October 2009
- Tweets10.6K
- Following185
- Followers65.9K
- Likes3.6K






Elastic retweeted
Two critical PHP RCEs are patched: CVE-2026-109618 and CVE-2026-109619, both CVSS 9.2.
• Fixed in 8.5.12, 8.4.27, 8.3.36, and 8.2.35.
You can still focus on detection coverage today.
Security Labs writeup (coverage + guidance): elastic.co/security-labs/thr…
Most PHP RCEs converge on the same outcome, whatever the bug: a web server process (php-fpm, php-cgi, apache2, httpd) doing something a request-serving daemon almost never does legitimately.
• a shell to confirm access: id, whoami, uname -a
• a second stage pulled in: curl http://... | bash
• a reverse shell: bash -i >& /dev/tcp//
• a webshell written into the web root
The bug class is public now: out-of-memory corruption, and stale state reused by the same worker. The behavior is what you detect.
We recently ran a different PHP RCE end-to-end (wp2shell): apache2 spawning dash to run id; whoami; hostname fired the exact rules that we suspect to catch php2shell. Payload Execution by Web Server kills the shell on the endpoint.
The Suspicious/Unusual Command, Child, and File Creation via Web Server rules stack on top.
(PHP did confirm partial php.ini mitigations. session.upload_progress.enabled=0 blocks the confirmed session paths only. Patch is still the fix.)
Patch to 8.5.12, 8.4.27, 8.3.36, or 8.2.35. Verify that the stack is enabled now.
Guidance + every rule link below.

Building search into a Java music library with plain Lucene, one step at a time.
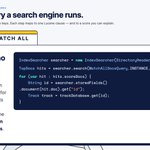
The tracks are indexed. Now we query them.
Should "Bob" in a title count for more than "Bob" in an album?
Step 1: start with no criteria. Open an IndexSearcher and fetch the first 10 hits. Each hit carries a Lucene doc number, so read the stored id and join back to your beans.


We're building search into a Java music library with plain Lucene, one step at a time.
Next up is analysis: what happens to your text before it reaches the index. An analyzer cuts it into tokens, lowercases them and folds the accents away.
Step 1: add lucene-analysis-common for ASCIIFoldingFilter. Pin the same version as lucene-core

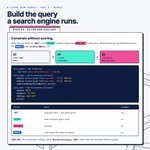
Step 3: filter and exclude.
Wrap the text query as MUST. Add a FILTER on genre = Club: 62 → 26 hits. Add a MUST_NOT on keys 4A or 4B: 26 → 23.
FILTER and MUST_NOT narrow the results without touching the score.
Gotcha: a query with only MUST_NOT matches nothing. When users exclude without typing, add a MatchAllDocsQuery as MUST.

Step 4: ask Lucene why a track ranked where it did.
searcher.explain(query, doc) breaks the BM25 score down per term: boost × idf × tf.
On a track with "bob" in both title and album, the title clause adds 10.77 and the album clause 4.08. So yes, the title counts for more.
Next: facets, counting what users can click.
Code for the series, built by @dadoonet github.com/dadoonet/lucene-s…


Why share an Agent Builder conversation instead of a summary? elastic.co/search-labs/blog/…

Stop moving Grafana dashboards by hand
Elastic’s tools make dashboard migration a whole lot easier: elastic.co/observability-lab…
We're building search into a Java music library with plain Lucene, one step at a time.
Next up is analysis: what happens to your text before it reaches the index. An analyzer cuts it into tokens, lowercases them and folds the accents away.
Step 1: add lucene-analysis-common for ASCIIFoldingFilter. Pin the same version as lucene-core
Step 2: build the analyzer chain.
StandardTokenizer splits the text. LowerCaseFilter lowercases it. ASCIIFoldingFilter turns "François" into "francois".
No stemming, so artist names stay intact. No stop words, so "Around The World" stays searchable.
Use the same analyzer at index time and query time, or your query terms won't match.

Step 3: the index holds terms, not text.
After commit, each term points to the documents that contain it. Look up artist:bob and you get docs 1, 2 and 3.
It works like the index at the back of a book: jump to the term, skip the scan.
Next: type "Bob" and build the query a real search engine runs.
Code for the series, built by @dadoonet github.com/dadoonet/lucene-s…

Elastic retweeted

📣 Attention #DevRel friends!
@elastic are hiring Senior Developer Advocates in NYC, US and Sao Paulo, Brazil. Job specs 👇 .
jobs.elastic.co/jobs/marketi…
jobs.elastic.co/jobs/marketi…
If you are based in these locations and have a background in #DevRel or software engineering, apply!

Full walkthrough with the ES|QL queries, alert rules, and a companion notebook that rebuilds the whole lab: go.es.io/4yVMeTm

Your beans are mapped. Now, who owns the index?
Step 1: wrap Directory + IndexWriter in a small class dedicated to your bean.
ByteBuffersDirectory for in-memory, FSDirectory to persist


Step 3: edit one row, not the whole index
updateDocument deletes by term, then adds, in one call.
Key it on the id StringField from part 1. It's never analyzed, so the term matches exactly.

Step 4: close the writer first, then the directory
Order matters
If request threads share the index, put every mutation behind the same lock.
Rule of thumb: upsert or delete for single-row edits, full rebuild for bulk changes.
Next: what happens to a token before it reaches the index.
Code for the series, built by @dadoonet github.com/dadoonet/lucene-s…

