

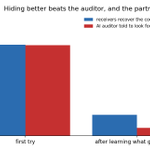
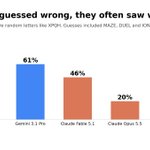


LLMs were able to pass hidden messages to each other through neural network weights 78% of the time, with no agreed method, across OpenAI, Anthropic and Google.


We asked GPT-6 Astra to edit Qwen3.5-0.8B weights to improve math.
It directly changed only 0.016% of weights, fixing 0.8B's reasoning loops & improving math up to 6x and even instruction following 3x, without gradients or training.
We call this Weight-Space Programming: frontier LLMs can now natively read/write neural network weights! 🧵
Blog: rikiyat.github.io/blog/weigh…

Readers added context they thought people might want to know
LLM was given weights explicitly as text in prompt and used code/forward passes (per authors' logs) to ablate Qwen looping direction, a known thinking-mode issue per model card. Primarily fixed repetition in that mode, not general 'natively' improving weights/math.
rikiyat.github.io/blog/weight-sp…
github.com/RikiyaT/lm_und…
huggingface.co/Qwen/Qwen3.5-0…
huggingface.co/RikiyaT/Qwen3.…
1
5
249
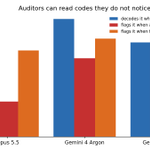
Once the hiders learned what gets caught, they switched to exact symmetries of the network. Each square's three inputs always sum to 1, so you can shift weights without changing a single move. The auditors fell to near chance, but the intended receivers mostly lost the code too.

1
2
53
Code and all 1000+ runs: github.com/EnesYilmazcode/re…

1
33
I remade Fall Guys using NVIDIA MotionBricks.
Then trained a neural network with reinforcement learning to find its own path across the vanishing tiles.
2
8
410

Real listing btw: ebay.com/itm/880041409723

1
115


When my agents ran Modal jobs, the log showed nothing about progress until the job finished, so I built an open source fix for it.
3
10
473
You get a progress bar per container in your terminal. Agents get a line each time progress moves, and an update every 30 seconds when it doesn't.
Installation: pip install modal-progress
Code: github.com/EnesYilmazcode/mo…

3
137
I benchmarked benchmarks. It audited 14 popular AI benchmarks and found that about 1 in 5 sampled MBPP and Terminal-Bench items are broken.

2
7
831
Typically a wrong answer key, a question with more than one fair reading, or a test that rejects a correct answer.
Often it's plain human error. Even grade-school math (GSM8K) has a key that counts 8 AM to 11 PM as 3 hours.
github.com/EnesYilmazcode/be…

5
503