
Research engineer, OSS crusader. Working on language models and rl. prev: null. rooting for @Jianlin_S
Joined March 2014
- Tweets805
- Following376
- Followers140
- Likes2.3K



i hate how i open this app for 5 minutes and end up with 10 tabs of new things i want to read...
i came here to take a break from what I actually need to be doing


you met me in a very chinese time of my life

Today we announce the launch of the Giotto family of models. We are unveiling Giotto Alto and Giotto Solo, the smartest European sovereign AI models on the market.
Giotto Alto is our flagship model built for advanced reasoning capabilities, free for everyone and available on the App Store and Google Play. It is hosted on European cloud infrastructure, so your data stays in Europe. Giotto Solo is the smartest model that runs on a single GPU, so organisations can keep their AI on their own infrastructure.
We are a Swiss lab with a European heart and we built this so that Europe can run advanced AI on its own terms.
Use Giotto: cloud.giotto.ai/

Readers added context they thought people might want to know
Giotto's graphic shows self-reported benchmark scores comparing to specific variants of other models; independent leaderboards as of late Oct 2026 list no Giotto and different leading scores on AIME 2026, GPQA-Diamond and HLE.
giotto.ai
benchlm.ai/benchmarks/aim…
benchlm.ai/benchmarks/gpq…
benchlm.ai/benchmarks/hle
the KL estimator only needs the sampled token, log-prob under q and p, which are already available in Tinker's normal importance-sampling interface.
so the fact that StableReinforce requires additional stability info from the sampler means there's more to this. might be top-k logprobs for score centering for example.

Off-policy RL is difficult; runs can suddenly collapse because of async RL staleness or numerical mismatch.
StableReinforce is a new method on Tinker that keeps your RL runs stable, even when learning drifts from sampling.
tinker-docs.thinkingmachines…
I've been a fan of DPPO for a while. PI has been running it as the default policy-gradient method for a while, but now they're switching to "IPO".
so what's changed?
1/n


DPPO proposes several alternatives, including binary total variation (TV) distance, which measures the absolute probability difference of the sampled token between the current trainer and the rollout policy. Imporance rtio still weighs the gradient, but TV is the masking criterion.
IPO also uses this!

Now, IPO uses only this distance as its masking criterion.
DPPO on the other hand retains PPO's asymmetric, advantage-dependent clipping. Updates are masked only when they would push the token's probability further away from the rollout policy and the divergence threshold has been exceeded. Updates that move back toward the generator are left untouched.
This means IPO is more conservative, DPPO preserves potentially useful corrective gradients, wheras IPO prioritizes stability at all cost by rejecting highly mismatched tokens altogether.


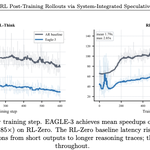
sorry to schmidhuber you here but speculative decoding was already explored by noam back in 2018 arxiv.org/abs/1811.03115


eagerly awaiting GLM 5.3 weirdml results.
pure rl scaling for a month, with heavy SWE focus, should be very interesting
wow, incredibly extensive post, and I appreciate how balanced the 0-mismatch cost/benefit discussion is given how much work went into achieving 0.
some thoughts:
- reproducibility deserves more credit as a benefit here. once your optimization signal has mismatch-induced bias baked in, it gets a lot harder to reason about changes to the RL pipeline, algorithmic or infra. did the run move because the algorithm changed, the serving stack changed, or some interaction between the two? reproducibility is kind of foundational to doing good science, and cutting out a major source of hidden variation seems worth it even if it doesn't show up in the headline reward curve
- Async RL shines as an unfortunate but necessary systems tradeoff.
- would've loved to see the comparisons plotted against wall-clock time instead of training steps. 0-mismatch is trading throughput for cleaner signal, and wall-time would make that tradeoff way easier to actually evaluate

