

Development economist @Macquarie_Uni | Tech adoption, beliefs, learning... but really I want to study ALL the things
Sydney, New South Wales
Joined July 2012
- Tweets10.9K
- Following1.7K
- Followers3.3K
- Likes19.8K




Pinned Tweet
After more years than any of us ever imagined, I'm so pleased to see this in print!
I also feel very lucky to have such awesome co-authors: @DaliaAGhanem Aleks @obcabanillas @TravisLybbert
& Jeff

Reanalyzing Suri (2011) We find instability in the parameter that governs who benefits most from technology adoption, consistent with weak identification. We propose a group random coefficient approach to diagnose it & construct robust confidence intervals econometricsociety.org/publi…

Emilia @econemilia.bsky.social retweeted

One paper. Then another. And another.
Next week, we’ll release findings from a large-scale investigation into data irregularities across papers with overlapping authors.
Duplicated observations. Unexpected patterns. Questions that kept leading to more papers.
Stay tuned.
Emilia @econemilia.bsky.social retweeted

Silicon Valley keeps building me a husband when what I really want is a wife lol
I don't want an agent that only does one-off, random tasks that are nice but not life-changing: booking flights, making dinner reservations, or buying tickets
I want an AI wife who knows what’s on the family calendar, remembers there’s a birthday party Saturday and we haven’t bought a gift then sends me options, realizes we’re almost out of diapers and buys them, knows which bills are coming up, remembers someone needs a dentist appointment and books it, figures out what the hell we’re eating all week and what we need from the grocery store, and generally keeps track of the 47 things that need to happen before anyone else even realizes they need to happen.
So, who's building me an AI wife that carries the mental load instead of an AI husband that waits for me to give it a chore??
Emilia @econemilia.bsky.social retweeted

Who knew we will have so many JMC apply!! Need help from generous mentors!! Please help!
@ideadevecon @AEAjournals @nberpubs @econmentoring

📢 Final call for AMIE Job Market Preparation mentors!
With 100+ mentees onboard, we’re looking for 25 more senior economists & researchers to support job market candidates through a one-on-one session.
📅 Deadline extended: Oct 9
🔗 docs.google.com/forms/d/e/1F…
#AMIE #Economics

Is it just me or do cloud sessions RIP through credits WAY faster than local sessions? I burned my $250 in 24 hours 😬

PSA: Don't forget that you only have another 2 days to claim this $250 credit for each of your Claude Max 20x subscription accounts.
If you have a bunch of accounts and don't log into the web app very often other than to swap accounts in Claude Code, it's easy to miss this.
You need to connect it to your GitHub account, which is very quick and easy if you're already logged into GitHub in the same browser. Then you just start a session, pick one of your repos, and give it a prompt to claim the credit.
If you're like me and don't even want to have to think much about this but want to make sure you get reasonably good utility out of your $250 credits, you can try this generic prompt that I've been using, shown below (adapted from a similar prompt I use with GPT Pro in the web app with the GitHub connector).
You can adapt it accordingly if you don't use beads or have a comprehensive plan document in the repo:
(also, another PSA: they gave everyone one banked reset per account that expires Oct 22 if you don't click the button in the "Usage" section in settings in the web app. But wait until you actually hit your weekly limit before clicking it, then do it right after that. Don't waste this potentially valuable reset!).
---
I have this now… can you work on it for me? Read the comprehensive plan and look at the beads first. Figure out the most momentous and critically important remaining gaps in features and functionality and focus on getting as much done of those things as possible in this session—not on minutiae or process/ceremony related tasks!!
Use GitHub to commit your changes directly to main (no PRs!!!!). Commit relatively frequently: don’t wait to do one big commit at the end, it’s too risky. But don’t commit absolutely trivial, tiny changes separately: wait until you have a meaningful commit.
And just keep going, being as useful as possible. Again, don’t focus on minutiae, focus on implementing the most critically important parts of the system that are incomplete! And commit directly to main using GitHub (I know for a fact that this works, just be persistent!).

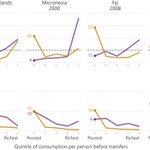
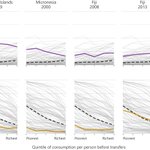
Debates about Pacific migration often discuss remittances as a share of GDP. That's useful for showing how much money a country gets, but tells us little about which households get it.
In a new @devpolicy post I take a look at data from household surveys: devpolicy.org/who-gets-pacif…

This was a fun exercise & made me think that we should be asking HOW to design state assistance to work alongside remittances (not whether remittances can replace social protection).
Also, why do poor households get so little of the money?
The data all come from the World Bank Atlas of Social Protection Indicators of Resilience and Equity (ASPIRE)
worldbank.org/en/data/datato…

IMHO we'll struggle to distinguish between "negligently sloppy" & "intentional fabrication" as long as journals accept replication packages with analysis-ready data.
@I4Replication
#EconTwitter

We have another @I4Replication report on #GDRI_rep. This time we replicate a paper originally published in the Economic Journal. Author responses can be found in the appendix. econstor.eu/bitstream/10419/…

In this case, many of the weird patterns in the paper COULD come from how the authors dropped observations, imputed missing values, or recoded variables. Without the raw data & the code that generated the analysis file, nobody outside the team can check whether they actually do.
Just call it the Negative Econometrica Tour, catchier
Plus, the evaluation penalty only applies if you have top pubs to "dilute," so most participants can join safely

LLM use that I've found quite useful: have subagent student personas go through assessments before finalizing them e.g. "anxious, literal reader," "complaint-prone," "skims instructions," etc. and write down stream of consciousness reactions + confusions
#HigherEducation #LLMs
Emilia @econemilia.bsky.social retweeted

Ooh, I have strong views on this! IMHO, pre-registration should not be a guessing game where the reward for guessing right is publication (or getting to call it pre-registered). A quick thread...

Emilia @econemilia.bsky.social retweeted

🚨Doctoral candidates involved in primary data collection research projects: SurveyCTO’s 2026 Primary Data Collection Research Grant is still open for ONE MORE WEEK.
You have until next Wednesday, September 30, to get your application in! Apply today 👉🏾 ow.ly/ptYc50ZrzK3

Emilia @econemilia.bsky.social retweeted

Some "overdue" news: my first paper on palm oil, started over a decade ago, was accepted for Christmas and is in print open access at the @JIntlEcon today. It's quite different from earlier versions, and the (excellent) review process improved it a lot.
sciencedirect.com/science/ar…


