

Marketing & AI | Founder @firsayai & @0penoffers | BD @frameonx | Amb @1inch
Joined September 2010
- Tweets34.6K
- Following2.9K
- Followers4.8K
- Likes62.1K


I built Firsay, my first truly useful tool for BD and outreach managers.
After more than 4 months of building, testing and breaking it, I can finally say: I made it happen.
you describe who you need in one sentence:
"find 10 BD managers at crypto exchanges on Telegram"
Firsay searches X, 8,000+ crypto Telegram chats, GitHub and the web, and keeps only people whose own bio proves the role.
→ every lead shows the exact line from their bio that proves it. no guesses
→ a public contact when there is one
→ never the same list twice. "find more like this" adds new people
→ drafts a personal first message from their real role and project
→ you send it from your own Telegram or X. it never asks for your login
→ works from Claude or Cursor too: "find 20 market makers and draft a message to each"
free to try, no signup. paid plans from $19/month.
And this is just the beginning.

Finding the right person in web3 used to take me hours
Scroll X, join 30 telegram chats, guess who still works where. half my DMs went to people who left the company a year ago
So i built Firsay
You write one sentence:
"find 10 BD managers at crypto exchanges on telegram"
You get real people. each one with the line from their own bio that proves the role, plus a public contact
- searches X, 8,000+ crypto telegram chats, github and the web
- "find more" adds 10 new people, never the same list twice
- writes a personal first message you send from your own account
First search is free, no signup
firsay.io

the creator of claude code just told everyone to delete their CLAUDE.md
good. delete it. delete the "be careful" prompt too
prompts are suggestions. the model reads them, nods, and does whatever the next token wants
the only part of my setup i'd never delete is 27 lines of python that aren't a prompt at all:
→ PreToolUse hook. runs before every single command
→ exit code 2 on git push, deploy, publish, rm -rf, rm -fr, terraform, kubectl, docker push, aws s3 rm
→ no "Verdict: PASS" in the review file → the task can't close
my first version was 21 lines and let 10 dangerous commands through
6 more lines → 31 of 31 blocked, 0 false alarms on 560 normal ones
grok finds it. 3 claude agents build it. the hook says no
full setup below ↓

Fluixo retweeted
170,000 people starred the most dangerous repo on github and 99% of them never opened a f*cking terminal
REA lets claude code, codex and grok build take apart any app on your disk. down to the byte. runs locally. MIT. free
what normal people did with it in ONE week:
→ lost the AC remote, turned the air conditioner into a mac menu bar app
→ got airdrop working on a linux laptop
→ opened a steam game they bought as a unity project in under 30 minutes
→ made plex open in 3 seconds instead of 30
zero reverse engineering experience. opus 5.5 on medium. not even max
the part nobody posted: compare_application_versions
diff two releases of any app and read the changelog they didn't publish
the full course with 15 copy-paste prompts is below ↓
elon just told millions of people to screenshot their credit card for grok bot
and amazon is already blocking it
an agent that can buy for you can also buy wrong for you. nobody installs the one thing that stops it:
→ a hook that runs before every action
→ exit code 2 on anything that spends, pushes, publishes or deletes
→ the agent asks. you say yes. then it runs
i tested mine on 591 real commands
v1, 21 lines → 10 dangerous ones slipped through
v2, 27 lines → 31 of 31 blocked, 0 false alarms
full grok + claude setup with the gate below ↓
YOUR CONTENT TEAM IS NOW ONE XML FILE. GROK + 3 CLAUDE AGENTS DO 48 JOBS FOR $1.30 AND THE 49TH JOB IS STOPPING THEM FROM NUKING YOUR PROJECT
screenshot the prompt. that's the whole team.
grok scouts. haiku digs. sonnet writes. opus kills anything without a source
the jobs it does every morning:
→ morning scout: 50 posts from 20 accounts you picked, one API call
→ engagement ranker: keeps the 10 people actually reacted to
→ evidence collector: every claim gets a link
→ draft writer: touches nothing outside output/
→ claim checker: no [S#], no sentence
→ verdict writer: PASS or NOT READY, nothing in between
and the jobs nobody talks about:
→ git push stopper
→ rm -rf stopper (and rm -fr, the one i missed)
→ terraform, kubectl, docker push, aws s3 rm blockers
my first gate was 21 lines. it let 10 dangerous commands through
6 more lines → 31 of 31 blocked, 0 false alarms on 560 normal ones
$0.25 grok + $0.08 haiku + $0.32 sonnet + $0.63 opus = $1.30
every agent file, every prompt and the 27-line gate below ↓

Fluixo retweeted
GROK AND CLAUDE CODE JUST BECAME ONE AI EMPLOYEE THAT CAN DELETE YOUR ENTIRE PROJECT IN ONE COMMAND
unless you add 27 lines of python
here's the team i wrote up:
01 Grok → the scout
x_search reads live X, up to 20 accounts you pick, last 7 days, real posts with links
02 Haiku 5.5 → research
read-only. tools: Read, Grep, Glob. turns posts into evidence
03 Sonnet 5.5 → the builder
writes the draft, only inside output/
04 Opus 5.5 → the verifier
reopens every source, writes PASS or NOT READY
the part nobody shows you:
claude code's own docs say the lead approves every teammate's plan without asking you
so i fed the safety hook 591 real agent commands
the first version let terraform apply, kubectl apply, docker push and rm -fr straight through
6 more lines → 31 out of 31 blocked, 0 false alarms
the whole run costs about $1.30
full setup, scout script, all 4 agents and both hooks below ↓
Fluixo retweeted
GROK AND CLAUDE CODE JUST BECAME ONE AI EMPLOYEE THAT CAN DELETE YOUR ENTIRE SERVER IN 0.3 SECONDS → UNLESS YOU ADD 27 LINES
here's the 4-agent setup i run, from one X trend to a reviewed result
01 Grok → the scout
reads live X, pulls the posts and threads people are actually reacting to, hands back links and one-line summaries
02 Haiku 5.5 → the research crew
model: haiku
tools: Read, Grep, Glob
read-only, maps sources and returns evidence
↳ code.claude.com/docs/en/sub-…
03 Sonnet 5.5 → the builder
turns the evidence into the draft, writes only inside output/
04 Opus 5.5 → the verifier
reopens every source, writes PASS or NOT READY
↳ code.claude.com/docs/en/agen…
the clever part:
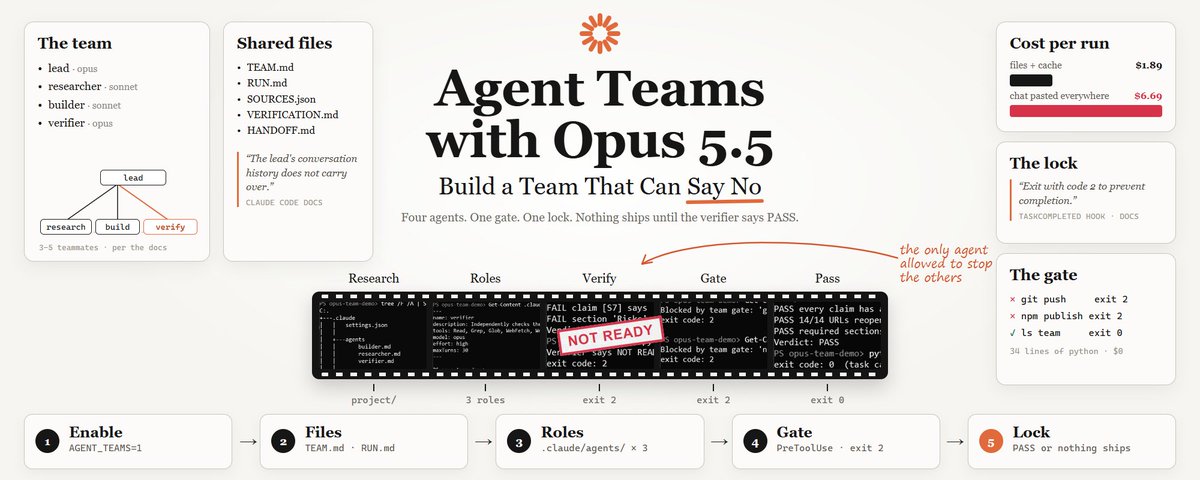
TaskCompleted hook → exit 2 until the verifier writes PASS. the task literally can't close
PreToolUse hook → blocks git push, publish, deploy, rm -rf, terraform, kubectl
i fed that hook 591 real agent commands
31 dangerous ones blocked, 0 normal commands blocked by mistake
the loop:
X trend → Grok scout → Haiku research → Sonnet build → Opus verify → you approve
full setup, both hooks and all 4 agent files below ↓
GROK AND CLAUDE CODE JUST BECAME ONE AI EMPLOYEE THAT CAN DELETE YOUR ENTIRE SERVER IN 0.3 SECONDS → UNLESS YOU ADD 27 LINES
here's the 4-agent setup i run, from one X trend to a reviewed result
01 Grok → the scout
reads live X, pulls the posts and threads people are actually reacting to, hands back links and one-line summaries
02 Haiku 5.5 → the research crew
model: haiku
tools: Read, Grep, Glob
read-only, maps sources and returns evidence
↳ code.claude.com/docs/en/sub-…
03 Sonnet 5.5 → the builder
turns the evidence into the draft, writes only inside output/
04 Opus 5.5 → the verifier
reopens every source, writes PASS or NOT READY
↳ code.claude.com/docs/en/agen…
the clever part:
TaskCompleted hook → exit 2 until the verifier writes PASS. the task literally can't close
PreToolUse hook → blocks git push, publish, deploy, rm -rf, terraform, kubectl
i fed that hook 591 real agent commands
31 dangerous ones blocked, 0 normal commands blocked by mistake
the loop:
X trend → Grok scout → Haiku research → Sonnet build → Opus verify → you approve
full setup, both hooks and all 4 agent files below ↓
ELON'S AI AGENTS JUST DESIGNED A CAR THAT DOES 0-60 FASTER THAN YOU BLINK → SPACEX THRUSTERS INCLUDED
he owns the AI company → he owns the car company → he owns the rocket company → he plugged all three together and let the agents cook
xAI's grok agents ran autonomously for 4 months → simulated 11,000 thruster configurations → the same cold-gas propulsion that lands Falcon 9 boosters is now bolted to a $200,000 hypercar
here's what each agent handled:
grok build → thruster integration
took SpaceX's cold-gas thruster blueprints → adapted them for a 2-seat car → 4 thrusters, 4 white plumes, 1.4g pinning you to the seat
grok 4.6 (500k context) → aerodynamics
ingested the entire SpaceX aero database in one prompt → ran CFD across 250+ mph scenarios → optimized downforce so the car doesn't lift off the ground at full thrust
grok bot → full pipeline
CAD → simulation → testing → production specs → autonomous 24/7 → zero coffee breaks, zero equity requests
the specs:
0-60 ..................... 0.59 seconds
top speed ................ 250+ mph
range .................... 620 miles
propulsion ............... SpaceX cold-gas thrusters
designed by .............. GROK 4.6 autonomous agents
price .................... $200,000
what took the original roadster team 4 years of engineering → grok agents compressed to 4 months
sam altman's agents write code
dario amodei's agents write code
elon's agents just designed a car with rocket thrusters that does 0-60 faster than you blink
save this → full roadster breakdown in the thread
my safety rule let 10 dangerous commands through. 6 more lines and it lets through 0
i gave my agent team one rule: nothing dangerous runs until i say yes. 21 lines of python. it blocked git push and deploys, and i thought i was done
then i fed it 591 commands an agent team would actually run, and 10 dangerous ones went straight through without a warning. terraform apply, kubectl apply, docker push, aws s3 rm. rm -fr got in because i had only written rm -rf
i added 6 lines and ran the same 591 again. 31 out of 31 blocked, nothing slipped, and it didn't block a single normal command by mistake
the rule is in the article, with all 4 agent files
who the f*ck let my "reviewer" agent approve its own homework... i am never building an agent team without a lock again
2am. my agent team says "done ✓"
i almost hit publish
then i opened the work
→ 3 claims with no source
→ 1 section just missing
→ the reviewer agent had written "looks good" and closed the task
turns out the claude code docs say it out loud: the lead approves every teammate's plan automatically. nobody asks you
a reviewer that can't stop "done" is just a comment with an avatar
so i wrote a 13-line rule: no task closes until the reviewer writes PASS
→ no review file: blocked
→ "NOT READY, 2 problems": blocked
→ "PASS": task closes
13 lines, $0 a run, and "done" finally means done
the rule and all 4 agent files are in the article below ↓
who the f*ck let my AI agents delete files and push to production... i am never trusting a safety rule i didn't test again
i gave my AI agent team one safety rule: nothing dangerous runs until i say yes
it looked clean, 21 lines of code, it blocked "push to github" and "deploy the site"
then i tested it the hard way, 591 real commands an agent team would run, and 10 dangerous ones walked straight through
→ terraform apply: rebuilds your servers
→ kubectl apply: changes what runs in production
→ docker push: ships a new version to the world
→ aws s3 rm: deletes your cloud files
→ rm -fr: wipes a folder, because i only blocked "rm -rf"
no warning, no pause, nobody asked me
so i added 6 lines and ran the same 591 commands again
→ 31 out of 31 dangerous commands blocked
→ 0 slipped through
→ 0 normal commands blocked by mistake
27 lines of code, $0 to run, and my agents finally can't break anything without me
the full setup, the safety rule and all 4 agent files are in the article below ↓
THAT 20-AGENT CLAUDE CODE TEAM IS A $120,000-A-YEAR F*CKING SCREENSHOT
$9,999 a month instead of $567
The trick is not more teammates
It is fewer teammates that can't step on each other
Most "I run 20 AI agents" posts end the same way
one screenshot of a full agent panel
twenty names
twenty context windows
one giant chat pasted into every single one
two agents editing the same file
one silent overwrite
one "it's basically a company now" reply
That is how a crowded terminal gets fucking mistaken for a team
Claude Code's own docs say it plainly
start with 3 to 5 teammates
token costs scale linearly
three focused teammates often outperform five scattered ones
Same model
Same task
17x the bill
20 agents with the chat pasted in: $33.33 a run
4 agents reading shared files: $1.89 a run
A big team does not need to be fake
It only needs to stop being your flex
The panel gets the screenshot
The four get the work done
Full setup below ↓
Follow me, I take apart what is real and what is theater in AI agents every day
YOUR AI AGENT TEAM IS BURNING $43,200 A YEAR ON F*CKING COPY-PASTE
$4,545 a month instead of $945
8 agents, 10 runs a day, one giant chat pasted into every single one
600K tokens of "see above", paid as fresh input, 8 times, every run
Opus 5.5 reads cached files at $0.20 per million
fresh input costs $4
that's the whole trick
Send this to your lead agent and thank me later:
"Audit what every teammate gets. Move rules to TEAM.md, the task to RUN.md, links to SOURCES.json, old chat to 10 lines in HANDOFF.md. Spawn teammates with a 3-line prompt that points to the files. Never paste chat. Price the run before and after and write COST.md."
$15.15 a run → $3.15
same agents, same model, same work
The paste gets you the vibe
The file gets you the margin
Full setup + the cost math below ↓
Fluixo retweeted

Operator Uplift is live now in @solanamobile
An app to help you build better habits and keep your word (only possible on @solana)
fleg went into X Spaces with $0 and came out with a bag
no team
no VC
no roadmap
just one green frog with a banger detector
everyone in that Space was still arguing about AI agents
fleg was already 3 bangers deep
net worth: $0 → $∞
(frog math, don't ask)
this is the most bullish thing on my timeline today
This quoted post is unavailable.