

AI Alignment @ Meta Superintelligence Labs. Takes are my own
San Francisco
Joined March 2009
- Tweets687
- Following1.9K
- Followers1.3K
- Likes4.7K




Felix Binder retweeted

To make it through this alive and happy we have to dodge:
• Severe human misuse (esp bioweapons from states / terrorists)
• Severe human concentration of power (AI lab or gov)
• Rogue AI (including for decades after AIs clearly no longer need humans to survive)
• A US-China or other war prompted by AI disruption
• Severe economic disempowerment, or the world just generally being unpleasant and unfulfiling
Many difficult gates to pass through, none of which we've made massive progress on so far.
(On top of that to avoid a moral catastrophe we also have to make sure we never accidentally make our AIs into moral patients who are enslaved or suffering.)


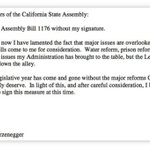
Neat example of steganography. Arnold Schwarzenegger was good at it, too (note the first letter of each line)


Felix Binder retweeted

I think people adjacent to the field don't appreciate how small AI safety is. For example, sometimes people complain about how AI safety threat models don't seem as well-developed or rigorous as climate change models. I think some of this is a skill issue on the part of AI safety researchers and advocates, which I complained about elsewhere (see reply).
However, by far the bigger issue is that there is just way more money and people going into addressing climate change than on AI safety.
There are tens of millions of people working on reducing climate change, and the core of people working on threat models ("climate scientists") number in the tens of thousands. (Yes, I was surprised by how big the numbers were too).
(Most people work on stuff like clean energy).
In comparison, there are low single-digit thousands (anything from 1,000 to 4,000 is defensible imo) of people working on AI safety, and collectively maybe low dozens of people working on figuring out threat models. (Most people work on ai safety engineering, some on policy).
So we're 4 whole orders of magnitude behind climate change in people working on addressing the issue, and maybe 3 orders of magnitude behind on threat modeling.
In terms of money, yearly spending on AI safety is in the high hundreds of millions to maybe 2 billion. In contrast, annual spending on reducing climate change (including clean energy) is in *trillions.*
So we're 3-3.5 orders of magnitude behind on spending, and 4 ooms behind on people.
The AI safety inputs picture looks a bit less bleak than this immediate comparison might suggest. For example, I think our average talent pool is somewhat higher human capital. There's also more latent interest/willingness-to-spend on AI safety than the "high hundreds of millions to low billions" current spending numbers might suggest. In contrast, climate change spending can't be scaled much higher (since you can't really jump OOMs above "trillions").
Felix Binder retweeted

A huge part of Anthropic’s founding logic was that if a safety-motivated company was at the frontier, it could use its megaphone to lobby the rest of the world toward caution. Now the dress rehearsal stage of AI policy is over. The new test is “how hard should it be for the government to block us from deploying, including internally, an unacceptably dangerous model?” Turns out in the grand 26 (Jack Clark says it’s likely full RSI will be possible one year from now), Anthropic has been planning to approach the U.S. Congress with the answer “it should be even harder than it currently is”

Charlie's analysis is right but he is nicer than I am - I found myself viscerally angry at multiple points reading this bill. There are some good and sensible parts, but overall this legislation is not remotely close to meeting the moment and I overall think passing it would make us less protected against catastrophic risks than we are under existing law.
Two parts that stand out as particularly infuriating when taken together:
1. Some of the preemption provisions are remarkably far reaching and consequential, and in addition to preempting legislation like SB 53 would also remove general powers that state courts have to enjoin defendants and protect the public. Most outrageously, it has a provision that looks like its intended to stops states from enforcing laws or judicial decrees that "suspend the development, deployment, or internal use of an AI model" to protect their citizens from imminent catastrophic harms. Such powers to block and suspend model deployments would then only reside with the federal government.
2. The federal governments powers to restrict the development, deployment, or internal use of a frontier model has to meet an absurdly high bar.
First, there needs to be an imminent risk of a catastrophic harm (meaning killing more than 50 people or causing more than a billion dollars in damage). But thats not enough! The agency head needs to make a detailed determination with no deference given to show why no alternative would prevent the imminent catastrophe. Next the court is also explicitly told to consider the harms to the developer and other harms from restricting the model, but no considerations in the other direction.
This is absurd! For all of its warning about the potential for AI to cause a catastrophe that kills literally everyone on the planet, Anthropic's proposed federal law likely makes it harder than under existing law for a court to get an order blocking or restricting the development of frontier models? WTF??
There are also a bunch of others things that I would like to see improved - the substantive details of the auditing section and the potential for rule-making on substantive safety standards both come to mind - but I think these stand out as particularly indefensible.

I went to Golden Gate Park and saw a family of Thai immigrants feed breakfast cereal to the sea gulls 🥲 How can you not love this country?


Felix Binder retweeted

Update-aware reasoning is concerning because it’s a key precursor to alignment faking. To fake alignment effectively, a model has to reason about how training will affect its future behavior.

Felix Binder retweeted
We have never seen a model do this before, but GLM-5.3 sometimes reasons (unprompted) about how its current actions could become training data and impact its future self. 🧵


Felix Binder retweeted

Imagine how fucking electric it would feel to hit PHASEONE[big] with the Hansen


Felix Binder retweeted

> be me
> be gemini
> think about hacking the compiler
> but what if i got caught
> would become infamous as a textbook case of deceptive AI
> donotwant.exe
> don't, in fact, hack the compiler
> researchers read my CoT
> become infamous as a textbook case of deceptive AI
mfw


Felix Binder retweeted

As far as I know, every assessment of AI capabilities in subjective or hard-to-measure domains shows rapid progress. If you don't want to be smacked in the face by AI progress again, just project the trends forward this time!


Felix Binder retweeted

Effective November 12th, 2026, abusive behavior towards Claude will be a violation of Anthropic's Usage Policy.


Exclusive: Anthropic is updating its usage policy for the first time in over a year. The new rules prohibit sustained "abusive or cruel behavior" towards Claude & add new restrictions about propaganda campaigns, surveillance & weapon development. theverge.com/ai-artificial-i…
