

Scientist @amazon, photographer, substandard musician but a linguistic genius
Melbourne, Victoria
Joined July 2013
- Tweets46
- Following61
- Followers92
- Likes275
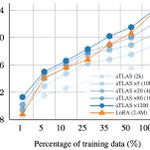




Is the low-rank formulation a necessity in parameter-efficient fine-tuning? In our #ICLR2025 paper, we proposed a full-rank PEFT method that outperforms LoRA across vision and language tasks, while maintaining parameter and memory efficiency.

New paper at ICLR 25 !
arxiv.org/abs/2502.00987
github.com/PaulAlbert31/Rand…
We evidence the low-rank bottleneck of LoRA, showing that scaling trainable parameters isn't always enough.
Plus, RandLoRA optimizes gradient computation to reduce memory use over LoRA !
#peft #ICLR2025
6
289
Excited to announce that the codebase for our #neurips2024 paper Knowledge Composition using Task Vectors with Learned Anisotropic Scaling (arxiv.org/abs/2407.02880) is now available. In this paper, we showed how to combine or transfer the knowledge across different models. [1/6]

(5) aTLAS is a strong PEFT method, especially when data is limited. In addition, exisiting PEFT methods such as LoRAs can be seamless integrated into aTLAS for better memory efficiency. [6/6]

88
(3) aTLAS is complementary to previous few-shot methods, in that one third of the examples it improves upon are unique; (4) aTLAS is robust to domain shift and achieves better generalisations on out-of-domain datasets; [5/6]

68
We show that (1) aTLAS implicitly exploits the low intrinsic dimensionality of pre-trained models, leading to few learnable parameters; (2) It is particularly effective in low-data regimes, and improves CLIP by 6.5 points in accuracy across 22 datasets with unlabelled data; [4/6]

67
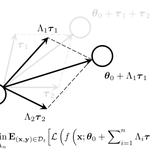
We learn an independent scaling coefficient for each parameter block of the task vector, e.g., weight matrices or its partitions, resulting in anisotropic scaling at the task vector level. We test our method across five different applications and reveal interesting insights [3/6]

1
60
We propose aTLAS, an algorithm that simplifies otherwise complex problems to learning a linear combination of task vectors. The task vectors, which are weight deltas between a pre-trained model and its fine-tuned variants, have been shown to encode task-specific knowledge. [2/6]

79
Frederic Zhang retweeted

In our first Researcher Spotlight, Dr. Frederic Zhang, AIML Postdoctoral Fellow, shares insights into his work on 'task vectors'—a method for improving multitasking in machine learning. Learn more and watch his interview: youtu.be/Rhe7AV2MPUg #AI #machinelearning

Frederic Zhang retweeted
I just posted the first of what will be several chapters about transformers, which in the last year has been the most requested topic for the channel.
youtu.be/wjZofJX0v4M
I’ll be presenting our paper in person for the first time! If you are interested in human-object interaction detection, come check out our poster (#147) in Room Nord this morning from 10:30 to 12:30. #ICCV2023 @dylanjcampbell_ @sgould_au


It was quite a rollercoaster ride with so many decisive games before the tie breaker. Most enjoyable WCC I’ve ever watched!

Ding Liren wins the 2023 FIDE World Championship 🏆
Congratulations to Ding on becoming the new FIDE World Champion, and cementing his place in chess history after a thrilling match! 👏

2
162
Frederic Zhang retweeted

My mind is blown 🤯🤯🤯
go to any github repo but use github.dev instead of github.com
it's now VS code IN BROWSER

Frederic Zhang retweeted

This is a baby GPT with two tokens 0/1 and context length of 3, viewing it as a finite state markov chain. It was trained on the sequence "111101111011110" for 50 iterations. The parameters and the architecture of the Transformer modifies the probabilities on the arrows.
E.g. we can see that:
- state 101 deterministically transitions to 011 in the training data, so the probability of that transition becomes higher (79%). Not near 100% because we only did 50 steps of optimization.
- state 111 goes to 111 and 110 with 50% probability each, which the model almost learns (45%, 55%).
- states like 000 are never encountered during training, but have relatively sharp transition probabilities, e.g. 73% of going to 001. This is a consequence of inductive biases in the Transformer. One might imagine wanting this to be 50%, except in a real deployment almost every input sequence is unique, not present in the training data verbatim.
Not really sure where I was going with this :D, I think it's interesting to train/study tiny GPTs because it becomes tractable to visualize and get an intuitive sense of the entire dynamical system. Play with here: colab.research.google.com/dr…

Frederic Zhang retweeted

Announcing GPT-4, a large multimodal model, with our best-ever results on capabilities and alignment: openai.com/product/gpt-4
Frederic Zhang retweeted

What if you actually could build Rome in a day? Prof Richard Hartley is one of the founders of Multiview Geometry, which establishes the construction of 3D models from sets of images or videos. He receives the Hannan Medal for his pioneering work.
Frederic Zhang retweeted

Thrilled that our workshop on "Generative Models for Computer Vision" got accepted to #CVPR2023!
We have a fantastic speaker lineup with whom we will discuss how image synthesis can benefit image analysis.
Stay tuned! :-)

Frederic Zhang retweeted

I'm recruiting for a 1-year postdoc to work at the intersection of object tracking and NeRF models. @ANUComputing
jobs.anu.edu.au/cw/en/job/54…
Applications close 23 October 2022. Ideal candidate will preferably be able to commence by January 2023. Contact me if you're interested.