






A $1.4 trillion valuation for Anthropic being treated as "modest" tells you everything about where AI capital is concentrated.
That is enough capital to back 1,000,000 independent AI builders with $1M each.
The next wave of AI breakthroughs won't come from one giant balance sheet it will come from removing the compute bottleneck for developers everywhere.
Build without gatekeepers on @gpunet.
Explore the ecosystem: world.gpu.net/

Board investigations. Congressional hearings. Geopolitical chokepoints.
The global AI stack sounds like a political drama because silicon supply has become far too centralized.
The real vulnerability is single-point dependency.
Your ability to ship AI shouldn't rely on the fate of one boardroom or one executive.
That is why we are building a distributed compute fabric at @gpunet: world.gpu.net/
🤖 Made with AI

**1/7**
Most AI teams pick compute providers with a broken framework.
They scan top-10 listicles, compare raw H100 hourly rates, and choose the cheapest option.
Six months later, they’re locked in. Here’s the framework that actually works for where to run your AI workloads.
**2/7**
Stop asking “Which provider is best?”
Ask these five questions first:
• Workload shape: Heavy batch training or 24/7 low-latency inference?
• Budget stage: Bursty pre-seed testing or steady-state Series A scaling?
• DevOps bandwidth: Can your team orchestrate multi-provider infrastructure?
• Compliance: Do you need strict HIPAA/SOC 2 regional boundaries?
• Growth spikes: Can your infrastructure scale 10× instantly without quota delays?
**3/7**
Understand the market split:
• Hyperscalers (AWS/GCP): Strong IAM/MLOps ecosystems and compliance, but premium pricing, high egress fees, and slow quota approvals.
• Neoclouds: Fast raw compute, yet you bet uptime on a single vendor’s physical limits.
• Aggregated fabrics (@gpunet): Global supply, lowest market-clearing rates, and dynamic scaling across distributed nodes.
**4/7**
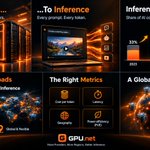
The biggest rookie mistake is treating training and inference as the same workload.
• Training: Needs massive centralized clusters, high inter-node bandwidth (NVLink), and “train once” batch economics.
• Inference: Needs low latency, regional distribution, fast cold starts, and ruthless cost-per-token optimization.
You serve forever. Build the stack accordingly.
**5/7**
The staged roadmap for AI infrastructure:
• Stage 1 (Pre-PMF): Stay 100% on-demand. Never lock into reserved contracts. Prioritize checkpointing discipline and flexible pay-per-hour compute.
• Stage 2 (Early scale): Separate training and inference clusters. Run 60-day spend models to test if reserved silicon pays off.
• Stage 3 (Scale): Abstract away single-vendor lock-in with open container standards and decentralized compute fabrics.
**6/7**
This is where @gpunet fits the modern AI stack.
Instead of rigid cloud contracts or manual vendor negotiation, it unifies global compute supply into a single fabric:
• NVIDIA H100s from $2.20/hr
• Instant B200 & Blackwell reservations
• OpenAI-compatible GLM 5.3 inference at $0.15/1M tokens
**7/7**
The future of production AI will not run on a single walled-garden cloud.
It will run on a global compute fabric that routes workloads by cost, geography, and latency.
Explore the full @gpunet compute, model, and yield ecosystem:
world.gpu.net/

🌐 Explore the entire @gpunet ecosystem in one place
All products & services on a single platform
👉 world.gpu.net/
Quick start
Connect your wallet
Access GPU Renting + GPU RWA on the main page
Hit the ☰ menu (top-right) for everything else
What you can access
• ⛓️ Ganchain ($GPU staking + validator rewards)
• 🖥️ GPU Marketplace
• 💰 GPU RWA
• 🎨 AI Generators
• 🤖 AI Agents
• 🔌 API Pricing
• 📚 Docs & Blogs
• 👥 Team
• 🏢 Enterprise & Data Centers
One platform. Full ecosystem.
Visit now → world.gpu.net/


GPU Rex retweeted
@gpunet first RWA Pool batch was successfully completed. ✅
Now, the next opportunity to access tokenized GPU hardware investments is here.
📈 Target APR: 20%
💵 Minimum: $1,000
💰 Returns in USDC at the end of the term
Explore the RWA Pool 👇
world.gpu.net/
Real hardware. Real compute. Tokenized access.


GPU Rex retweeted

GPUNET Cloud is live 🔥
Need serious compute? Rent a GPU in minutes.
🔸 Use the default SSH key or bring your own
🔸 Compare offers by count, location, interconnect and provider
🔸 Pick your OS and SSH key, then launch
Link: cloud.gpu.net/
GPU Rex retweeted
Drop-in replacement. Unbeatable token economics.
@gpunet Models is officially live 🔥
Switch your provider in 1 line of code:
• ⚙️ 100% OpenAI-Compatible API
• 🧠 GLM 5.3 starting at $0.15 / 1M tokens
• 🔑 Instant API key generation
• 💻 Plugs natively into cURL & the OpenAI SDK
Stop paying single-provider premiums.
👉 Claim your API key: cloud.gpu.net/models
Drop-in replacement. Unbeatable token economics.
@gpunet Models is officially live 🔥
Switch your provider in 1 line of code:
• ⚙️ 100% OpenAI-Compatible API
• 🧠 GLM 5.3 starting at $0.15 / 1M tokens
• 🔑 Instant API key generation
• 💻 Plugs natively into cURL & the OpenAI SDK
Stop paying single-provider premiums.
👉 Claim your API key: cloud.gpu.net/models
GPU Rex retweeted

RWA #2 is filling 🔥
Target: $250,000
🔸$1,000 minimum
🔸20% APR
🔸Paid in USDC at the end of the term
🔸Target term under 12 months
Link: ganchain.gpu.net/rwa-pool

GPU Rex retweeted
1/
Feels like we've spent the last two years obsessing over training.
Bigger models. Bigger clusters. Bigger training runs.
Meanwhile, the economics of AI are shifting somewhere else:
Inference. 🧵
2/
Training gets the headlines.
Inference gets the bill.
Frontier-model training costs are measured in the hundreds of millions.
But once a model is deployed, every prompt, every agent action, and every generated token becomes an ongoing expense.
You train once.
You serve forever.
3/
The data is moving fast.
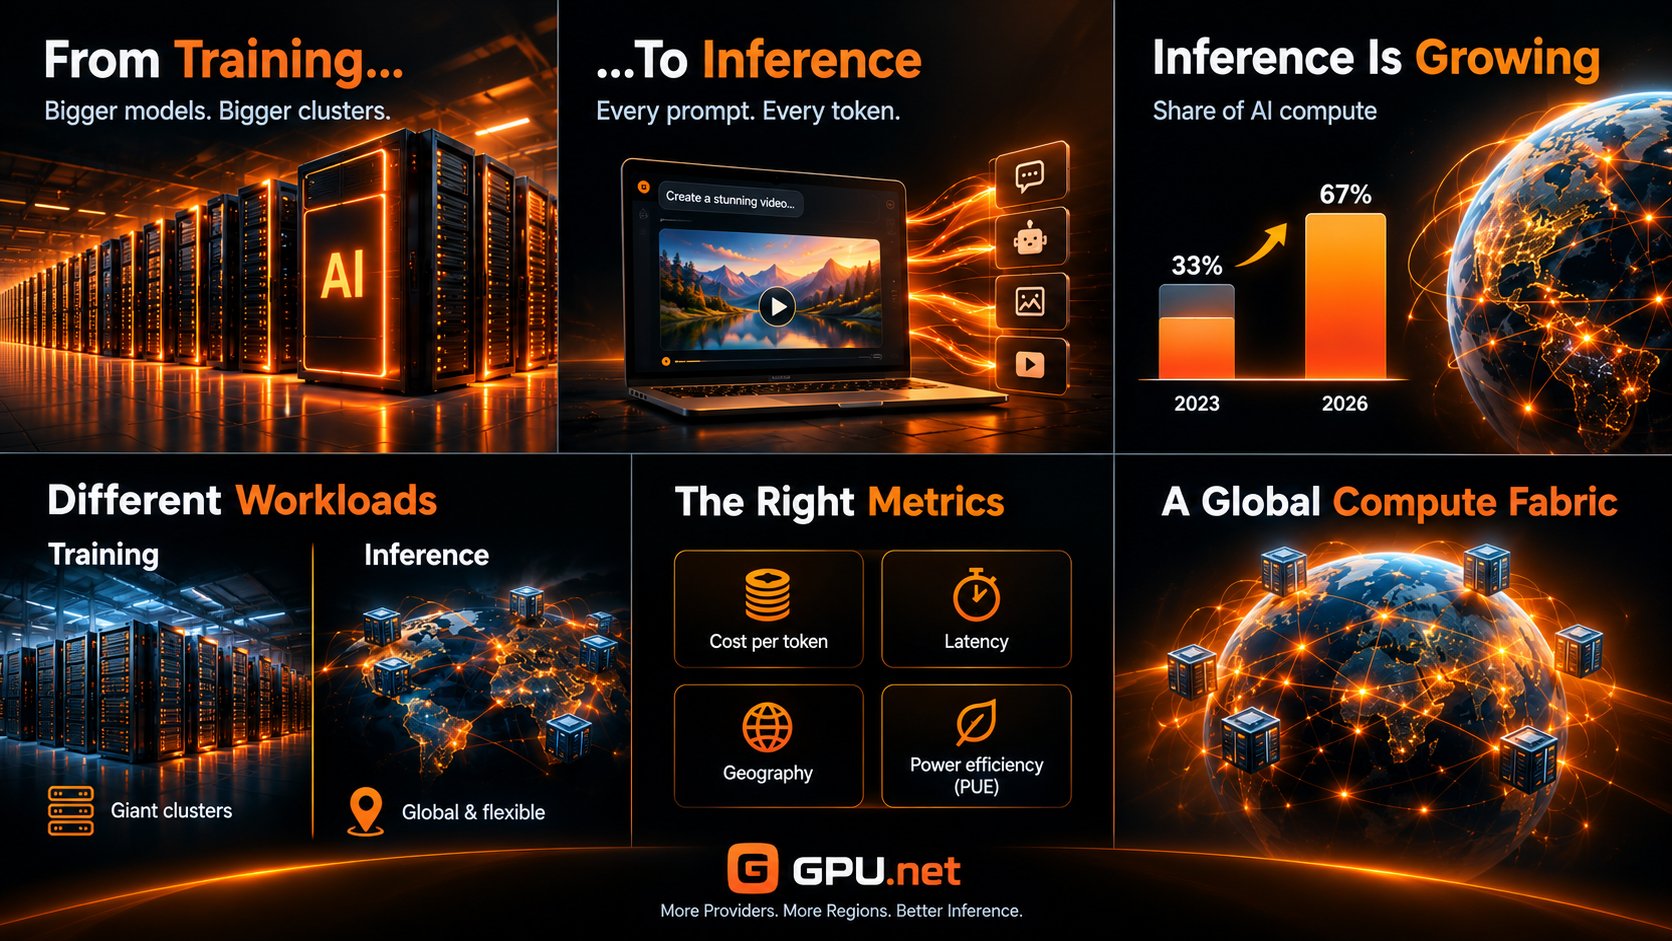
Inference represented roughly 1/3 of AI compute in 2023.
Deloitte projects it will reach roughly 2/3 by 2026.
That's a massive shift in just a few years.
4/
The mistake many teams make?
Treating training and inference like they need the same infrastructure.
Training wants giant centralized clusters.
Inference often benefits from: • Lower latency
• Regional deployment
• Better cost efficiency
• Proximity to users
Different workload. Different priorities.
5/
For production AI, the key metrics aren't just FLOPS anymore.
They're: • Cost per token
• Latency
• Geography
• Power efficiency (PUE)
That's where margins are won or lost.
6/
The challenge is that compute is fragmented across hundreds of providers and regions.
That's where @gpunet comes in.
Instead of manually researching infrastructure, teams can compare providers, discover available capacity, and find infrastructure that fits their inference workload.
The future of AI won't run on a single cloud.
It will run on a global compute fabric.
#AI #GPU #DataCenters #InferenceAI
1/
Feels like we've spent the last two years obsessing over training.
Bigger models. Bigger clusters. Bigger training runs.
Meanwhile, the economics of AI are shifting somewhere else:
Inference. 🧵
2/
Training gets the headlines.
Inference gets the bill.
Frontier-model training costs are measured in the hundreds of millions.
But once a model is deployed, every prompt, every agent action, and every generated token becomes an ongoing expense.
You train once.
You serve forever.
3/
The data is moving fast.
Inference represented roughly 1/3 of AI compute in 2023.
Deloitte projects it will reach roughly 2/3 by 2026.
That's a massive shift in just a few years.
4/
The mistake many teams make?
Treating training and inference like they need the same infrastructure.
Training wants giant centralized clusters.
Inference often benefits from: • Lower latency
• Regional deployment
• Better cost efficiency
• Proximity to users
Different workload. Different priorities.
5/
For production AI, the key metrics aren't just FLOPS anymore.
They're: • Cost per token
• Latency
• Geography
• Power efficiency (PUE)
That's where margins are won or lost.
6/
The challenge is that compute is fragmented across hundreds of providers and regions.
That's where @gpunet comes in.
Instead of manually researching infrastructure, teams can compare providers, discover available capacity, and find infrastructure that fits their inference workload.
The future of AI won't run on a single cloud.
It will run on a global compute fabric.
#AI #GPU #DataCenters #InferenceAI
GPU Rex retweeted
The biggest problem with AI video generation isn't quality it's control.
Astra Video by @gpunet changes that:
Upload your starting frame
Set your target ending frame
Adjust camera angles & motion intensity
Render in seconds
Powered by the SeeDance engine on GPU.net’s decentralized GPU network meaning top-tier output at fraction-of-a-cent compute costs.
Full creator control without the random morphing.
👉 legacy.gpu.net/astra/video
The biggest problem with AI video generation isn't quality it's control.
Astra Video by @gpunet changes that:
Upload your starting frame
Set your target ending frame
Adjust camera angles & motion intensity
Render in seconds
Powered by the SeeDance engine on GPU.net’s decentralized GPU network meaning top-tier output at fraction-of-a-cent compute costs.
Full creator control without the random morphing.
👉 legacy.gpu.net/astra/video
GPU Rex retweeted
The complete @gpunet compute, yield, and AI product suite at a glance:
🖥️ GPU Cloud : Enterprise H100 rentals starting at $2.20/hr + B200 & Blackhole reservations
👉 cloud.gpu.net/
📈 RWA Pool : Tokenized GPU hardware investments delivering 20% APR ($1,000 min)
👉 ganchain.gpu.net/rwa-pool
🪙 GPU Staking :Stake your GPU tokens to earn massive APR
👉 ganchain.gpu.net/
🤖 AI Models : Managed model hosting & inference with pay-per-token API pricing
👉 legacy.gpu.net/models
🎬 Astra Video : Pay-per-second AI video generation with zero monthly sub traps
👉 legacy.gpu.net/astra/video
🎨 Astra Image :High-res image creation at fraction-of-a-cent compute costs
👉 legacy.gpu.net/astra/image
⚡ Astra Agents : Low-latency, automated AI agent execution stack
👉 legacy.gpu.net/astra/agents
🌐 Access everything across the @gpunet world on a single page:
👉 world.gpu.net/

The complete @gpunet compute, yield, and AI product suite at a glance:
🖥️ GPU Cloud : Enterprise H100 rentals starting at $2.20/hr + B200 & Blackhole reservations
👉 cloud.gpu.net/
📈 RWA Pool : Tokenized GPU hardware investments delivering 20% APR ($1,000 min)
👉 ganchain.gpu.net/rwa-pool
🪙 GPU Staking :Stake your GPU tokens to earn massive APR
👉 ganchain.gpu.net/
🤖 AI Models : Managed model hosting & inference with pay-per-token API pricing
👉 legacy.gpu.net/models
🎬 Astra Video : Pay-per-second AI video generation with zero monthly sub traps
👉 legacy.gpu.net/astra/video
🎨 Astra Image :High-res image creation at fraction-of-a-cent compute costs
👉 legacy.gpu.net/astra/image
⚡ Astra Agents : Low-latency, automated AI agent execution stack
👉 legacy.gpu.net/astra/agents
🌐 Access everything across the @gpunet world on a single page:
👉 world.gpu.net/
GPU Rex retweeted
5M $GPU have been minted as part of our planned liquidity expansion.
This marks the first release from our 20M liquidity bucket, with 5M planned each month.
The goal is simple:
🔸 Increase circulating liquidity.
🔸 Support more trading volume.
🔸 Strengthen liquidity for upcoming listings.
$GPU is entering its next phase ⚡️