



Pinned Tweet
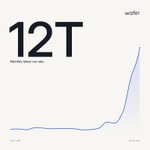
The biggest bottleneck in the GPU industry at the moment is not chips, CoWoS, or even power. It's credit.
Sharing some thoughts on compute markets, residual value, and where compute financing is heading.
Substack link in the comments.

Eugene Ye retweeted

excited to partner with @Vercel to power Token Pass!
for $30 per month, your team gets $80 in monthly credit for:
- GLM 5.3,
- Kimi K3
- DeepSeek V4.1 Flash 1017
powered by Wafer, with more models coming soon!
available as an add-on to Vercel Pro.
links in thread 🧵


Eugene Ye retweeted

Introducing the Haight Street Compute Market.
A one-day trading floor where vetted buyers and sellers of compute meet and sign deals in person. Nov 17, at the old Federal Reserve building in San Francisco.
Request your invite: luma.com/86cjwpui
Eugene Ye retweeted

personal update: i quit investment banking
and joined @wafer_ai as chief of staff
thank you to my goats @gpuemi @gpusteve @gpugene
we’re hiring ranked gamers: jobs.ashbyhq.com/wafer

no one is ready for the chopped Cloud

keep SF Tech Week going at Wafer After Hours 🎮
this month it's a Smash Bros tournament
one champion. unlimited bragging rights. 🏆
poker and more to play, then drinks at House of Shields
sat oct 10, 7-11pm in San Francisco. request an invite:
luma.com/z54figtk

Eugene Ye retweeted

Just like with oil, the market outside the majors is the true marginal market for compute.
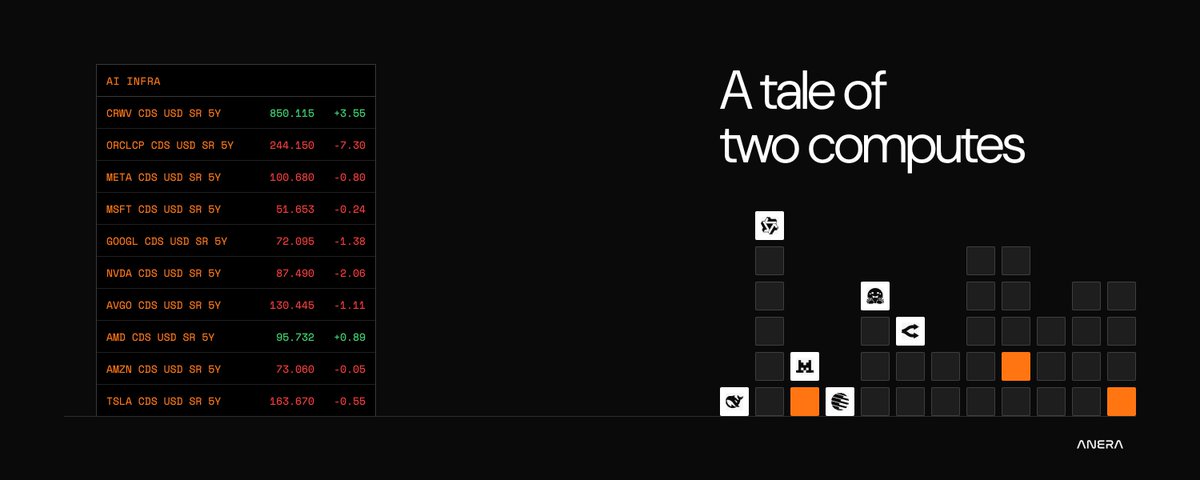

being able to trade and hedge your compute is the unlock inference companies need to grow faster and offload risk.
if I sell a customer fixed-price service while my GPU bill floats, I've taken a position on compute prices whether I meant to or not.


Eugene Ye retweeted
Wafer beat Cerebras on latency for @ycombinator's AI Office Hours.
GLM-5.2 on Wafer averaged 379 ms versus 674 ms for Gemma 4 31B on Cerebras.
that's 44% lower latency with a much larger model.
YC wanted people to get startup advice from AI versions of its partners at conversational speed. after testing lightweight Gemma and OpenAI models, they moved to a dedicated Wafer endpoint.
Wafer agents tuned the serving setup for YC’s request rate, cache usage, and prompt and response lengths.
users spent 2.5 minutes longer talking to its AI partners on Wafer compared to other providers.
read how YC built the experience and landed on Wafer
🧵 link in thread

Eugene Ye retweeted
@brilliantorg 3x’d their tokens per second and cut inference costs by 50%, by making its AI tutor fast enough to answer in real time instead of speculatively prefetching answers.
To keep Koji, their AI tutor, responsive during math and coding lessons, the Brilliant team was speculatively prefetching AI-generated responses so students wouldn’t have to wait.
On Wafer's dedicated GLM-5.2 endpoint, Brilliant reached ~250 ms time to first token and 300+ output tokens per second. This was a 3x throughput increase over their previous provider.
That speed let Koji answer learners in real time, so the Brilliant team could stop pre-generating responses and remove the prefetching layer.
Read how Brilliant made the switch!
🧵 Link in Thread

Eugene Ye retweeted
we launched the most comprehensive ai performance engineering repo in the world
now we'll be posting every single resource
follow and save to keep up with the series. links in thread 🧵
part 5: Roofline: An Insightful Visual Performance Model for Floating-Point Programs and Multicore Architectures
the authors introduced a model for relating arithmetic throughput, memory bandwidth, and data reuse. applied to AI workloads, it gives a way to evaluate batching and kernel optimizations against the hardware's limits.
the paper's concepts connect to these AI performance decisions:
operational intensity measures floating-point work per byte of DRAM traffic after cache reuse. during dense transformer decoding, a linear layer processing a small token batch can read a large weight matrix for little arithmetic.
compute and bandwidth roofs bound throughput. if weight reads limit an inference kernel, reducing transferred bytes can lower its memory-time bound. increasing peak arithmetic throughput alone leaves that bound unchanged.
the ridge point marks the minimum intensity needed for peak compute throughput to be possible. batching tokens that share a weight matrix can increase work per weight byte, moving the matrix multiplication toward that threshold.
computation ceilings account for limits in instruction parallelism and operation mix. for neural-network matrix multiplication, check Tensor Core use and compare throughput with the roof for the kernel's execution path and precision.
bandwidth ceilings account for memory access patterns and data placement. for GPU tensor operations, changing the layout or thread-to-data mapping to coalesce scattered accesses can improve useful bandwidth.
data reuse raises intensity when it reduces DRAM traffic for the same arithmetic work. a tiled matrix multiplication can reuse operands on chip; measure whether that reuse reduces DRAM byte traffic.
the memory level determines which bytes to count. if a matrix multiplication reuses operands from L2, compare its L2 traffic with L2 bandwidth and its DRAM traffic with DRAM bandwidth.
the authors demonstrated the model with 4 floating-point kernels on 4 multicore systems. for AI performance work, use it to assess weight reuse, memory layout, and arithmetic execution before choosing an optimization to test.


Eugene Ye retweeted
Nope. OpenAI and Anthropic trending towards a duopoly would be negative for AI infrastructure demand and a disaster for the application layer.
Eugene Ye retweeted
Inference providers hate this man...
Your LLM deployment can deliver 30 to 50% better performance after initial deployment.
If your current inference provider isn't learning your workload and tuning the stack continuously after deployment, you need another provider.
Wafer's continual inference agents do that work.
Wafer's continual inference agents profile your production workload to identify where scheduling, decoding, or GPU memory pressure limits performance.
The agents benchmark changes to batching, serving engines, and GPU kernels against your workload. Each candidate must preserve correctness and meet your reliability targets before it ships.
The agents keep profiling as traffic changes, identifying new bottlenecks and further opportunities to improve performance per dollar.
Watch @gpuemi explain how that work continues after deployment in his conversation with theCUBE.
Eugene Ye retweeted

Why am I so focused on networking over raw compute?
Look at GPU utilization 53% of surveyed data center operators report running at only 50–70% capacity during peak demand.
GPUs aren't sitting idle because they lack compute power, they're sitting idle because they're waiting for data. They wait on storage, they wait on CPUs, and above all, they wait on other GPUs to send results back across the network.
If you add more compute to a cluster without upgrading the pipes, you just get diminishing returns on your capex.
$LITE $COHR $AAOI $CRDO
