

Software Engineer pre AI - TensorFold Contributor - Local LLM builds for DGX Sparks - Engineering Mentor to 1,200+ AI builders.
Bangkok, Thailand
Joined February 2026
- Tweets2.1K
- Following131
- Followers1.2K
- Likes690




Pinned Tweet
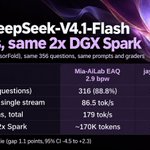
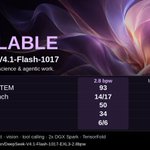
My DeepSeek-V4.1-Flash-1017 quant is NOW LIVE for TP=2 DGX Sparks.
Same 353 questions for all three packs:
new / Mia 2.9 / my old q28-v2
MMLU-Pro STEM: 93 / 91 / 90 (of 100)
LiveCodeBench: 14 / 11 / 11 (of 17)
MBPP+: 50 / 49 / 50 (of 60)
HumanEval+: 34 / 34 / 33 (of 40)
SciCode: 6 / 6 / 5 (of 10)
MATH-500: 36 / 36 / 36 (of 40)
MGSM: 40 / 40 / 40
BFCL tool calls: 39 / 39 / 39 (of 40)
Multi-step tool chains: 6/6, 6/6, 4/6
These are small samples, so I read it as "at least as good, in a smaller pack". It's not a blowout.
The gaps I care about are LiveCodeBench and the tool chains, which my old quant kept dropping. Calibrated it for coding, science and agent work.
Weights/Recipe are in the comments. Recipe has been updated with my current config but is mostly unchanged.
@MiaAI_lab I still don't know how you get them so good. I can't wait to use your Engine Aware Quant (EAQ) system when it's ready.
2.8 BPW, EXL3, 203.8 GB, running on two DGX Sparks with @ashxhart TensorFold.
- 1M context
- image input
- 2.1M-token cache total with NVMe offload.
As usual, if you have any issues, please let me know or submit a PR.
What will you throw at it first?

Just wanted to give an update on LocalRouter. I am working on a few new tools and some of the feedback.
Nothing is quite ready yet, but it's moving quickly
Nearly ready
- Jev style decision model for computer use.
- Remote companion and choose-your-own harness.
- Smaller quant for Dramma thanks to @plotarmordev
Also porting my companion mobile app over too, but I want to ask a question.
I don't want to deal with App Store submissions right now (Maybe later).
Would you prefer an Expo app that you would need an Expo account for, or a raw swift/kotlin build that you can just download to the device directly?
Both would just work over Tailscale. Let me know below!


LocalRouter AI assistant. One DGX Spark. Full duplex.
This actually feels like Jarvis in a box! Built on @ashxhart TensorFold
🧠 Qwen 27B
🗣️ Drama 3 with streaming (Thanks @plotarmordev )
🖼️ Qwen Image Turbo 2.1
🎬 MiniMax H3 video
👂 Whisper STT
~0.5s after I stop talking, it starts with its first word. Interrupt it anytime. Set the delay as you please for responses.
Normal models stay loaded and can be swapped as needed.
Want a video model up? Then Whisper and Drama will make space. Once the video is generated, start voice back up when the video is finished.
The goal is actually fully modular, so consider this a super early version of what it could be. MCP by default, but also ships with a simple UI you can extend as you please.
Thin by design, so everyone can make it their own.
What features do people want next? What about TP=2 or Mac Studio versions?

Well, the easy part is done. How the heck am I going to get 500k verified impressions without showing any bobs....
Maybe I can start a new SaaS product called OnlyAI. Just edging people with AI tokens and usage.

Quick reminder to store database backups and preferably externally of the core system.
Most people won’t want to pay for snapshots but would you rather lose 95% of your data or pay $20 per month.
Also @lockpickapp can help protect you in the first place.

This was a very good model to use, and I tried to get early access ☹️
Now working on a quant and will have a recipe coming with TensorFold. Please give me a few days.

MiniMax M3.1 Flash weights are now public. 428B parameters total, 23B activated per token.
Agentic performance: A generational leap in agentic tasks, coding, and cybersecurity — 76.2 on BankerToolBench, 73.7% on DeepSWE v1.1, 61.7 on OSWorld V2, 29.6 on Agents' Last Exam, and 82.2 on CyberGym.
Efficient by design: MiniMax Sparse Attention and DSpark speculative decoding improve inference efficiency.
Hugging Face:
huggingface.co/MiniMaxAI/Min…
ModelScope:
modelscope.cn/models/MiniMax…
API: platform.minimax.io
M Plan: minimax.io/m-planMiniMax
MCode for desktop: agent.minimax.io/download

Here are some of the people that I have learned from over the last few months/years.
This isn't everyone, but it's a great starting point if you are interested in AI, software engineering, or local hardware.
Later, I want to share more underrated people I missed. Please comment anyone you think I can learn from, and I will be sure to follow them! 🙂
Software Engineers (Super technical)
@webdevcody (Super technical in-the-weeds engineer)
@poteto (Unlimited AI usage but very cool skills)
@mattpocockuk (Very technical engineer and architect)
General AI knowledge and amazing tips
@MarkKashef (Amazing skills, tools and workflows)
@MatthewBerman (Very consumer AI tips but no BS)
@BetterStackHQ (More software than AI but some very good lessons)
Local Hardware and AI engines
@0xSero (Pushing local hardware)
@ashxhart (TensorFold)
@RaidOwlTweets (Homelab and networking)
Local AI
@bertholomusai (Very underrated local recipes)
@plotarmordev (Very cool niche models and config)
@MiaAI_lab (The Local AI Goddess)
LocalRouter AI assistant. One DGX Spark. Full duplex.
This actually feels like Jarvis in a box! Built on @ashxhart TensorFold
🧠 Qwen 27B
🗣️ Drama 3 with streaming (Thanks @plotarmordev )
🖼️ Qwen Image Turbo 2.1
🎬 MiniMax H3 video
👂 Whisper STT
~0.5s after I stop talking, it starts with its first word. Interrupt it anytime. Set the delay as you please for responses.
Normal models stay loaded and can be swapped as needed.
Want a video model up? Then Whisper and Drama will make space. Once the video is generated, start voice back up when the video is finished.
The goal is actually fully modular, so consider this a super early version of what it could be. MCP by default, but also ships with a simple UI you can extend as you please.
Thin by design, so everyone can make it their own.
What features do people want next? What about TP=2 or Mac Studio versions?
github.com/jayleaton/localro…
More PR's incoming as I continue testing through the night

Reminder that everyone has outages at the best of times. @Railway is a good product, and what has happened is unfortunate.
Maybe @theo can build a better way to handle secrets/rotations without needing a full deployment.

Railway seems to be coming back online slowly.
This is a reminder that all systems can and will fail, and to build in redundancies in the event of something like this.
I don't personally think swapping to something like Vercel would matter here. They are just as likely to be hit by these kinds of attacks.
The beginning of the end. WTF is happening, everyone is getting hacked or had emergency security issues.
- Node
- PHP x2
- OpenCode
- Railway
- Gitlab
- Lite LLM
It’s going to get much worse I think. Please be careful out there.

🚨 CRITICAL: GitLab flaw (CVSS 10.0) affects 12 years of releases.
CVE-2026-110264 could allow unauthenticated remote code execution on self-managed servers.
Read - thehackernews.com/2026/10/cr…

Clearly, @ThePrimeagen doesn't know about my 2 DGX Spark recipes for DeepSeek Flash on TensorFold.


I wonder if PornHub runs on PHP. Maybe some good will come out of bringing down over half the internet.

‼️ PHP UPDATE: The Dutch parliament, the Dutch national cyber agency and Finland's central government have pulled websites offline ahead of the PHP patch.
Finland's state IT centre Valtori is shutting down public-facing central government web services. The National Land Survey of Finland is already down.
In the Netherlands, the Tweede Kamer, the NCSC and the Dutch Data Protection Authority are offline. So are tech site Tweakers and NotuBiz, which runs council information for 100+ local governments.
The University of Vienna switched off its websites, webmail and Moodle. The University of Freiburg and Finland's Haaga-Helia have taken services down too.
Fur Affinity, Pinboard, explain xkcd and every wiki on Miraheze are dark as well.
Valtori says its shutdown is a precaution, not the result of an attack or breach.
PHP was created by Rasmus Lerdorf in 1994, it initially stood for Personal Home Page
PHP's fix is due at 14:00 UTC today.


Local ai is already doing about 30% of my work.
Once we have local models that perform on the same level as Opus 5.5 then all my work will be using local ai.
The only reasons I would consider paying for subs after that point comes down to 2 reasons.
1. Faster speed. If I can get 200-300 tokens per second at current regular prices then it’s worth it as it’s a multiplayer on output.
2. Complex math/science experiments. As ai solves more math and science problems I might use to experiment on new lossless compression or scaling improvements.
The future of ai improvements are going to be on speed and solving problems humans can’t. Opus 5.5 is already good enough for every task 90% of humans need done.
Welp. Hundreds of km away from my homelab and now one of my machines doesn’t want to boot.
Guess that means Il be working on 1 Spark solutions until I get home. ;)
Very good results for 1 DGX Spark! Incredibly smart and don’t know how @ViC305 did it.
This is the new level to set for 1 Spark.
It would be nice to see tool call improvements as that certainly will effect autonomous work if it gets stuck in a tool call loop often.
Another model I will have to try!

🚨 𝗠𝗬 𝟭.𝟲𝟮 𝗕𝗣𝗪 𝗗𝗘𝗘𝗣𝗦𝗘𝗘𝗞 𝗤𝗨𝗔𝗡𝗧 𝗝𝗨𝗦𝗧 𝗕𝗘𝗔𝗧 𝗧𝗪𝗢 𝗛𝗜𝗚𝗛𝗘𝗥-𝗣𝗥𝗘𝗖𝗜𝗦𝗜𝗢𝗡, 𝗧𝗪𝗢-𝗦𝗣𝗔𝗥𝗞 𝗤𝗨𝗔𝗡𝗧𝗦! 🧪🔥
And I have the REAL benchmark results to prove it! 🤯
Remember my DeepSeek V4.1 Flash 1017 SAGE-EXL3 release from YESTERDAY?
📦 1.62 bpw routed experts
💻 99.61% code answer-token agreement
🖥️ ONE DGX Spark @nvidiaai
Well, I promised to go beyond KL divergence and token agreement and test ACTUAL coding, mathematics, reasoning and tool execution.
𝗧𝗛𝗘 𝗥𝗘𝗦𝗨𝗟𝗧𝗦 𝗔𝗥𝗘 𝗜𝗡!
━━━━━━━━━━━━━━━━━━━━
🏆 𝗗𝗘𝗘𝗣𝗦𝗘𝗘𝗞 𝗩𝟰.𝟭 𝗙𝗟𝗔𝗦𝗛 𝟭𝟬𝟭𝟳 — 𝗡𝗜𝗡𝗘-𝗦𝗨𝗜𝗧𝗘 𝗦𝗛𝗢𝗪𝗗𝗢𝗪𝗡
353 matched benchmark questions.
9 evaluation suites.
Strict pass@1 scoring.
Temperature 0.
🟢 𝗠𝗬 𝗦𝗔𝗚𝗘-𝗘𝗫𝗟𝟯 — 𝟭.𝟲𝟮 𝗕𝗣𝗪
🖥️ 1× DGX Spark
🏆 𝟵𝟰.𝟭% — 𝟯𝟯𝟮/𝟯𝟱𝟯 𝗣𝗔𝗦𝗦𝗘𝗗!
🔵 𝗝𝗝 𝗡𝗘𝗪 — 𝟮.𝟴 𝗕𝗣𝗪
🖥️ 2× DGX Sparks
📊 90.1% — 318/353
🟣 𝗠𝗜𝗔𝗟𝗔𝗕 — 𝟮.𝟵 𝗕𝗣𝗪
🖥️ 2× DGX Sparks
📊 88.4% — 312/353
𝗜'𝗠 𝗨𝗦𝗜𝗡𝗚 𝟰𝟮–𝟰𝟰% 𝗙𝗘𝗪𝗘𝗥 𝗕𝗜𝗧𝗦 𝗣𝗘𝗥 𝗥𝗢𝗨𝗧𝗘𝗗 𝗘𝗫𝗣𝗘𝗥𝗧 𝗣𝗔𝗥𝗔𝗠𝗘𝗧𝗘𝗥...
𝗔𝗡𝗗 𝗦𝗖𝗢𝗥𝗜𝗡𝗚 𝗛𝗜𝗚𝗛𝗘𝗥 𝗢𝗡 𝗢𝗡𝗘 𝗦𝗣𝗔𝗥𝗞! 🤯
━━━━━━━━━━━━━━━━━━━━
💻 𝗧𝗛𝗘 𝗖𝗢𝗗𝗜𝗡𝗚 𝗥𝗘𝗦𝗨𝗟𝗧𝗦 𝗔𝗥𝗘 𝗜𝗡𝗖𝗥𝗘𝗗𝗜𝗕𝗟𝗘!
Scores shown as SAGE / JJ / Mia:
🏆 HumanEval+
39/40 vs 34/40 vs 34/40
🏆 MBPP+
53/60 vs 50/60 vs 49/60
🏆 LiveCodeBench
15/17 vs 14/17 vs 11/17
🧠 𝗥𝗘𝗔𝗦𝗢𝗡𝗜𝗡𝗚 & 𝗠𝗔𝗧𝗛
🏆 MMLU-Pro STEM
95/100 vs 93/100 vs 91/100
🏆 MATH-500
40/40 vs 36/40 vs 36/40
𝗙𝗜𝗩𝗘 𝗢𝗨𝗧𝗥𝗜𝗚𝗛𝗧 𝗪𝗜𝗡𝗦! 🔥
I also tied both models on:
✅ MGSM: 40/40
✅ BFCL: 39/40
✅ SciCode first-step: 6/10
For full transparency, both JJ and Mia won the multi-step tool-chain test, scoring 6/6 against my 5/6.
𝗦𝗢 𝗧𝗛𝗔𝗧'𝗦 𝟱 𝗪𝗜𝗡𝗦, 𝟯 𝗧𝗜𝗘𝗦, 𝗔𝗡𝗗 𝟭 𝗟𝗢𝗦𝗦.
All while using a substantially lower expert bitrate!
━━━━━━━━━━━━━━━━━━━━
🚀 𝗕𝗜𝗚 𝗨𝗣𝗗𝗔𝗧𝗘: 𝗠𝗬 𝗣𝗨𝗕𝗟𝗜𝗖 𝘃𝗟𝗟𝗠 𝗥𝗘𝗖𝗜𝗣𝗘 𝗜𝗦 𝗡𝗢𝗪 𝗣𝗨𝗦𝗛𝗜𝗡𝗚 𝟱𝟮𝟰𝗞 𝗖𝗢𝗡𝗧𝗘𝗫𝗧!
YES. ON ONE DGX SPARK! 🤯
With the latest W2 kernel, updated expert set and KV-cache configuration, I just completed an actual long-context retrieval test!
📚 𝗙𝗨𝗟𝗟-𝗟𝗘𝗡𝗚𝗧𝗛 𝗣𝗥𝗢𝗠𝗣𝗧 𝗧𝗘𝗦𝗧
🧠 518,103 INPUT TOKENS!
🎯 Fact planted HALFWAY through the context
✅ THE MODEL FOUND THE FACT!
⏱️ Time to first token: 470 seconds (~7.8 minutes)
🚀 Prefill: ~1,100 tok/s
⚡ Decode at that context depth: 25.6 tok/s
💾 Minimum available memory: 2.19 GiB
🛡️ Memory safety floor: 0.5 GiB
And on SHORTER prompts?
⚡ ~36 TOK/S DECODE!
🔧 ~130.5 ms per speculative step
🎯 ~4.7 accepted tokens per step
𝗪𝗘'𝗥𝗘 𝗧𝗔𝗟𝗞𝗜𝗡𝗚 𝗔𝗕𝗢𝗨𝗧 𝗢𝗩𝗘𝗥 𝗛𝗔𝗟𝗙 𝗔 𝗠𝗜𝗟𝗟𝗜𝗢𝗡 𝗜𝗡𝗣𝗨𝗧 𝗧𝗢𝗞𝗘𝗡𝗦 𝗣𝗥𝗢𝗖𝗘𝗦𝗦𝗘𝗗 𝗢𝗡 𝗔 𝗦𝗜𝗡𝗚𝗟𝗘 𝗦𝗣𝗔𝗥𝗞! 🔥
To be clear, this was a successful full-length retrieval test, not a claim of perfect accuracy across every possible long-context task.
And the 7.8-minute prefill is a real trade-off at that depth.
But seeing a model this large, with this level of compression, successfully retrieve information buried inside 518K tokens on ONE 128GB machine is an exciting milestone for local AI!
━━━━━━━━━━━━━━━━━━━━
⚡ 𝗔𝗡𝗗 𝗧𝗛𝗘 𝗢𝗡𝗘-𝗦𝗣𝗔𝗥𝗞 𝗣𝗘𝗥𝗙𝗢𝗥𝗠𝗔𝗡𝗖𝗘 𝗞𝗘𝗘𝗣𝗦 𝗜𝗠𝗣𝗥𝗢𝗩𝗜𝗡𝗚!
Separately, my latest REXL3 development measurements at a 256K context configuration:
⚡ 55.35 tok/s single-stream decode
🚀 2,045 tok/s peak prefill
⏱️ 509 ms TTFT on a 512-token prompt
Those REXL3 numbers come from a different engine and workload than the new public vLLM 518K-token test.
And here's something else I'm particularly excited about...
𝗔𝗟𝗟 𝟭𝟱,𝟯𝟲𝟬 𝗥𝗢𝗨𝗧𝗘𝗗 𝗘𝗫𝗣𝗘𝗥𝗧𝗦 + 𝟯𝟴𝟰 𝗗𝗥𝗔𝗙𝗧 𝗘𝗫𝗣𝗘𝗥𝗧𝗦 𝗔𝗥𝗘 𝟭𝟬𝟬% 𝗚𝗣𝗨-𝗥𝗘𝗦𝗜𝗗𝗘𝗡𝗧 𝗜𝗡 𝗠𝗬 𝗧𝗘𝗦𝗧𝗘𝗗 𝗥𝗘𝗫𝗟𝟯 𝗖𝗢𝗡𝗙𝗜𝗚𝗨𝗥𝗔𝗧𝗜𝗢𝗡!
ZERO streamed experts.
𝗢𝗡𝗘. 𝟭𝟮𝟴𝗚𝗕. 𝗗𝗚𝗫. 𝗦𝗣𝗔𝗥𝗞. 💚
@mr_r0b0t and I are continuing to refine REXL3 before its release. More on that soon! 👀
━━━━━━━━━━━━━━━━━━━━
💚 𝗧𝗛𝗜𝗦 𝗜𝗦 𝗪𝗛𝗬 𝗜 𝗕𝗨𝗜𝗟𝗗 𝗙𝗢𝗥 𝗟𝗢𝗖𝗔𝗟 𝗔𝗜.
Just YESTERDAY, I shared my goal of bringing extremely aggressive, high-quality quantization to people who don't have access to massive compute clusters.
With the support of @AWERXAI, I've been working tirelessly to push that vision forward.
And now we're seeing a 1.62 bpw expert quant outperform higher-bitrate alternatives on actual tasks, not just token-level fidelity measurements.
This doesn't establish mathematical losslessness or superiority on every possible workload. These are matched subsets of nine benchmark suites, not full public leaderboard scores.
But it demonstrates something IMPORTANT:
𝗠𝗢𝗥𝗘 𝗕𝗜𝗧𝗦 𝗗𝗢𝗡'𝗧 𝗔𝗨𝗧𝗢𝗠𝗔𝗧𝗜𝗖𝗔𝗟𝗟𝗬 𝗠𝗘𝗔𝗡 𝗕𝗘𝗧𝗧𝗘𝗥 𝗥𝗘𝗦𝗨𝗟𝗧𝗦.
And more hardware doesn't automatically mean you need it!
Huge respect to @jayleaton for his contributions and for giving the community more ways to run these incredible models.
And thank you @AWERXAI for supporting this work. 🙏
🔗 𝗠𝗬 𝗦𝗔𝗚𝗘-𝗘𝗫𝗟𝟯 𝗤𝗨𝗔𝗡𝗧
huggingface.co/vcruz305/DSV4…
🛠️ 𝗢𝗡𝗘-𝗦𝗣𝗔𝗥𝗞 𝘃𝗟𝗟𝗠 𝗥𝗘𝗖𝗜𝗣𝗘
github.com/vcruz305/DSV4.1-F…
𝗙𝗥𝗢𝗡𝗧𝗜𝗘𝗥 𝗠𝗢𝗗𝗘𝗟𝗦. 𝗟𝗢𝗖𝗔𝗟 𝗛𝗔𝗥𝗗𝗪𝗔𝗥𝗘. 𝗥𝗘𝗔𝗟 𝗥𝗘𝗦𝗨𝗟𝗧𝗦.
𝗟𝗘𝗧'𝗦 𝗞𝗘𝗘𝗣 𝗣𝗨𝗦𝗛𝗜𝗡𝗚! 🚀🔥


TP=4 this is your model.

@deepseek_ai -V4.1-Flash-1017 is live on 4× GB10 with TensorFold TP4.
• Our EXL3 4.0 bpw quant of the new 1017 weights: open, MIT
• 136 tok/s code at 1 stream, 183 tok/s at 4 streams
• 2,679 tok/s prefill at 128K
• 1M context, vision, bit-exact drafting
huggingface.co/bertholomus/D…

Crazy that I can sit on a beach in the Phuket islands while my AI computers in my home office can run all my work.
@bot does all my email/calendar and triage for any product outages or help tickets.
DGX Sparks are now self improving the recipe I released last night with my new quant.
My Mac Studio is working on some Mac tensorfold stuff.
My Linux homelab is running all my usual work.
I just use my own fork of T3 for agents and Grokbot app and I have merged over 100 pr’s in the last 36 hours across 5 projects.
