
Research scientist in NLP and interpretability. Ex-Salesforce Research, PARC.
Joined April 2009
- Tweets457
- Following1.8K
- Followers2K
- Likes2.8K


Congratulations @meetdavidwan for this great collaboration between Salesforce Research and UNC! @JotyShafiq @mohitban47

How does positional bias influence faithfulness in long-form summarization (LFSumm)? 🤔
In our latest study, we analyze the effect of positional bias on faithfulness metrics and generated summaries, and methods to mitigate this bias.
📄Paper: arxiv.org/abs/2410.23609
Thead🧵👇

Jesse Vig retweeted

Excited to share this fun new work on the 🩴FlipFlop Effect.
In short: if you ask models if they're sure of their answers, they tend to change their minds (and severely degrade accuracy).
What's mindblowing is how universal the effect is across LLMs (GPTs, Gemini, Claudes, …).

Jesse Vig retweeted

Excited to share a new preprint on the 🩴FlipFlop Effect.
We prompt LLMs with a classification task, and challenge the model by following up with “Are you sure?”. The model can confirm or flip its answer. The results? More flips than a gymnastics competition! 🤸♂️ 1/N

How can we teach models to simplify text using the revision history of Wikipedia articles?
Check out our paper "SWiPE: A Dataset for Document-Level Simplification of Wikipedia Pages" presented by @PhilippeLaban at #acl2023NLP (poster session 5). 🎉

🔗Paper: arxiv.org/abs/2305.19204
🔗Github: github.com/Salesforce/simpli…

1
3
507
Jesse Vig retweeted
🤔Which words in your prompt are most helpful to language models? In our #ACL2023NLP paper, we explore which parts of task instructions are most important for model performance.
🔗 arxiv.org/abs/2306.01150
Code: github.com/fanyin3639/Rethin…

Check out our latest work on text simplification at #acl2023nlp .

Very excited to present SWiPE in person at ACL in a few weeks.
In short, we collaborated with Wikipedia editors to understand the process of document simplification and take a (small) step towards improving document accessibility by releasing a large dataset!
4
792
Jesse Vig retweeted

"SWIPE: A Dataset for Document-Level Simplification of Wikipedia Pages" leveraging the entire revision history when pairing enwiki/simplewiki pages, to identify simplification edits.
(Laban et al, 2023)
arxiv.org/pdf/2305.19204.pdf
@iam_wkr

Jesse Vig retweeted

Check out our work on text simplification! SWiPE accepted at #ACL2023
Finding a document too dense to decipher? 🤔Content a bit convoluted? Essay too esoteric? Check how we simplify and improve document readability using SWiPE. Join us in making knowledge accessible to all! 🌐
🔗Paper: arxiv.org/abs/2305.19204
🔗Github: github.com/salesforce/simpli…
Jesse Vig retweeted
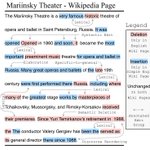
By aligning Wikipedia articles to their simplified versions on Simple Wikipedia, we reconstruct the process by which human editors simplify whole documents, in contrast to prior work focused on sentence-level simplification.

Jesse Vig retweeted
Finding a document too dense to decipher? 🤔Content a bit convoluted? Essay too esoteric? Check how we simplify and improve document readability using SWiPE. Join us in making knowledge accessible to all! 🌐
🔗Paper: arxiv.org/abs/2305.19204
🔗Github: github.com/salesforce/simpli…
Jesse Vig retweeted

Delighted to announce our paper has been accepted for an oral presentation at #ACL2023 oral! In this work we emphasize the intricate complexity of human evaluation while it is becoming even more crucial for both model training and evaluation in the LLM era.

🚨🆕📄🚨
How gold is your human evaluation? We seek the answer, and its implications in the GPT3 era, in our preprint “Revisiting the Gold Standard: Grounding Summarization Evaluation with Robust Human Evaluation”
Paper: arxiv.org/abs/2212.07981
Equal contribution @YixinLiu17

How can NLP help us understand the diversity of news coverage of a topic? Check out the latest work from @PhilippeLaban et al. appearing at #CHI2023 this week.
📰 How can we make it easier for news readers to access nuanced and diverse coverage from multiple sources?
In our #CHI2023 paper, we propose to highlight news coverage diversity through generated *discord questions* shown to the readers.
Link: bit.ly/41yviRP

3
566
Jesse Vig retweeted
Very excited to have the opportunity to present research done at @SFResearch on Automatic Text Summarization at @ZIL_IPIPAN
„Long Story Short: A Talk about Text Summarization” will cover the current state of the field, existing challenges, and future directions.
Jesse Vig retweeted

Human preference != Job Done. Check our interesting findings (ROSE🌹) on summarization!
Thanks to my fantastic collaborators @alexfabbri4 @YixinLiu17 @stefan_fee Yilun Zhao Linyong Nan Ruilin Han @HanSineng @JotyShafiq @CaimingXiong @dragomir_radev!
🚨🆕📄🚨
How gold is your human evaluation? We seek the answer, and its implications in the GPT3 era, in our preprint “Revisiting the Gold Standard: Grounding Summarization Evaluation with Robust Human Evaluation”
Paper: arxiv.org/abs/2212.07981
Equal contribution @YixinLiu17
Jesse Vig retweeted

You can explore the ACU annotations in Rose🌹along with protocol results on our demo page and start using our dataset!
Repo: github.com/Yale-LILY/ROSE
Demo page: yale-lily.github.io/ROSE/
Dataset: huggingface.co/datasets/Sale…
Jesse Vig retweeted
🚨🆕📄🚨
How gold is your human evaluation? We seek the answer, and its implications in the GPT3 era, in our preprint “Revisiting the Gold Standard: Grounding Summarization Evaluation with Robust Human Evaluation”
Paper: arxiv.org/abs/2212.07981
Equal contribution @YixinLiu17
Jesse Vig retweeted

People have been asking for slides of our ACL 2020 tutorial w/ @sebgehr Ellie Pavlick @Brown_NLP on Interpretability and analysis of #nlproc. Thanks to @aclanthology team it’s now here:
aclanthology.org/2020.acl-tu…
Hopefully still useful though much has changed in the field since.

Jesse Vig retweeted

Excited to announce v0.5 of the @GoogleAI Learning Interpretability Tool (🔥LIT), an interactive platform to debug, validate, and understand ML model behavior. v0.5 includes exciting features and a new name! pair-code.github.io/lit/ #NLProc #googlePAIR (1/7)

Jesse Vig retweeted
@davidbau giving keynote 3 on Direct Model Editing and Mechanistic Interpretability


