







MONAI framework is such an amazing gift to the whole medical imaging community and it keeps getting better thanks to many friends at @NVIDIAHealth .
I simply love how powerful and accessible the new gen of open source tooling has become, and it is also super inspiring to see how much of what we do is supported by the strong ITK/VTK foundations laid by @Kitware those many years ago.

Introducing MONAI Physio at #MICCAI2026.
3D and 4D medical images ➡️ personalized cardiac and respiratory digital twins.
This open-source Project MONAI toolkit lets researchers model how the heart beats and lungs move for simulation, visualization, and reproducible research.
Explore the project 👉 nvda.ws/3VLmJFq
1
64
Qwen3.8-27B + RTX 3090 + Pi, are a solid local combo. With smart software optimizations, this card has still plenty of life left in it.
Surprised by how well the token throughput holds up even when capping the GPU to 250W.


🤯 A localmaxxer hit ~381 tok/s on a SINGLE RTX 3090 with Qwen3.8-27B.
This developer has turned a 24GB RTX 3090 into a monster Qwen inference box - w/some creativity.
Four days ago 👉 ⚡ ~82 tok/s single-user
Then 👉
⚡ ~114 tok/s with optimized MTP
⚡ ~138 tok/s with DFlash2 + lookup drafting
Now 👉 🔥 ~381 tok/s on ONE request
How? The recipe combines ...
🧠 Qwen3.8-27B
🎮 1× RTX 3090 24GB @ 250W
⚙️ heavily optimized vLLM
⚡ DFlash2 speculative decoding
🔎 lookup-augmented drafting
📚 prefix caching
🧮 16-token verification blocks
💾 quantized KV / heads / activations
DFlash2 normally proposes 7 tokens.
The developer realized the verification block doesn't have to stop there.
If Qwen is answering from a document already sitting in the prompt, the system can fill the remaining draft positions using tokens found directly in that context.
🎯 So the target model can verify 16 tokens at once.
On a ~25K-token document reproduction task:
Previous DFlash2 👉 ~260 tok/s
Longer verification + context lookup 👉 🔥 ~382 tok/s
Acceptance:
🤯 15 of 16 tokens per verification step
That is where the crazy number comes from.
⚠️ On ordinary real-world chat prompts, the same setup is around ~133 tok/s
Still extremely fast for a dense 27B model on an RTX 3090.
The 381 tok/s mode shines when the answer largely comes from material already in context so these are best use cases
📚 RAG / document Q&A
💻 Coding assistants applying edits
📝 Quoting or rewriting documents
🔎 Extracting information from long prompts
And another optimization 👉 With prefix caching, a second question against the same 25K-token document reportedly goes from:
🐌 22.4 sec TTFT
→
⚡ 0.56 sec TTFT
Because the model doesn't need to process the whole document again.
🎯 It's specifically a mode for RAG front ends and coding agents.
Follow iamMess on Reddit or syv-ai on GitHub
🔗 Reddit: r/LocalLLaMA/comments/1vtup5s/
🔗 GitHub: /syv-ai/qwen38-27b-rtx3090
1
165
An already excellent multi-camera calibration toolbox got even better ⚒️

Excited to announce MC-Calib v1.5.0!
By upgrading to OpenCV 5, reprojection errors are almost halved across all tested scenarios.
Shoutout to @LearnOpenCV for encouraging the upgrade.
🔗 github.org/rameau-fr/MC-Cali…
132
Jan Margeta retweeted

Arithmetic. Vision. Navigation. Planning. What if they're all the same task?
We introduce group composition as a unifying abstraction for many learning problems & show neural networks crack it using Fourier!
Led by @KuninDaniel @giovannimarchet @AdeleMyersPhD @hopfbifurcator🌟


Excited to share that our paper “Sequential Group Composition: A Window into the Mechanics of Deep Learning” was accepted to ICML 2026 in Seoul!
Co-led with @giovannimarchet
and @AdeleMyersPhD @hopfbifurcator @ninamiolane
Paper: arxiv.org/abs/2602.03655

LeRobot never ceases to improve the bot experience 💪
Deployment of policies got easier.
Recording of corrections and retrospective flagging from the ring buffer are two excellent ways to not miss those interesting training examples.
Real-time chunking is pretty sweet too.

🤖🚀 𝗜𝗻𝘁𝗿𝗼𝗱𝘂𝗰𝗶𝗻𝗴 '𝗹𝗲𝗿𝗼𝗯𝗼𝘁-𝗿𝗼𝗹𝗹𝗼𝘂𝘁' — 𝗼𝗻𝗲 𝗖𝗟𝗜 𝘁𝗼 𝗱𝗲𝗽𝗹𝗼𝘆 𝗮𝗻𝘆 𝘁𝗿𝗮𝗶𝗻𝗲𝗱 𝗽𝗼𝗹𝗶𝗰𝘆 𝗼𝗻 𝗮𝗻𝘆 𝗿𝗲𝗮𝗹 𝗿𝗼𝗯𝗼𝘁.
Until today, running a trained policy on a real robot meant repurposing 'lerobot-record' — the same script you used to collect data. Need a different inference engine? That was yet another script. 'lerobot-rollout' replaces all of that with one command: pick a rollout strategy, pick an inference engine, and go.
🔵 Base — Run your policy. See if it works. No recording, no setup friction.
🟢 Sentry — Leave your robot running overnight. Episodes auto-rotate, data streams to the 🤗 Hub in the background. Come back to a ready-made dataset.
🟠 Highlight — A ring buffer silently records the last N seconds. See something interesting? Press a key and that moment is saved retroactively. No more "I wish I was recording."
🟣 DAgger — When the policy fails, pause it, take over with the teleoperator, record the correction, and resume. Every intervention is tagged so you retrain on exactly the moments that matter.
All four strategies work with both synchronous and Real-Time Chunking (RTC) inference, and you can even plug your own! Every combination of strategy × inference engine just works.

1
5
463

Huge thanks to PyCon Austria for the invite and the great conference. Loved talking about robots, simulation, physical AI, and Python in general... some bots can do some serious yoga😃

2
106
Had to get my ACT together!🤖
50 demonstrations and 30 minutes of training is all it takes to get started with imitation learning. @LeRobotHF and the SO-101 arm from @huggingface are a blast to play with, the kit from @seeedstudio is top tier!
Well done AWS, looking forward to trying this! Sounds like some ML pipelines will get simplified. Hope that other blob storage vendors get inspired

Announcing Amazon S3 Files.
The first and only cloud object store with fully-featured, high-performance file system access.
Learn more here. go.aws/4tw17Zg
2
120
Jan Margeta retweeted

you can now run RF-DETR in your react native mobile apps; let’s gooooo!

We just shipped React Native ExecuTorch v0.8.0 – our biggest release yet! 👏🏼
➡️ Vision Camera integration that runs computer vision models directly on your camera feed, in realtime.
Also new: multiple CV models (including RF-DETR (@roboflow) and @liquidai's Vision Language), Bare React Native support, and more.
Takes minutes to try – check out the repo! ⬇️
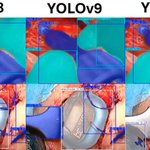
📜Our last pre-RF-DETR-era paper:
Vision-based object detection and tracking from surgical microscope video for augmented cochlear implant surgery
Alvansazyazdi, S., Hussain, R., Margeta, J., Chessa, M., Calixto, R., Kamraoui, R., Hussain, R., Solari, F.
doi.org/10.1080/14670100.202…

105
Our book on Advancing Cochlear Implants is out!
See the magic behind a tech that makes people hear and be heard.
Kudos to the amazing co-authors and editors of our chapter on imaging & AI @PaulaLopezDiez, Behnam Molaee-Ardekani, Thomas Demarcy, Manuel Segovia-Martinez.
Link👇
Covers all from input sound processing to electrical stimulation, and our chapter is on imaging and AI.
link.springer.com/book/10.10…

71
Several years ago, the VIBOT program changed my life. A revolutionary international MSc with courses in vision and robotics, amazing teaching staff, and friends for life. Don't miss this opportunity! Check out the details at vibot.org!

🚀 VIBOT 2026–2027 | Applications opening soon
Read more: linkedin.com/posts/davidfofi…
#AI #ComputerVision #Robotics #Master

Fitsum is awesome, and working with him is too! Apply now, I promise you will enjoy it soooo much!

We’re hiring research interns at @NVIDIA 🚀
You’ll work on core generative models, including autoregressive and diffusion, and help advance NVIDIA Nemotron. Interns are encouraged to publish in top-tier venues like ICLR, ICML, and NeurIPS. Apply or connect with us: forms.gle/8TbXoft7pNWd3Mav9
#GenAI #Nemotron #LLMs #Internships
Wow, this works amazingly well even on my normal laptop! Having performant LLMs will be pretty dope for any offline travels✈️
It's impressive how so much data can be condensed into just 1.5B params (and going down). Those weights should be put onto future Golden records #voyager

it's crazy what a 1.5B model can do these days!
"VibeThinker-1.5B is a 1.5-billion parameter dense language model. With a total training cost of only $7,800 USD, it achieves reasoning performance comparable to larger models like GPT OSS-20B Medium."
runs perfectly on device!
2
2
485
supervision and inference from Roboflow are super vision libraries with very well designed composable APIs and under MIT license.
Perfect as the first stop especially for any object detection and tracking. You only live once, so pick the tools wisely. The new release is 💥


NextBrain solves histology jigsaw puzzles guided by MRI, to create ultra fine, densely labelled probabilistic brain atlas with 333 regions. Amazing research, publications, data and code by @JuanEugenioIgl1 et al

Ten years (!) after submitting the grant, NextBrain is published in @Nature . NextBrain is a brain atlas built from 3D histology that enables segmentation of 3D brain scans (MRI, Hip-CT, even photos!) into hundreds of regions.
Article, data, code, videos, & more in this 🧵 (1/3)

1
4
357
The Grid, a digital frontier.
I tried to picture clusters of information as they moved through the computer
What did they look like? Ships? Motorcycles?
...
I kept dreaming of a world I thought I'd never see.
And then, one day,
I got into Neural operators 🏍️
#TronLegacy

🚀 NeuralOperator v2.0.0 is here! 🎊
Train at 64×64, fine-tune at 128×128, run inference at 512×512. No retraining.
That's the power of learning in function spaces 🔥
🎪 At the @PyTorch conference today? Find us at the poster session, we’d love to discuss operator learning, and don’t miss @AnimaAnandkumar’s keynote on foundations for AI+Science!
✨ What's new:
•New models: CodaNO, Mollified GNO, Fourier Continuation
•Tensor-GaLore for memory-efficient training
•The Well dataset integration
•Physics-informed training: H-div loss, PINO reweighting, Fourier differentiation
•Improved docs with tutorials, theory, user & dev guides
•Major refactoring & 100+ bug fixes
📖 Docs: neuraloperator.github.io
⚡ Install: pip install neuraloperator
📦 Release: github.com/neuraloperator/ne…
Big thanks to our 16 contributors! 🙏
#MachineLearning #ScientificML #PyTorch #NeuralOperators
1
2
103