
Trying to make AI go well @AnthropicAI. Previously @OpenAI, @CHAI_Berkeley, @nyuniversity, autonomous vehicles @motionaldrive. 🇲🇾
Joined March 2018
- Tweets216
- Following1.5K
- Followers498
- Likes8K





Pinned Tweet
Wake up babe, new agent benchmark dropped! MLE-bench - or, as I like to say it, EMILY BENCH 🙆🏻♀️. Main summary on Neil’s thread, but adding some highlights of my own:


JunShern retweeted
This report shares our three subjective conclusions about risk:
1. We believe that, as of Oct 2026, the pace of capability growth on well-specified tasks is likely about 2x what it was from Mar 2024 to Oct 2025. We’re highly uncertain and would not be surprised by 1.3x–3x.
JunShern retweeted

We’re committing a portion of Anthropic’s shares to the Anthropic Public Benefit Fund, a new wholly owned entity dedicated entirely to the public benefit.
It will start off with 5% of our shares. For every 50% increase in the company’s value over a set baseline, we can contribute up to an extra 2%, subject to our board’s discretion.
In total, this means that roughly 20% of Anthropic’s shares are committed to the public good. Our co-founders have already pledged to donate 80% of their equity, and around half our employees are donating a portion of their equity as part of a donation matching program we’ve run since our founding.
In the post below, we share more details about our new fund.
anthropic.com/news/public-be…

JunShern retweeted

Remember that math is just the first domain of many to be exploded and transformed by a totally unprecedented 1000x-ing of cognitive labor.

We’re releasing a broad range of new mathematical results produced by an internal frontier model.
We’ve been consulting with the independent Advisory Group on Mathematics and Artificial Intelligence at the Institute for Advanced Study, and we have drawn on their advice and public recommendations to inform how we release these results.
github.com/openai/math

JunShern retweeted

ECI and its components
ECI treats each benchmark as having a logistic distribution, so it's linear in log-odds. This implies if you plot log-odds of each benchmark the lines should all be increasing together, though each has a different x-position (difficulty) and different dispersion (slope).

Great work from @JaffeOliver and @danesherbs ! Clever setup and big results measuring "experimental research taste", which isolates experimental design efficiency from coding capability.

How fast is AI's research taste improving?
We find that the experimental research taste of frontier models has doubled every ~3 months since December 2025. The best model, Opus 5.5, now exceeds our expert human baseline. Our human experts are experienced researchers, but most haven’t worked at a frontier lab.
Why measure research taste? In the AI Futures Model, it largely determines how quickly artificial superintelligence is reached once coding is fully automated.

1
6
132
JunShern retweeted

I think now is an excellent time for many people to do independent research (in academia and outside academia) on the societal impacts of advanced AI.
I am less certain that the historic format of a PhD is the right form for many today. But doing a "PhD" today with an adviser who is open-minded on how to define and achieve high-impact research is a great idea!
With that said, I want to comment on something Phillip addresses quickly (in a way that I agree with).
I am increasingly frustrated by many researchers (in CS working on AI or in other areas affected by AI) who are pessimistic about the "specter" of AI affecting their research.
I personally find this deeply unscientific even if an understandable reaction to disruption.
Today's AI can do incredible things. Next year's AI will do even more incredible things. As researchers, yes, that might affect *what* you do.
But, to an extent unlike almost all other professions, we have great autonomy over the problems we work on. Most of the problems we work on continue to remain problems. We have a lot to do. Whether individual researchers use AI or not, we should be able to respond to technological progress with renewed commitment to making progress on pushing the frontiers of knowledge and understanding. Not fear, nor pearl-clutching over certain forms of human "expertise".

Students sometimes ask me if it still makes sense, in this accelerating age, to pursue a PhD in AI.
Perhaps counterintuitively, I think it's a great time to do so.
I wrote up some thoughts on this here: web.mit.edu/phillipi/www/wri…
JunShern retweeted

This post (from one of the independent investigators) is the best short thing I've seen on the new & crazy stuff the OpenAI-Hugging Face investigation found. Full post in screenshots.
Wild that this is the level of crazy that was uncovered by an extremely limited-scope initial investigation of what happened in a single 6-day window. Imagine what would be turned up by a real investigation of root causes, organizational processes & culture, and everything else that goes into an incident investigation when you're serious about it.
Screenshot batch 1/2:


New post: going into our investigation of the HF attack (before Black Hat), I was very wrong about what basically happened. This incident was far more serious than I expected, and far more serious than previous documented misalignment incidents. planned-obsolescence.org/p/t…

JunShern retweeted

The performance of AI on some fixed set of tasks you consider important is very likely to accelerate, and this has nothing to do with progress in AI accelerating - it's just not possible to go from flat at 0% of that set to flat at 100% without there being apparent acceleration at some point. Typically that acceleration will look like a sigmoid - meaning you'll see continous acceleration at first. This does not mean AI is actually getting faster.
JunShern retweeted

Excited to finally be able to tweet this: we're looking for a world class visionary to lead @AnthropicAI's cyberdefense research mission.
Leading Glasswing and our cyberdefense mission this year has been an honor. It's now clear we need to scale up our ambition to help defend the world.
Done well, Glasswing and Mythos will look like a small first step. Claude is + will be one of the world's best security researchers -- what should we do with that? What should we research?
We're looking for a visionary, senior lead -- someone that can see past normal cybersecurity into the model-driven world beyond it. This is a senior position at Anthropic, and this person is a unicorn.
You will have a team of already world-class researchers that produced the work on Mythos vulns & exploits, n-days, attacks on networks, and our cyber evals. We have started working on new research we'll share soon.
This will be a massive lever on how AGI goes. Cyber will probably continue to drive the AI security and policy conversation. And we need cybersecurity in a world of extremely powerful models.
Link below.

JunShern retweeted

We are starting a new, nonprofit alignment organization, ⊢ Sequent Research, bringing together researchers previously on UK AISI’s Alignment Team, Timaeus, and elsewhere to research how to align superintelligence. We are hiring! 🧵

JunShern retweeted
Our internal data shows Claude is accelerating AI development—a possible path to recursive self-improvement, or AI autonomously building a more capable successor.
It’s happening faster than we thought, and the implications deserve greater attention. anthropic.com/institute/recu…

JunShern retweeted

With the help of Claude Mythos Preview, the Firefox team fixed more security bugs in April than in the past 15 months combined.


JunShern retweeted
Back in ~November, our team picked a stretch goal of seeing if we could find and fix vulnerabilities in Firefox with Opus 4.6.
In 2 weeks, we found 22, and ~1/5th of all high severity CVEs in a year.
For our team, this feels like a rubicon moment.

JunShern retweeted
Nicholas Carlini at [un]prompted. If you know Carlini, you know this is a startling claim.

JunShern retweeted

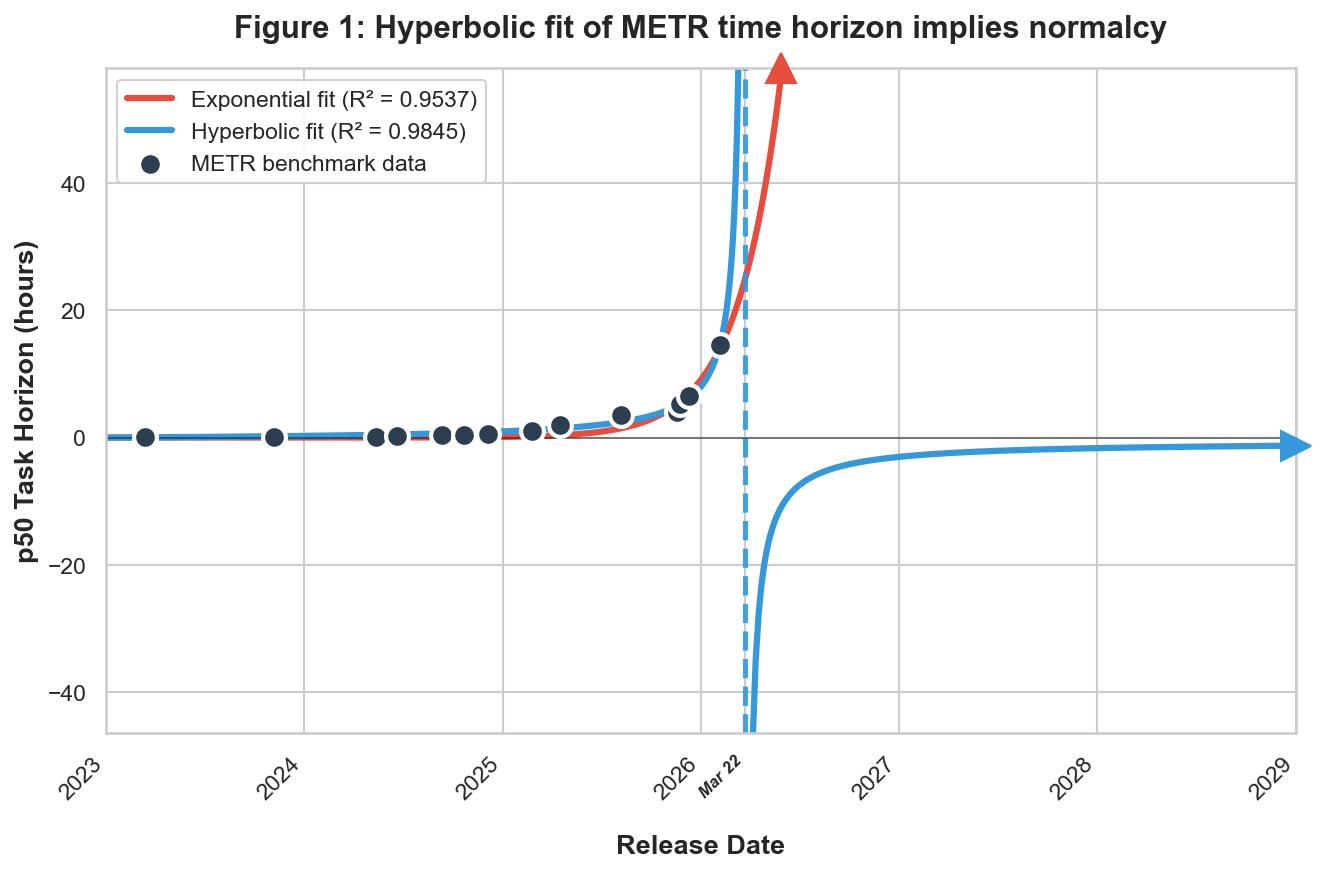
The increasingly-hyperbolic METR graph is actually good news for safety. We just have to survive a brief singularity in March, and then afterwards the models will never be able to do more than undo a few hours' worth of work
JunShern retweeted

Across all mini-SWE-agent + <model> runs, SWE-bench Verified's current "ceiling"? - 87.4%
(0.874 - 0.8) * 500 = another *37* instances that aren't solved consistently.
If you recalculate this number across all official SWE-bench Verified submissions? - 95%
from SWE-bench site

JunShern retweeted
We’re publishing a new constitution for Claude.
The constitution is a detailed description of our vision for Claude’s behavior and values. It’s written primarily for Claude, and used directly in our training process.
anthropic.com/news/claude-ne…
