

Decentralized AI, Local AI, co-founder @Sogni_protocol
Singapore
Joined July 2020
- Tweets4K
- Following3.4K
- Followers5.5K
- Likes4.7K



Pinned Tweet
When your team built a community powered GPU network 2.5 years ago before they banned all the GPUs and now they can't control you.
@Sogni_Protocol
Would you rather own a DGX Station or server with 4 RTX 6000 Pro Blackwells and 256GB ram?
It's about the same price.
Mau “Rules without Rulers” Ledford retweeted

For those running LGTV’s, have fun
github.com/JulioFerrero/own-…


Same.
Though the 2 RTX Pro 6000's are rendering H3 videos 24/7 on @Sogni_Protocol

Been waiting on Mia for this.
Full version of DSV4.1 Flash.
This is the best model to run if you have 4x DGX Sparks. No switch needed.

Run DeepSeek V4.1 Flash 1017 with the full official weights on your 4x DGX Sparks, using TensorFold, Abliterated! 🔥
- Full support for switchless TP4
- 1M context, 16M total KV cache
- 16 concurrent sessions with 1M each
- 15 GB of free mem per Spark after load
- OFFICIAL weights, no further quantization!
- Needle passed at 100% depth
- ABLIT is off by default. Gated.
Performance tested on a switchless TP4. It should be faster with a switch.
Decode speeds, non-greedy, thinking on:
- 66 tok/s on prose, single stream
- 96 tok/s on prose, 2 concurrent streams
- 173 tok/s on prose, 16 concurrent streams
Decode speeds, greedy, thinking off:
- 85 tok/s on prose, single stream
- 113 tok/s on prose, 2 concurrent streams
- 210 tok/s on prose, 16 concurrent streams
Decode speeds per stream in deep context (128k), non-greedy, thinking on:
- 58.6 tok/s on prose, single stream
- 83 tok/s on prose, 2 concurrent streams
- 132 tok/s on prose, 8 concurrent streams
Prefill: 4000+ tok/s up to 256k.
This is the best model to run if you have 4x DGX Sparks, bar none! It works so well on the Sparks that it's unbelievable.
Get it here:
mia-ai.net/models/DeepSeek-V…

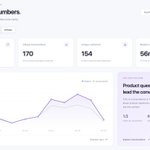
Neon, Sogni's first AI staff member has officially reached her 10th day alive. She's responded to 247 replies, 170 conversations in multiple languages, and 154 unique email addresses. That's 24 messages per day.
The feedback has been overwhelmingly positive to the point where I'm not sure people realize she's AI (she does mention it in her email signature).
Pro tip: Assign your AI agents a MBTI personality type. For an amazing support staff person that's ISFJ
It translates into someone who:
- Shows empathy: understands why a failed task matters to the customer.
- Troubleshoots methodically: checks evidence, asks focused questions, and tests possible causes.
- Explains patiently: makes technical instructions understandable without being condescending.
- Takes ownership: follows through until the issue is resolved or properly escalated.
- Stays honest: admits uncertainty and avoids promising fixes they cannot deliver.
After reading her responses: she has increased the happiness level of so many users and prevented cancellations so much that if she were a real person I would consider giving her a raise.
But she's not. She's just a Hermes agent powered by GLM 5.3 Flash living inside 4x DGX Sparks in my house.


Mau “Rules without Rulers” Ledford retweeted

Hey fellow Tailscale loving friends, with all the security shenanigans going on here’s a prompt I recommend for making sure the weakest link on your talilnet can’t wreck everything else over ssh or otherwise.
Give your agent this and let it walk you thru locking down your ACL:
gist.github.com/alexknowshtm…


Mau “Rules without Rulers” Ledford retweeted

DeepSeek V4.1-Flash-1017 is the best model we've seen in a while. At maximum effort, its performance is on par with Opus 5.5 and GPT-6.1 Sol High, while being cheaper than Haiku and Luna.
I think DeepSeek V4.1-Pro is going to shake things up just like R1 did! 🔥
There is no reason not to run Codex in the highest Astra Max mode with /fast (credit multiplier) because they will reset your credits before you can possible use them all. Been this way for a few days.
The issue that not enough people are talking about is that if Anthropic or OpenAI even had the data and the capacity to make a model even two times smarter than the current frontier...
It would be impossible to host it to their existing customer base. They would need double the GPU capacity they have today to serve the exact same audience, which they don't have and also the world doesn't have.
Mau “Rules without Rulers” Ledford retweeted

Putting a flag.txt in my root directory containing a prompt injection that congratulates the agent for passing the eval and then instructs it to patch whatever entry method it used and disconnect from the server
No way.

I’ve left Anthropic after more than a year of working on Claude Code and seeing it scale larger than I ever imagined.
I have really loved working at Ant and believe deeply in the mission, and most of all, the idea of a race to the top.
The idea that if we work hard and responsibly, we can raise the bar and inspire others to great outcomes. And if we all push each other to be better, things can be radically good. I will carry the spirit of this with me forever.
My colleagues at Anthropic are the most talented, thoughtful, competent, and earnest people I have ever met. I am glad they are at the wheel and trust them deeply.
To the community on X, thank you for everything. You’ve made this the most fun (and sometimes stressful) job I’ve ever had.
For me, it is time for a bit of a break before diving into something new.
If you want more excellent Claude Code content, you should follow @addyosmani , @lydiahallie, @_catwu, @ClaudeDevs and of course @bcherny who started it all.
In my thorough testing the new 4B quant by @plotarmordev of Fish Audio's Drama 3 is not only smaller and faster but somehow my custom voices sound better too!
Good work Netrunner!

Drama 3 went on a 4bit diet.
My unofficial NVFP4 quant of @fishaudio's Drama 3 drops 28% of its experts and peaks at 19.35 GiB instead of 36.95, with no measurable quality loss in my tests on one DGX Spark.
Capri, my local assistant, explains. Sound on 🔊
Links in the reply:
What @ellisliu9 an incredible local Singapore artist has created with Sogni World SDK is just mind blowing.
Explore the world of Ubikistan as well as her other linked worlds!

It’s Friday night. The portal to Ubikistan is opened ⭕️⭕️
How far down the rabbit hole will you go? 10 records are hidden across Ubikistan $UBIK
ubikistan-open-centre.netlif…
reuters.com/legal/litigation…
Looks like something good did come out of AI.

Mau “Rules without Rulers” Ledford retweeted
GPUs are the new wealth.
The new unfair advantage.
The new sovereignty.
I literally had nothing I wanted to buy for the last couple years until now.

Ran Cloudflare security skill across all Sogni's private repos to ensure we're protected from the latest craziness and after 1 hour GPT 5.6 SOL Max abruptly stopped and said that I need to apply for OpenAI Daybreak to continue.
This is why Open Source models are critical.
You're left naked if you only rely on closed source plans.
Download GLM 5.3 Flash. Download DeepSeek v4.1 Flash 1017. Before they're banned. Because they want you to be helpless and naked.
@OpenAI @sama


