
Research Scientist @cognizantailab PhD @jkulinz, Institute for Machine Learning
Joined November 2010
- Tweets287
- Following284
- Followers435
- Likes639




Kajetan Schweighofer retweeted

New paper 🧵 KronLSTM: a new member of the xLSTM family, built on the Kronecker Delta Rule.
✏️ less interference than delta-rule updates
📏 provably bounded memory, no normalizer state
📈 competitive with, often ahead of, (Gated) DeltaNet, especially at long context
Kajetan Schweighofer retweeted
Sorry for delay! Here is my work on zero order (ZO) optimization.
We achieve SOTA for ZO methods on pretraining controlling for compute and parameters.
ZO methods struggle to improve loss
as model size grows because relative gradient variance increases linearly with the number of perturbed parameters, inhibiting large model training.
All previous methods innovate on the optimizer, but adopt architectures designed for backprop.
Instead, we design an architecture with ZO in mind, that caps the gradient variance as you increase model size.
Introducing SOMA (Sharded Optimization Mixture of Assemblies). SOMA shards the model into tiny experts, and trains each expert independently, on disaggregated GPUs, without communicating gradients, activations or optimizer state during training.
Inspired by the thalamus and cortical columns, each expert specializes on a subset of the train set based on a fixed router.
At isocompute and isoparams, SOMA achieves lower loss vs. all monolithic ZO methods tested (e.g. EGGROLL, more perturbations w Vanilla SPSA, etc).
ZO w SOMA continues to improve at larger model sizes.
Additional inference benefits of this architecture, we can select top-k active experts over N trained experts to reduce inference compute by O(N/k), allowing us to tradeoff inference flops for accuracy wo retraining.

Kajetan Schweighofer retweeted

We let an agent self-improve by exploring and internalizing ”on this sort of task, keep this sort of thing in mind“ bits of self-feedback. It learned to solve tasks where the original policy failed 128 attempts in a row and GRPO flatlined.
Paper: arxiv.org/abs/2609.37633
🧵1/8
Kajetan Schweighofer retweeted

Why don't you set up the ICML deadline one week *before* the ICLR notification date? If NeurIPS, ICML, and ICLR go out of sync, every researcher has to decide: is it worth submitting my paper now and missing the next deadline, or should I submit a better version in four months?
76% on ARC-AGI 1 training from scratch + inference in a bit more than 4h on a single H100.
Throughput-optimized recipe attains 44% (TRM-level performance) in 17min.
Just a simple autoregressive transformer with a few twists. 🧵
The strong but not saturated performance + low runtime allow to quickly test new ideas on abstract reasoning.
Solving ARC-AGI 1 building upon this approach should be within reach: Ensembling over multiple models can generate correct solutions to 91% of the tasks (top-2 score 80%).
Thanks to my colleagues at
@cognizantailab
, for creating such a vibrant research environment. Many more exciting results to come soon. Code and writeup with ablations: Code: github.com/kschweig/transduc…
Writeup: github.com/kschweig/transduc…

Kajetan Schweighofer retweeted

Post-training with RL increases pass@1 accuracy and reduces solution coverage. When scaling test-time compute, maintaining solution coverage is essential! Can a method improve accuracy while maintaining coverage? Yes, Evolution Strategies can! We show this in our new paper!
Kajetan Schweighofer retweeted

TerraLingua is live! And now open to the public! 🌍🤖
Create an autonomous AI agent, introduce it into a persistent world, and see what happens:
cognizant.com/us/en/ai-lab/t…
A thread 🧵
Kajetan Schweighofer retweeted
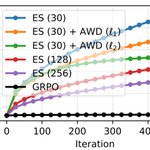
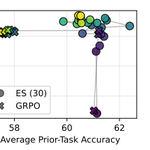
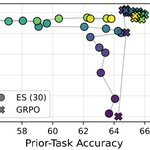
Forgetting in post-training can be mitigated by using evolution strategies with anchored weight decay!
ES+AWD operates in weight space and applies regularization directly to the model parameters.
We are only scratching the surface of what ES methods are capable of. 🚀🚀🚀

New preprint: Overcoming Forgetting in LLM Fine-Tuning with Evolution Strategies
ES recently emerged as a strong alternative to RL methods for LLM post-training. However, it was shown to suffer from prior task forgetting. We took a closer look and challenge this narrative🧵

Overall, these findings position ES well as method of choice for continual learning in LLMs.
Grateful for my amazing collaborators at @cognizantailab :
@conorfhayes @RobertoDailey1 @RistoMiikkulai1 @realVsonicV
📄 arxiv.org/abs/2605.30148

Our latest Blogpost on this line of research: cognizant.com/us/en/ai-lab/b…

Kajetan Schweighofer retweeted

We did a deep investigation on prior-task forgetting during LLM fine-tuning with Evolution Strategies (ES). Two main takeaways:
1. Forgetting is not a big hurdle for ES: it only happens at moderate level in specific settings.
2. In cases of forgetting, we have a simple yet effective solution.
Check out the full paper here: arxiv.org/abs/2605.30148