

The Robotic Systems Lab designs machines, creates actuation principles, and builds up control technologies for autonomous operation in challenging environments.
Zurich, Switzerland
Joined March 2016
- Tweets714
- Following171
- Followers39K
- Likes588






This work is led by Mohamad Danesh @mo_danesh, together with Chenhao Li @breadli428, Amin Abyaneh, Anas Houssaini, Kirsty Ellis, Glen Berseth @GlenBerseth, Marco Hutter, and Hsiu-Chin Lin.
@mcgillu
@Mila_Quebec
@UMontreal
@ETH_en
@ETH_AI_Center
@leggedrobotics
In our latest work at @corl_conf, we introduce Quadrupedal World Model: a single morphology-conditioned dynamics model, where policies are trained entirely in imagination.
We found generalization emerges by conditioning the dynamics, not the policy.
🔗modanesh.github.io/papers/qw…

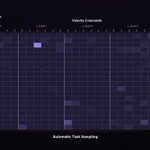
LP-ACRL removes the need to predefine task difficulty. It measures task-wise learning progress from episodic-reward changes, then uses a softmax to shift sampling toward the current learning frontier, where tasks show stronger positive competence gains at that stage.

After teacher–student distillation, a single policy transfers to ANYmal D and achieves:
• 3.0 m/s on flat terrain
• 2.5 m/s on challenging terrain
• Up to 3.0 rad/s angular velocity across all tested terrains
Scaling Rough Terrain Locomotion With Automatic Curriculum Reinforcement Learning
Authors: Ziming Li @ZimingLi97, Chenhao Li @breadli428, Marco Hutter
Published in: IEEE Robotics and Automation Letters ( Volume: 11, Issue: 8, August 2026)
ieeexplore.ieee.org/document…
We achieved high-speed rough-terrain locomotion on ANYmal with an automatic curriculum.
LP-ACRL automatically samples terrain types, levels, and velocity commands at the correct time based on policy performance, without predefining an order.
🔗sites.google.com/view/lp-acr…
🧵RAL 2026

VLMs don't understand a robot's body. How can a robot learn from its failures without retraining?
PragmaBot: online in-context learning from real-world experience. The robot reflects on failures, stores lessons in memory, and retrieves them for new tasks.
RA-L · #IROS2026
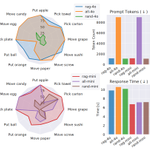
How much memory belongs in the context? 5 random memories: 17% first-action accuracy on unseen tasks. Entire memory in the prompt: 74%, at 7.5x the tokens. Top-k relevant via RAG: 89%. Relevant context beats more context. As memory grows, what should a robot forget?

Congrats to Kaixian Qu, Guowei Lan, René Zurbrügg, Changan Chen, Christopher Mower, Haitham Bou-Ammar & Marco Hutter. Say hi at IROS 2026!
ieeexplore.ieee.org/document…
arxiv.org/abs/2507.16713
pragmabot.github.io
github.com/leggedrobotics/pr…
We are releasing EgoHTR, a dataset with both human motions and terrain references, accepted @corl_conf.
📖 Paper: lnkd.in/eeepUefs
🌐 Project Page: egohtr.github.io
• 55 scene-aligned sequences • 150k+ frames • rough-terrain environments • multi-modal 3D scene
We’re open-sourcing the dataset and the full data pipeline to make this resource accessible to the community and hopefully enable new directions in learning-based robotics.
By Alex Brandes, Haig Conti Georges Sajelian, Manthan Patel @patelm99, Dominik Hollidt, Chenhao Li @breadli428, Matthias Heyrman, Oliver Hausdörfer, Manuel Kaufmann, Xi Wang, Jonas Frey, Angela Schoellig @angelaschoellig, Christian Holz, Marc Pollefeys @mapo1, and Marco Hutter.
PPO has long dominated robot locomotion training in simulation. SAC, despite its sample efficiency, couldn't keep up.
We analyze why:
🔗sabagian.github.io/sac_relea…
🔥Integrated into RSL-RL, our approach requires only minimal changes, making SAC a drop-in alternative out of the box.
This project focuses on understanding the performance gap between PPO and SAC in massively parallel robot learning.
While efforts like FlashSAC @hojoon_ai and FastSAC @younggyoseo explore separate development, RSL-RL-SAC is made to stay close to the widely used RSL-RL codebase.

This project is led by Gianluca Sabatini, supported by Chenhao Li @breadli428 and Marco Hutter @leggedrobotics. We thank Clemens Schwarke's implementation insights.
Check out the paper!
arxiv.org/abs/2605.24975
