

@printfresh co-founder. Living in and making Philly better.
Philly
Joined April 2008
- Tweets1.5K
- Following2K
- Followers470
- Likes1.9K
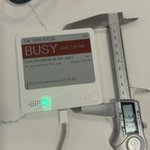






Don't sleep on Argon. Built a Telegram desktop fork with 50% of an Ultra plan's weekly usage. I hated how I couldn't filter/search Telegram topics with my Hermes agent, so I forked and added a quick filter for topics that is semantically accurate as a bonus, and built in a Telegram MCP for my Hermes agent to access all my Telegram stuff (Hermes is the only thing that I use Telegram for) so it can much more easily and quickly inspect conversations inside of Telegram. Currently building the same for iOS and still well within my weekly limit. I know that I can do the same with Opus, but @GoogleAI Argon is at parity for me and nice to have options.

You can just make things these days.
Leg on my couch busted. Took out a caliper, measured it, snapped some photos, and sent them to my Hermes. Asked it to rebuild it. No problem.
Added a tpu foot. Printed it at a 45-degree angle for strength. Perfect match. Showing you the scraggly side where the fins were holding it up.
The point is, with any agent, you basically have a replicator. You just have to be able to articulate what you want.
Printed on a @BambuLab H2D


Unbelievable ♥️

Through the VOICE trial, Terry is using his Neuralink implant to help fine-tune a brain-to-voice interface for himself and others who can’t speak. He trained the algorithm first by miming speech as best he could, then by simply thinking the words and hearing them come out in his own natural voice.
Powered by Grok Voice from @spacexai
Muse may be the single best consumer ai implementation there is right now. Long Meta. It’s not bad for business either.
My personal sense is that instinct doesn’t have enough to lose and may play faster and looser than I am personally comfortable with. I would feel better if it was acquired by Google.
Just like every one has already done with instinct i got Muse to save me $1500 on car insurance with minimal guidance.
It has also created some reasonable implementations of hardware concepts (but I did have it install herdr , OMP and gave it Deepseek v4 api key and taught it to orchestrate that). 3d, design,
Practical computer use in muse is through the roof way better and quicker than my Hermes/openclaw. Even with all the optimizations I’ve put on top of both implementations (cua etc).
For example today I wanted to setup ADP to track pto instead of the spreadsheet my company uses. Turned out I needed to setup my adp account - it asked me the questions asked me for 2fa and took care of it. Navigated the full setup created a google doc sop, imported and setup everyone’s pto over, then created a well done voice narrated walk-through for employees and managers. I could do all this in Hermes and OpenClaw for sure but this was wayyyyy smoother and faster. The muse model is conversationally good and is a little warmer than Astra and less pedantic/didactic than fable/opus.
I think it may be better than grok bot. I still haven’t figured out how to make multi-session work in there on the mobile app.
Don’t sleep on muse is my recommendation - you can push it pretty far - give it your hardest problems it will surprise you.


leovoloshin retweeted

Sneak peek at one of the coolest projects we’ve worked on over the last year: @chadludeman and I designed a floating resort, in the form of a row of semi-permanent houseboats at a NJ marina… pro photos coming this fall!

leovoloshin retweeted

“Dangerous Chinese models thwart an active cyber crime from a frontier closed source US lab.”


This is the only argument for a subscription model for frontier models. If the token prices go down by 95% then OpenAI/anthropic/etc become dramatically profitable and justify the crazy infra buildout. Questions of data sovereignty not withstanding. For our company we are approaching it from a both locally trained model perspective for handling our customers data and our proprietary design stuff while using frontier models to execute the build out. This hybrid approach is most likely the future. Companies will wall off access to their internal data while utilizing frontier models to build the internal infrastructure quickly. The real question to me is once most of the infrastructure is built in a company and for most companies it’s finite - there’s not going to be a hell of a lot for the frontier models to do if the locally hosted ones can do a big part of the day to day work on internal company data.
Anecdotally I’m finding Sol/fable advisor to be very good at rebuilding any piece of software that we are paying for. Currently building our version of granola/read hybrid. Think we can build it in about a week or two with just one or two codex resets and one fable max plan (I guess that runs out tomorrow). Interesting times.
I Really wonder if anthropic will be forced to keep fable in the max plan because of the quality of Sol. They’ve done a massive amount of aura damage with the rollout as they have done it. In our 40 person company I just rolled out Claude to everyone over the last month and am now regretting not picking OpenAI. I feel like anthropic needs to do damage control quickly or it will have a very high churn a year from now.

When tokens go down 90% by the end of the year and then another 90% next year, everyone's opinions on artificial general intelligence and superintelligence are going to change radically
I'm currently on an unlimited GLM 5.2 bittensor subnet and I can tell you your behavior changes radically when token prices plummet
An inspiration few days in Los Angeles. Thanks to these guys for putting this on. @friedberg


Does anyone know when @GeminiApp for workspaces will have memory? My personal @gmail account's Gemini already does but the workspace at our company does not...

leovoloshin retweeted
1) DeepSeek r1 is real with important nuances. Most important is the fact that r1 is so much cheaper and more efficient to inference than o1, not from the $6m training figure. r1 costs 93% less to *use* than o1 per each API, can be run locally on a high end work station and does not seem to have hit any rate limits which is wild. Simple math is that every 1b active parameters requires 1 gb of RAM in FP8, so r1 requires 37 gb of RAM. Batching massively lowers costs and more compute increases tokens/second so still advantages to inference in the cloud. Would also note that there are true geopolitical dynamics at play here and I don’t think it is a coincidence that this came out right after “Stargate.” RIP, $500 billion - we hardly even knew you.
Real: 1) It is/was the #1 download in the relevant App Store category. Obviously ahead of ChatGPT; something neither Gemini nor Claude was able to accomplish. 2) It is comparable to o1 from a quality perspective although lags o3. 3) There were real algorithmic breakthroughs that led to it being dramatically more efficient both to train and inference. Training in FP8, MLA and multi-token prediction are significant. 4) It is easy to verify that the r1 training run only cost $6m. While this is literally true, it is also *deeply* misleading. 5) Even their hardware architecture is novel and I will note that they use PCI-Express for scale up.
Nuance: 1) The $6m does not include “costs associated with prior research and ablation experiments on architectures, algorithms and data” per the technical paper. “Other than that Mrs. Lincoln, how was the play?” This means that it is possible to train an r1 quality model with a $6m run *if* a lab has already spent hundreds of millions of dollars on prior research and has access to much larger clusters. Deepseek obviously has way more than 2048 H800s; one of their earlier papers referenced a cluster of 10k A100s. An equivalently smart team can’t just spin up a 2000 GPU cluster and train r1 from scratch with $6m. Roughly 20% of Nvidia’s revenue goes through Singapore. 20% of Nvidia’s GPUs are probably not in Singapore despite their best efforts. 2) There was a lot of distillation - i.e. it is unlikely they could have trained this without unhindered access to GPT-4o and o1. As @altcap pointed out to me yesterday, kinda funny to restrict access to leading edge GPUs and not do anything about China’s ability to distill leading edge American models - obviously defeats the purpose of the export restrictions. Why buy the cow when you can get the milk for free?
People’s inability to write a cover letter is astounding. I hope they realize that using ChatGPT to write one is easily spotted and an instant disqualification. That people would use this while applying for a $150k+ position is honestly shocking.
Every single one has a third paragraph that starts with:
What excites me most about Printfresh is…