

Research at NVIDIA | Led OmniVinci, MM-Ego, X-VILA | Contributed Nemotron-Omni
Santa Clara
Joined October 2012
- Tweets441
- Following2K
- Followers1.2K
- Likes1.6K



Pinned Tweet
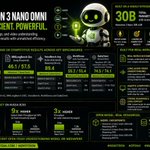
@NVIDIA introduces Nemotron 3 Nano Omni LLMs.
A year ago, we started research on omni-modal LLMs—covering everything from architecture to data—and released OmniVinci (ICLR 2026). We’ve received some feedback since then, but two clear themes emerged: 9B parameters weren't quite enough for many applications, and restrictive licensing was holding back commercial use.
Therefore, we’ve teamed up with a larger group of amazing NVIDIA researchers/engineers to introduce NVIDIA's first commercial omni-LLM Nemotron 3 Nano Omni. This new 30B-A3B model is fully open-source and commercially usable. It also consistently outperforms similar-sized models across image, video, audio, and omni benchmarks.
My primary focus on this project was Omni-RL infra development and model training, besides architecture/hyper-parameter exploration and verification. Here are a few key takeaways from the process:
• Cross-modal synergy is real: In multimodal RL, improvements in one modality reinforce the others, translating directly into stronger overall benchmark scores.
• Data quality beats quantity: When it comes to RL, a steep reward curve slope is often much more critical than sheer training duration.
• Untapped potential in RL infra/algorithm: Especially for multimodal setups, there is still so much room to explore and optimize underlying architectures and scheduling systems.
To better support both the research community and industry developers, we aren't just releasing the model weights—we are also open-sourcing the training datasets and training code.
All LLMs should be omni-modality. We are looking forward to hearing your thoughts and feedback!
Blog: nvda.ws/4tCmhFS
Hugging Face: nvda.ws/4u79ue9
Tech Report: nvda.ws/4tDzHBq
#AI #MultimodalAI #OpenSource #ReinforcementLearning


Hanrong YE @ Nvidia retweeted

8 a.m. An office coffee machine.
Hanrong remembers seeing Jensen standing there alone, making coffee in his leather jacket.
An ordinary moment. One he says he wishes he’d held onto a little longer. 💚
teapaw.org/leoyerrrr/status/21211…


Just last week, I saw Jensen at the Endeavor office around 8:00 a.m., standing alone in front of the coffee machine, quietly making himself a cup of coffee. He was wearing his familiar leather jacket, and I noticed the snow-white hair at the back of his head—a small, aching reminder that my hero was already 63. For a moment, I wondered what NVIDIA would be like without him. Then the thought passed, and the morning went on. I never imagined that, only a week later, he would become a casualty of brutal conflict. Now I keep returning to that moment, wishing I had lingered a little longer. NVIDIA is Jensen.
Jensen, you’ve been on vacation for too long. It’s time to come back to the office!

Over the past week, I’ve been overwhelmed by the love and support of friends, industry colleagues, and people I've never met. Thank you to everyone who has shown kindness to my family and me. It means the world to me.
I came to the United States 53 years ago, and becoming an American citizen is one of the greatest gifts and proudest moments of my life. NVIDIA has been my life’s work. Building it into the company it is today alongside my colleagues has been a privilege and an honor. Nowhere but in America could a company like NVIDIA be possible. I love our country, and I love NVIDIA.
I did not live up to the standards expected of everyone at NVIDIA, and I have made serious mistakes in my personal life. I created problems for the Board that I deeply regret. I own my mistakes completely, and I am committed to cooperating with the Board’s independent investigation.
Since my departure, I’ve seen an outpouring of calls from NVIDIA’s employees, investors, business partners, and customers for me to return as CEO. Many continue to reach out to me directly as the company navigates complex technology, market, competitive, and geopolitical dynamics. NVIDIA is a once-in-a-generation company. If the Board of Directors decides that my return is in the best interest of our shareholders, our employees, the company, and America, I would be honored to answer these calls and return as CEO.
Thank you again to everyone who has shared their good wishes. I am profoundly humbled by your support. To my family: I love you, and I will spend the rest of my life being worthy of yours.
Jensen
Hanrong YE @ Nvidia retweeted

Over the past week, I’ve been overwhelmed by the love and support of friends, industry colleagues, and people I've never met. Thank you to everyone who has shown kindness to my family and me. It means the world to me.
I came to the United States 53 years ago, and becoming an American citizen is one of the greatest gifts and proudest moments of my life. NVIDIA has been my life’s work. Building it into the company it is today alongside my colleagues has been a privilege and an honor. Nowhere but in America could a company like NVIDIA be possible. I love our country, and I love NVIDIA.
I did not live up to the standards expected of everyone at NVIDIA, and I have made serious mistakes in my personal life. I created problems for the Board that I deeply regret. I own my mistakes completely, and I am committed to cooperating with the Board’s independent investigation.
Since my departure, I’ve seen an outpouring of calls from NVIDIA’s employees, investors, business partners, and customers for me to return as CEO. Many continue to reach out to me directly as the company navigates complex technology, market, competitive, and geopolitical dynamics. NVIDIA is a once-in-a-generation company. If the Board of Directors decides that my return is in the best interest of our shareholders, our employees, the company, and America, I would be honored to answer these calls and return as CEO.
Thank you again to everyone who has shared their good wishes. I am profoundly humbled by your support. To my family: I love you, and I will spend the rest of my life being worthy of yours.
Jensen
Just last week, I saw Jensen at the Endeavor office around 8:00 a.m., standing alone in front of the coffee machine, quietly making himself a cup of coffee. He was wearing his familiar leather jacket, and I noticed the snow-white hair at the back of his head—a small, aching reminder that my hero was already 63. For a moment, I wondered what NVIDIA would be like without him. Then the thought passed, and the morning went on. I never imagined that, only a week later, he would become a casualty of brutal conflict. Now I keep returning to that moment, wishing I had lingered a little longer. NVIDIA is Jensen.
Hanrong YE @ Nvidia retweeted

嘿,Jensen! 此片献予你!
我是一名来自中国的 AI 开发者,你一定会回来的对吧。对吧
@JensenHuang
🤖 Made with AI

Hanrong YE @ Nvidia retweeted

When should an AI agent pass the baton?
🚀 Introducing our work AgentBaton from NVIDIA Research: efficient model collaboration through well-timed handoffs.
We study how capable and efficient models can collaborate without fine-tuning either one: who starts, when to switch, and how to pass context.
🛠️ Our approach: a capable model starts; AgentBaton decides when an efficient model takes over.
The next model inherits the workspace, with history passed in context or through log files. The same detector works across different model pairs.
📈 The results: AgentBaton extends the accuracy–cost frontier. Across 11 model pairs, AgentBaton cuts API costs by 65.9% on average with same or improved accuracy.
📄 arxiv.org/abs/2610.35959
🌐 research.nvidia.com/labs/lpr…
Details in 🧵
#NVIDIA

Hanrong YE @ Nvidia retweeted
Impressive NVIDIA paper on cutting agent costs.
For long-horizon agent tasks, you want the capable model for the early steps and a cheaper model for the rest. Handing off in the other direction saves little or nothing.
AgentBaton learns when to make that one switch from patterns in task progress. Each check has a median latency of 338 ms on one H100.
Across 11 model pairs and two benchmarks, it cuts API cost by 65.9% on average while largely keeping accuracy. Some pairs gain up to 8.8 points over running the capable model alone.
The handoff happens once per task, so it is easy to add to an existing agent loop.
If your agent bills are dominated by a frontier model, you might want to test one capable-to-cheap handoff before building a full router.
arxiv.org/abs/2610.35959
Chat with Paper: academy.dair.ai/papers/agent…

Didn’t expect our omni-LLM research release to coincide with Genie 4, but what better time to share Nemotron-Labs-Diffusion-Uni!
Long name, I know— just call it NLD-Uni.
Our goal: bring multimodal understanding and generation into a unified discrete diffusion language model. Two key ideas make this work:
🧑🏫 Cross-paradigm on-policy distillation: learning from autoregressive VLMs for understanding and continuous flow models for visual generation, bridging fundamentally different generation paradigms.
✨ Progressive self-refinement: giving image tokens intermediate states so the model can refine its predictions over multiple steps, improving visual quality.
The result: state-of-the-art performance among unified diffusion LLMs across visual understanding, reasoning, grounding, text-to-image generation, and image editing—with parallel decoding for both image and text tokens.
Our takeaway: discrete tokens offer a promising foundation for bringing strong visual understanding and generation together with efficient diffusion decoding.
Paper, model, and code: github.com/NVlabs/Nemotron-L…


NLD-Uni supports diverse multimodal tasks by adopting an Elastic-MoT architecture with three elastic views of a single model. The VLM view uses the 8B understanding branch; the T2I view combines 4B understanding parameters with the 8B generation branch; and the interleaved view uses both full branches (16B).

1
57
(Left) NLD-Uni introduces a new paradigm for building unified Diffusion LLMs through on-policy distillation from cross-paradigm teachers: VLMs for visual understanding and continuous diffusion models for visual generation. (Right) NLD-Uni achieves highly competitive visual understanding and generation performance with improved speed.

2
231
Hanrong YE @ Nvidia retweeted

Is on-policy distillation really necessary? 🤔
📄 arxiv.org/pdf/2610.11291
🚀 Semi-OPD—distilling on fixed initial-student rollouts—beats OPD on 14/17 teacher–student pairs, with up to +13.6% accuracy and 11.4× training speedup.
More on-policy ≠ better. Alignment matters.

There can be no intelligence without scaling, regardless of which methodology you believe will ultimately lead to AGI.

10
708
Congrats @Mononofu for open-sourcing nothing 😀

I’m so excited that @JensenHuang is a believer in open source now, looking forward to the CUDA and GPU driver open source release!
4
432