

product marketing @p0
San Francisco, CA
Joined January 2014
- Tweets5K
- Following969
- Followers1.3K
- Likes16.9K


Lukas Levert retweeted
MiniMax M3.1 Flash is now #1 on our search capabilities leaderboard for efficiency.
It delivers web research performance with Parallel Search similar to DeepSeek V4.1 Flash (1017) at ~3x lower cost.


MiniMax M3.1 Flash: Space Performance + Bunny Speed
🚀🐰 Yes, Space Bunny - which has topped global leaderboards with 200T+ tokens - was an earlier version of M3.1 Flash.
💰Redefining the performance economics of agentic AI. M3.1 Flash achieves frontier-level intelligence across key tasks such as Cowork (Automation-Bench: 62%; ALE: 30%), Coding (DeepSWE: 74%) and Visual Reasoning (BabyVision: 91%), at 1/3 the cost of M3 and 3x the speed.
API pricing (flat rate): $0.15 / $0.60 per 1M input/output tokens, with cache reads at $0.015 / 1M tokens.
Model weights will arrive on Oct 23.
API: platform.minimax.io
M Plan: minimax.io/m-plan
MiniMax Code for desktop: agent.minimax.io/download

Lukas Levert retweeted
Mercury 3 is the first diffusion LLM we've tested with Parallel Search.
It's Pareto-optimal, delivering capable web research at a price similar to Claude Haiku 5.5, GPT-6 Luna, and DeepSeek V4.1 Flash (base).


Mercury 3 is live: the most capable diffusion LLM released to date.
It outperforms GPT-6 Luna and Claude Haiku 5.5 across a range of benchmarks while running at over 1,000 tokens per second.
More than 40x the size of Mercury 1, 3x more intelligent across standard benchmarks, and just as fast, with a 1M-token context window.
Available today on the Inception API, @baseten, and @OpenRouter .


The minisite mafia strikes again:
archives.parallel.ai


our first big brand campaign is here 🧡
last week, we launched the first batch of our @p0 brand campaign in NYC
every ad is a collage assembled with citations, representing a real research report built on Parallel's APIs
more to come on how we built this. in the meantime, share with us if you encounter it in the wild!


Lukas Levert retweeted
NEW: DeepSeek V4.1 Flash (1017) is the highest-performing open model we've measured.
It's the first to crack the top 10 on the Search Capability Leaderboard across open- and closed-source models.


🚀 DeepSeek-V4.1-Flash-1017 is here!
Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API.
🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy, WorkBuddy, and more. Upgrade to DeepSeek Harness v0.2.1-rc.1 or later for the best experience with the new model.
1/4


Lukas Levert retweeted

I’ve been in London Fields tonight, watching the first ever Lime Bike joust - here’s a thread of my best shots:

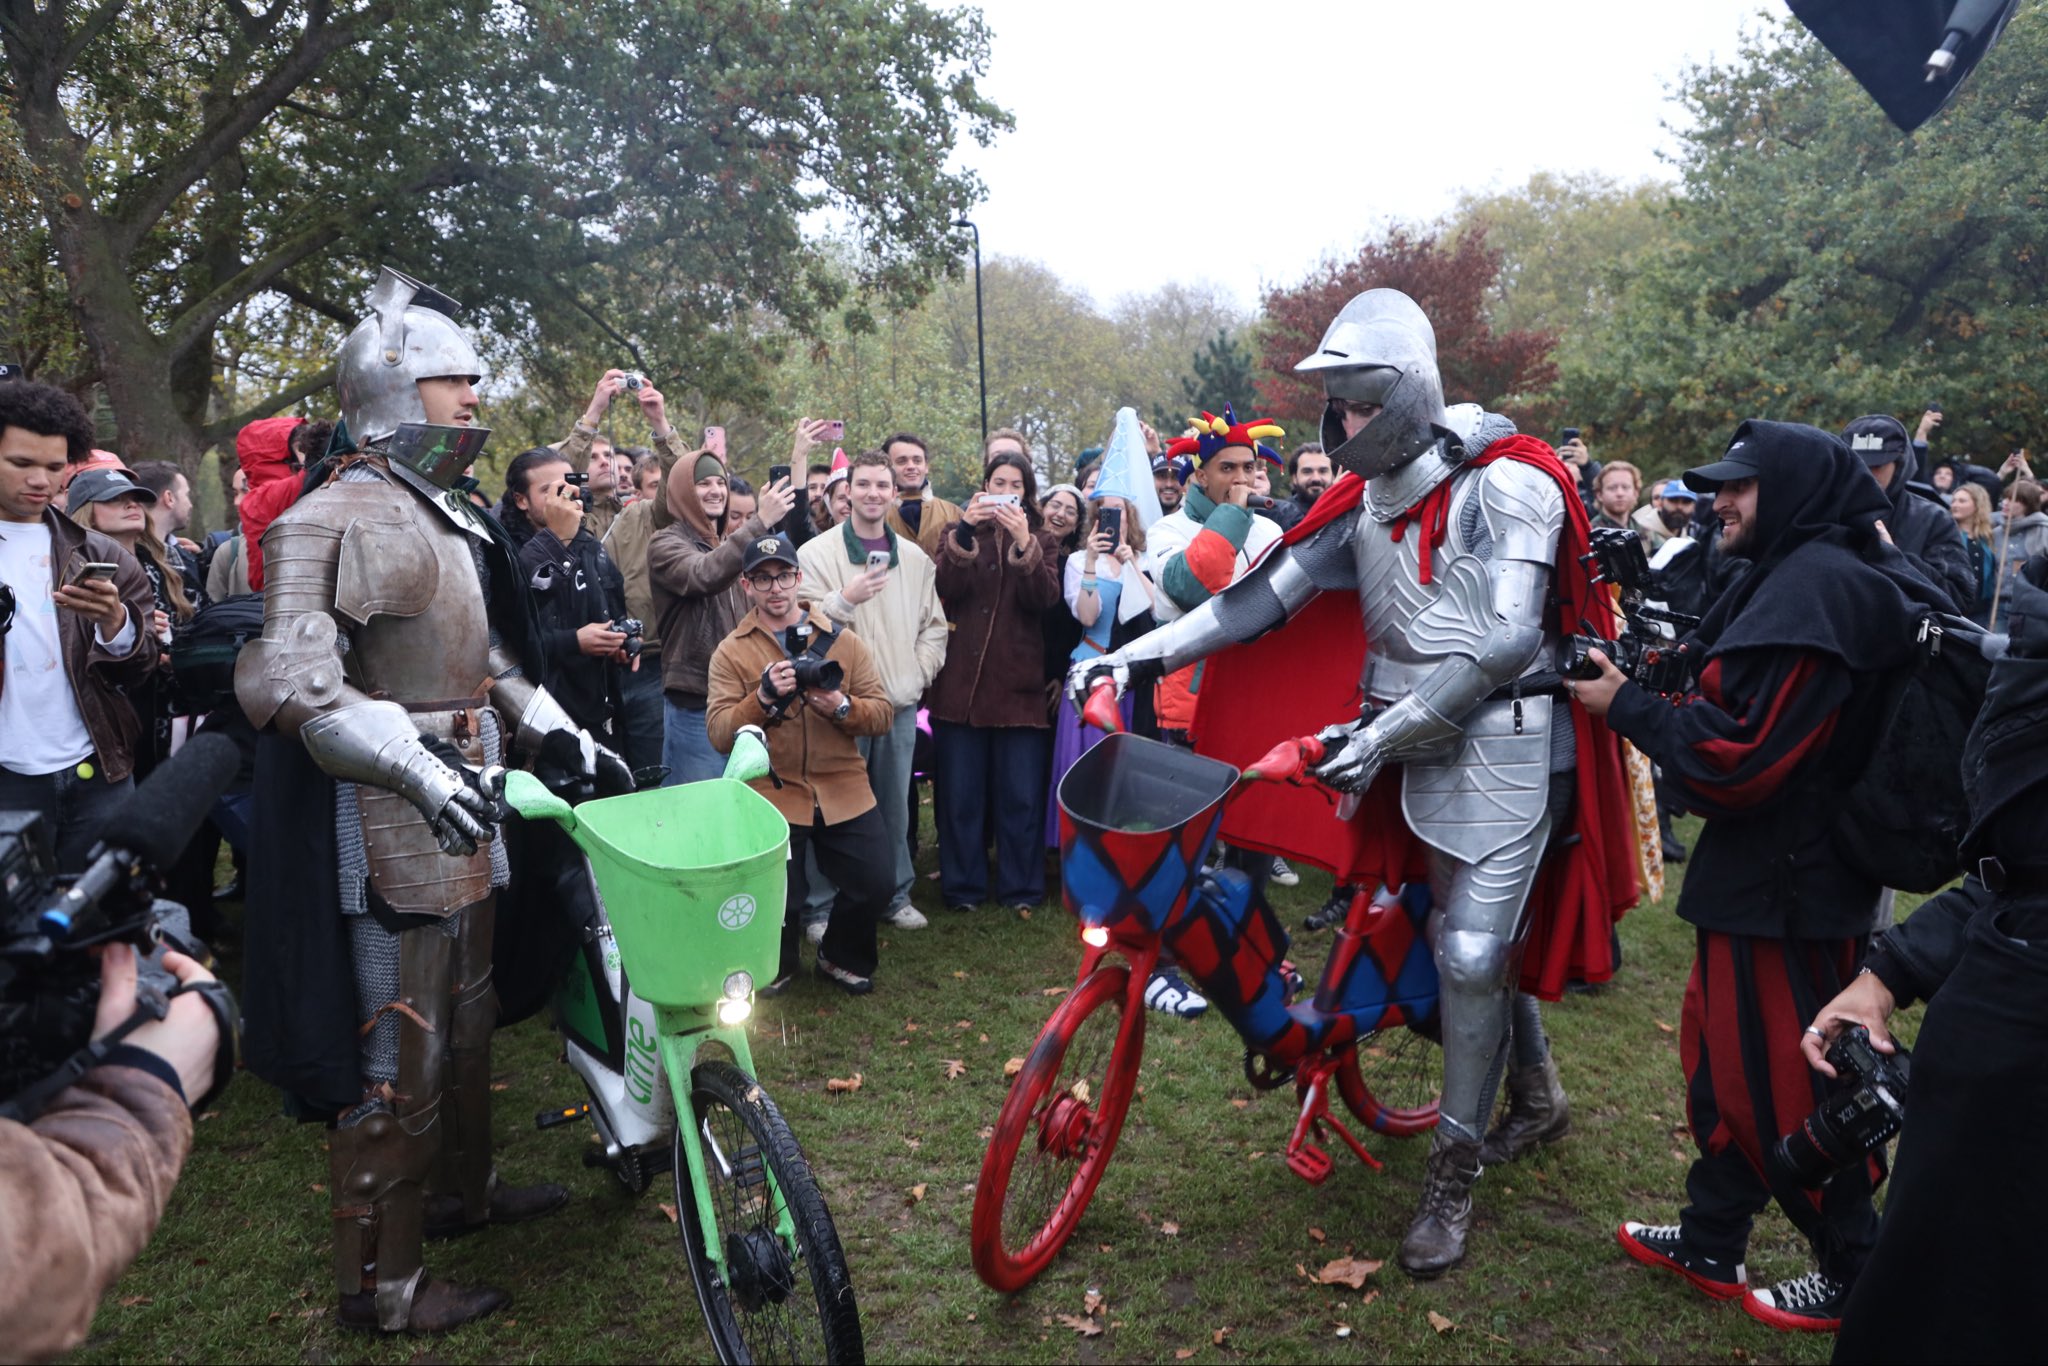


The last thing you see before Roko’s basilisk gets ya


Introducing Hugo: the first human companion robot.
At Boston Dynamics, I was Chief Strategy Officer, bringing robots into the real world.
My co-founder, Farbod Farshidian, led research at the RAI Institute.
Together, 15+ years teaching robots to run, jump, and work.
So we asked: what if robots could connect with people?
Hugo runs on the first Vision-Language-Expression (VLE) model.
He links what he sees and hears to movement, expression, and gesture.
He notices you, reads the room, and reacts in real time.
And he's only the first.
Dynamic Creatures is @BostonDynamics' official entertainment and hospitality partner.
We're building a cast of characters with film studios, resorts, and theme parks.
dynamiccreatures.com


IYKYK

🔍 Search & Fetch APIs are now open to everyone!
Powered by our in-house search engine, serving hundreds of millions of requests daily worldwide.
💰 Each endpoint: $0.75 per 1,000 calls.
📖 Docs: api-docs.deepseek.com/guides…
📌 Search & Fetch calls via server-side tools in DeepSeek Harness, Claude Code, and Codex are currently free for DeepSeek API users. Billing starts Oct 31, 2026, at 16:00 UTC.
3/4


Muse Spark Open is on the @p0 search capability leaderboard.
Similar performance to GPT-5.6 Sol and Gemini 3.7 Flash in an open-weights model.


Today we’re releasing Muse Spark Open, the most capable US open-weight model to date.
Built for coding and agentic work, it excels at long-horizon tasks, complex software engineering, and multi-step reasoning.
Key Model Specs:
→ 816B total / 42B active parameters
→ 1M token context window
→ Natively multimodal across text, image, video, audio


