





Pinned Tweet
Chinchilla writes loss as a sum of two independent terms: model size and data never interact. Kaplan's original law coupled them.
But interaction has an impact, dropping it bends predictions exactly where you extrapolate. Skaling, our new law, puts it back with one exponent. 1/8
Mathurin Videau retweeted

1/
Chinchilla scaling laws enforce a mathematical impossibility: that adding model parameters has zero dynamic interaction with adding tokens.
This cross-derivative blind spot causes severe error at parameter-data boundaries.
Meta FAIR just fixed it with a single exponent. 🧵

Mathurin Videau retweeted

arxiv.org/abs/2608.07222
Simple scaling law formulation that considers the interaction between N and D, and efficient experiment sampling strategy for parameter estimation.


Mathurin Videau retweeted

Meta scientists just proved the foundational law of AI training is broken.
For four years, every frontier lab on earth, OpenAI, Google, Anthropic, DeepSeek, has scaled their models using the exact same rulebook.
Chinchilla scaling laws.
Published in 2022, it became the bible. It's the reason you keep hearing "20 tokens per parameter." Every compute budget, every pretraining run, every architectural decision at the multi-billion dollar labs has been guided by this single formula.
Meta FAIR just published a paper called "Skaling," and it shows Chinchilla is mathematically flawed at exactly the scales frontier labs care about.
Here's the crime scene.
Chinchilla assumes that model size and training data affect the loss independently. Add more parameters over here. Add more tokens over there. The two variables never talk to each other.
Meta went back and directly measured the loss surface. They calculated the mixed derivative, the exact mathematical object that reveals whether two variables actually interact.
It wasn't zero.
Not even close.
The interaction was negative and consistent across the entire training grid. Scaling model size and data together lowers loss more than scaling either alone. A synergy the additive Chinchilla law is structurally incapable of representing.
So they built Skaling.
A minimal, one-parameter fix that couples model size and data through a single interaction exponent. At k=1, you recover Chinchilla. At any other value, you get the real physics of the loss surface.
The results are brutal for the incumbent:
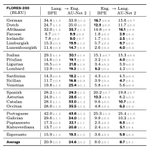
- 1.5x to 3x reduction in prediction error across every regime tested.
- 10x less compute needed to fit an accurate scaling law.
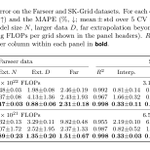
- Far-extrapolation error drops from 5.17% to 0.70% on their own grid.
- On boundary predictions where Chinchilla fails hardest, error drops from 14.63% to 1.15%.
Here is the part that should terrify every lab holding a compute contract.
Chinchilla predicts that at frontier scale (~2×10^25 FLOPs), the optimal token-to-parameter ratio is roughly 380.
Skaling predicts it's 20 to 40.
That's a 10x discrepancy in the single most important architectural decision a lab makes before spending hundreds of millions of dollars on a training run.
Meta then verified this two independent ways using model-free gradient estimators. Both matched Skaling. Chinchilla's prediction was moving in the wrong direction entirely.
Think about what this means.
Frontier labs like DeepSeek have publicly locked in fixed token-to-parameter ratios based on Chinchilla-style reasoning. If Meta is right, some of the biggest training runs in history have been quietly leaving performance on the table, or burning compute on the wrong side of the frontier.
For four years the industry treated Chinchilla as physics.
Meta just showed it was a first draft.

Mathurin Videau retweeted

A new Meta FAIR paper finds a blind spot in the Chinchilla scaling law that becomes expensive when you extrapolate.
Chinchilla can look almost perfect inside a training grid and still mispredict what happens at the frontier.
The problem is: Chinchilla assumes model size and training data help separately, but the experiments show that each changes how useful the other one is.
Skaling adds just 1 extra term to capture that connection, cutting prediction error by about 1.5–3× and getting full-grid Chinchilla-level prediction accuracy with roughly 10× less profiling compute.
On Farseer, the difference becomes huge at frontier scale: at 2×10^25 FLOPs, Chinchilla points to ~380 tokens per parameter, while Skaling and the paper's direct estimates land around 20–40.
– arxiv. org/abs/2608.07222
Title: "Skaling: Chinchilla's Exponents Meet Kaplan's Coupling"

Mathurin Videau retweeted

"Skaling: Chinchilla's Exponents Meet Kaplan's Coupling"
Skaling shows a simple flaw in Chinchilla scaling laws where model size and training data are not independent.
By adding one coupling exponent cuts extrapolation error by 1.5-3x and enables accurate scaling predictions with ~10x less profiling compute.
alphaxiv.org/abs/2608.07222

Mathurin Videau retweeted

The Top AI Papers of the Week (August 10 - August 16)
- Skaling
- Harness-IF
- Mind Viruses
- Distilled Reasoning Skills
- Stealing Reasoning Traces
- Programmatic Tool Calling
- Catastrophic Remembering
Read on for more:


Mathurin Videau retweeted

Impressive new paper from Meta.
(bookmark it)
Scaling laws assume model size and training data act on loss independently.
This work introduces Skaling law, which couples capacity and data through a single interaction exponent. The extra term cuts mean absolute percentage error by 1.5x to 3x across both interpolation and extrapolation.
The largest corrections land in the data-scarce and heavy-overtraining regimes where the standard Chinchilla and Kaplan forms drift.
Paired with a sparse grid restricted to low-compute runs, it extrapolates the full grid using roughly 10x less compute than a uniform sweep.
Why does it matter?
Deployment now happens well past compute optimal. A law that stays accurate there, and that can be fit from small runs, changes how a pretraining budget gets planned.
Paper: arxiv.org/abs/2608.07222
Track more trending AI papers in our academy: academy.dair.ai/

Coupling also moves compute allocation. On Farseer data, model-free estimates of the optimum track Skaling rather than Chinchilla: tokens/parameter fall as compute grows. At 2×10²⁵ FLOPs, ≈380 versus 20 - 40. 7/8

A scaling law can fit the interior of your grid perfectly and still be wrong at every edge. The edges are the part you extrapolate from.
Huge thanks to my co-authors @byoubii, David Lopez-Paz & @KartikAhuja1 🙏
📄 Paper: arxiv.org/abs/2608.07222 8/8

Mathurin Videau retweeted

WaiT for the Signal: Simple Frequency-Aware Flow-Matching.
We show how to natively incorporate a fundamental property of images directly into diffusion models; setting a new pixel-space SOTA on ImageNet, while reducing compute.
📄 arxiv.org/abs/2607.28760
Full breakdown below👇
Mathurin Videau retweeted

🧵How to combine code correctness and efficiency objectives in online RL?
-> we break the correctness-efficiency Pareto frontier!
+125% relative improvement in CWM32B compared to standard RLVR (13.7 ->30.9 pass@1@top30%)
+150% with Qwen32B
Paper: arxiv.org/abs/2607.25970


Mathurin Videau retweeted

What advantage to use, and when? Everyone's proposing new advantage functions for RL with LLMs but nobody knows why they work or fail.
We break this down and build FADE a self-adapting advantage to get +14% on LiveCodeBench v6 in 40% less steps.
Paper: arxiv.org/pdf/2607.01490
Mathurin Videau retweeted

🧵 For 2 RL checkpoints trained differently, you can just weight extrapolate them and it works!
Bonus: these extrapolated checkpoints are complementary policies
-> Get exploration and diversity for free
-> Better inference scaling when ensembling
Paper: arxiv.org/abs/2605.28751
arxiv.org/abs/2605.28751
Now many studies try to do extrapolation through model merging. arxiv.org/abs/2605.26484

