

co-founder/ceo https://xitter.cf/t.co/RAAaSu0RMJ | xresearcher @ETH @ycombinator
San Francisco, CA
Joined December 2022
- Tweets1.3K
- Following479
- Followers2.8K
- Likes3.3K





Pinned Tweet
Most RL frameworks are fundamentally unstable.
We wasted more H100 hours on debugging this than any other issue fornour multi-turn, multi-env RL run (below).
When using OpenAI-style messages for env interactions, parsing and retokenizing leads to subtly different tokens. This creates extremely unlikely tokens, which dominate the gradient and over time lead to collapse. The screenshots describe the mechanism in more detail.
We tried a lot of interventions, but ended up reimplementing our environments to use token lists directly (Tokens-in/Tokens-out). This fixed it immediately.
Always inspect logprobs!


we just released our first model: SID-1
it's designed to be extremely good at only one task: retrieval.
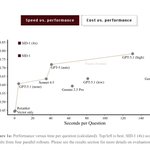
it has 1.8x better recall than embedding search alone (even with reranking) and beats "agentic" retrieval implemented using all frontier LLMs, including the really large and expensive ones (see chart).
we trained SID-1 using multi-environment, multi-turn RL on Qwen. it was a lot of work (a lot of which is documented in our tech report -- see pinned tweet).
our RL environments build on the idea that humans with search tools can find almost any information given sufficient iteration. like humans, SID-1 makes a first search, read the results, and adapts its strategy.
and it can do this much faster *and* better than frontier LLMs: 24x faster than GPT-5.1, 27x faster than Gemini 3 Pro.
the better part is critical! if a model is fast and wrong, it's just wrong. that's why we trained SID-1 until it was the most likely to deliver the correct results. bar none.
we're partnering with a small number of companies today and have a waitlist for everyone else. (we don't have enough inference compute for everyone yet).


$1B ~= 11k B300s for 3 years (rented)
$3.50/h * 24 * 365 * 3 = $92k / GPU
$1B / $92k = 10,872 GPUs.


we have an entropy guy.
he sets e_clip_high and e_clip_low in our runs.
we just replaced him with an algorithm. it works.
RSI is near.

to my friends in zurich this week. we're throwing small events with a @ycombinator partner and a @cerebras cofounder. already oversubscribed, but might find more room.
too much TIS, not enough 'tism.

RL with LLMs is very unstable when training and sampling policies differ. Standard fixes (matching numerics, importance sampling) work around the problem.
We find the root cause of this instability from first principles and propose a way to directly cancel it. Score Centering is competitive and compatible with existing approaches — while simple to implement!
🧵 [1/6]

running a website requires 1 CPU per 10k users.
running a Claude/Codex sandbox is 1 to 1-ish.

$NET Matthew Prince reveals running every knowledge worker's agent in containers would need 40x the world's CPUs
" Really the whole hyperscale world and all of the mobile world is built on this idea of containers."
"The problem with containers is, if you imagine every single knowledge worker on earth has one agent that's running for them, which seems, I mean, pretty conservative, I think most knowledge workers are going more than one agent, and you imagine those agents are all running in containers."
"The problem with containers is you have to import a whole operating system and tool chain, all this stuff, just to power that."
"Not even looking at GPUs, just looking at CPUs, you need 40x the number of CPUs that are produced in the world in order to just run the agents for those knowledge workers, which is, like, that's not going to work."
new chart crime unlocked

Zhipu ($2513.HK) filed its first interim report as a public company on 31 Aug. 19 of the 60 pages read like a technical blog, plus a 9-page technical glossary. Most investors would not expect to see GRPO, mHC and a 3D pareto frontier chart in a financial report. Zhipu defines the pareto frontier of a SOTA model to be speed of iteration X intelligence index X per task cost. (1/3)🧵


first time i've audibly said wow at a product announcement in a while.
given hbm4, the better comparison is probably vera rubin, but this is just nuts.
well done!

Since announcing Jalapeño, our first custom inference chip, we’ve been testing it and the system around it.
The results show a major advance: more intelligence from every watt and faster responses, delivering both higher throughput and lower latency in one architecture without sacrificing efficiency.
Max Rumpf retweeted

1/ Today, @Primero_ai is announcing its public launch and a $12m seed, one of the largest seed rounds in LatAm.
Primero is the AI transformation company for Latin America's largest enterprises.

