

ML PhD @ucl | @adobe | ex @nvidia | @ELLISforEurope | Interested in visual generation
London, UK
Joined July 2012
- Tweets165
- Following480
- Followers350
- Likes1.1K



Pinned Tweet
🎉 LoST: Level of Semantics Tokenization (CVPR 2026)
What if 3D generation didn’t start from coarse geometry, but from semantics?
We introduce LoST, a semantic-first 3D tokenizer that orders tokens by semantic salience, so even very short prefixes can already decode into complete, plausible, recognizable 3D shapes 🧩
Early tokens capture the principal semantics.
Later tokens refine the details.
Result: Generate 3D shapes starting from as few as 1 token!
The goal is to have high fidelity shapes even with very few tokens, with more tokens semantic alignment increases.
Project: lost3d.github.io/
Paper: arxiv.org/abs/2603.17995
@CVPR @AdobeResearch @Adobe

Really cool work and shows how one can enable various levels of detail during generation.
Checkout our #CVPR 2026 work on 3D generation-- Level of Semantics Tokenization for 3D Shapes
lost3d.github.io/
Code is now released.

Diffusion models spend the same compute on a blank wall as on a face. But you often know in advance where the detail will be.
Introducing Level-of-Token (LoT) Diffusion: we turn that knowledge into a multiresolution token layout, with fine tokens where detail is needed and coarse tokens elsewhere.
1/9🧵
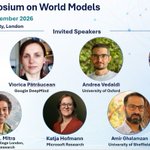
Excited to announce the @TheBMVA Symposium on World Models! 🌍
📍 London | 🗓 Nov 18, 2026
We have an amazing lineup of speakers joining us! Check out the full program, registration, and poster submission details:bmva.org/meetings/26-11-18-W…
#AI #worldmodels #computervision


Niladri Dutt retweeted

A really refreshing take on 3D generation: instead of building shapes from coarse geometry, build them from semantics.
huggingface.co/papers/2603.1…

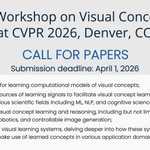
Excited to share the 3rd Workshop on Visual Concepts at @CVPR 2026! Call for papers is now open till April 1. We welcome submissions on the following topics. See our website for more info: sites.google.com/stanford.ed…
Join us in Denver!
#CVPR2026

Niladri Dutt retweeted

🎉Thrilled to share that CABS is accepted to #CVPR2026! See you in Denver!
Everything is now open-sourced:
Webpage:cabs-vlp.github.io/
DataConcept:huggingface.co/datasets/beth…
Paper:arxiv.org/abs/2511.20643
Code:github.com/bethgelab/cabs
Excited to see what the community builds!

🚨Current data curation results in the creation of static datasets and the use of model-based filters that induce many biases. Can we fix this?
We propose ✨CABS✨, a flexible concept-aware online batch curation method that improves CLIP pretraining!
arxiv.org/abs/2511.20643
🧵👇

Niladri Dutt retweeted

Happy to bring back the 3rd Workshop on Visual Concepts at @CVPR 2026! Call for papers is now open.
We welcome submissions on the following topics. See our website for more info: sites.google.com/stanford.ed…
Join us in Denver!

Niladri Dutt retweeted

Excited to introduce 🎬ActionMesh, a fast model transforming any video → high-quality animated 3D mesh !
Generate animated mesh seamlessly importable into any 3D software in less than a minute.
🤗Try it out: huggingface.co/spaces/facebo…
🌐Project Page: remysabathier.github.io/acti…
📄Paper: remysabathier.github.io/acti…
💻Code: github.com/facebookresearch/…
#Video4D #GenAI #3DGeneration
@Meta @RealityLabs @AIatMeta @ucl
Animation brings characters to life 🎬✨
Introducing our #SIGGRAPHAsia '25 (TOG) paper:
Self-Supervised Motion Fields (SMF) that can transfer motion from any source (even 2D video) to any stylized character!
🚫 No Rigging 🚫 No Templates (SMPL) ✅ Any source
🧵Thread👇
Project website: motionfields.github.io/
Paper: arxiv.org/abs/2504.04831
Code: github.com/sanjeevmk/SMF
Can an LLM learn professional photo retouching by solving puzzles?
Our new work, MonetGPT, presented at #SIGGRAPH2025, shows it can.
By solving visual puzzles, our MLLM becomes operation-aware and develops image aesthetics.
Check out our blog from @AdobeResearch & code below👇
#AI #MLLM
✍️ Blog Post: research.adobe.com/news/adob…
💻 GitHub: github.com/niladridutt/monet…
🌐 Project Website: monetgpt.github.io/
Check out this thread to learn more
teapaw.org/niladridutt/status/192…


🧵9/10 We quantitaively evaluate on the Adobe5k dataset as well as conduct user studies by expert and novice users. Our evaluations show that MonetGPT outperforms open-source alternatives and performs comparably to Google Photos AutoEnhance (closed-source).

🧵10/10 Lastly, huge thanks to my co-advisors Niloy and Duygu!
For more details check out our paper below-
🌐 Project Website: monetgpt.github.io/
📄 Arxiv: arxiv.org/abs/2505.06176