Nicolas Phung (@nsphung) header
Nicolas Phung (@nsphung) profile picture

Freelance Data Solution Architect / RT interesting news about software development & computer science. Occasionally asking for help when stuck!

Paris, France
Joined April 2009
Photo by Nicolas Phung (@nsphung)Photo by Nicolas Phung (@nsphung)Photo by Nicolas Phung (@nsphung)Photo by Nicolas Phung (@nsphung)Photo by Nicolas Phung (@nsphung)Photo by Nicolas Phung (@nsphung)Photo by Nicolas Phung (@nsphung)Photo by Nicolas Phung (@nsphung)Photo by Nicolas Phung (@nsphung)Photo by Nicolas Phung (@nsphung)
La prochaine fois que vous serez contrôlés à bord d'un train en France, vous saurez que c'est via une architecture réactive #akka et #Kafka ! Pour plus de détails, on vous invite avec @yaourtcorp @ouisncf_news à jeter un oeil sur #DevoxxFr youtu.be/0xQfne7s_xE
3
6
22
Nicolas Phung retweeted
Vector databases are no longer a cloud product. They're becoming a pip install. A new open-source project called turbovec just crossed 10K stars on GitHub. And once you understand what it does, you understand why. It's a Rust vector index with Python bindings, built on Google Research's TurboQuant algorithm, a quantizer accepted at ICLR 2026 that compresses embeddings to within a hair of the theoretical Shannon limit. No codebook training. No train phase. No rebuilds as your corpus grows. You add vectors, they're indexed. Done. The headline number: A 10 million document corpus takes 31 GB of RAM as float32. turbovec fits it in 4 GB and searches it faster than FAISS. Read that again. Faster than FAISS. The library Meta has tuned for a decade. Hand-written NEON and AVX-512 kernels beat FAISS FastScan by 12–20% on ARM and match-or-beat it on x86. (And the recall benchmarks are published openly against FAISS as the baseline including the configs where it loses. That honesty alone is rare in this space.) But the speed isn't even the strategic part. The strategic part is what this enables: Fully local, air-gapped RAG. 10M documents in 4 GB means your entire company knowledge base fits in the RAM of a MacBook. Pair it with an open-source embedding model and nothing not a query, not a vector, not a document ever leaves your machine. It also ships drop-in replacements for the vector stores inside LangChain, LlamaIndex, and Haystack. Swap one import, keep your pipeline. The switching cost is approximately zero. The obvious comparison is SQLite. Databases used to be servers you provisioned and paid for. Then SQLite made the database a file inside your app, and an entire category of managed infrastructure became optional for most use cases. The same compression-driven collapse is now coming for vector search. Every startup selling "managed vector search" as a line item should be paying attention. When the index fits in laptop RAM, runs faster than the industry standard, and installs in one line the moat was never the database. The vector database is becoming an embedded library, not a cloud service. And the frontier of RAG just moved on-device. Really cool to see.
30
117
630
40,206
Nicolas Phung retweeted
🚨 The #1 problem with local AI is now solved. There’s a new tool called llmfit that checks your hardware and tells you which models will run well before you download anything. So instead of guessing and hitting out-of-memory errors…it gives you a ranked list based on your machine. What it does (in one command): → scans your setup (RAM / CPU / GPU / VRAM) → evaluates models for quality, speed, fit, and context → selects the best quantization automatically → labels what’s ideal vs okay vs borderline The part I like most: it handles MoE models correctly. Example: Mixtral 8x7B has ~46.7B total params, but only ~12.9B are active per token, and llmfit accounts for that (a lot of tools still don’t). 100% Opensource.
111
414
23
3,796
229,710
Nicolas Phung retweeted
It's true: TypeScript surpassed Python and JavaScript to become the most-used language on GitHub. 📈
234
581
260
5,404
527,885
Stop building AI Agent plumbing🛠️ 🧠 Brain: @LangChain Deep Agents (Reasoning + Harness) 👀 UI: @CopilotKit (Generative UI) ☸️ Infra: @skaffolddev (Kubernetes ready) I tied it all together in the Agent Studio Starter. Go from "Idea" to "K8s-Deployed" in minutes🚀
2
2
87
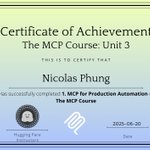
✅ MCP course done & certified! Grateful for a challenging but rewarding experience with Hugging Face MCP Course. Huge thanks to @huggingface 🤗 top-notch content 👏 Now applying it IRL and sharing what I’ve learned with others! #HuggingFace #LLMs #MCP #AI #MachineLearning
67
🚀Certified! Wrapped up the @huggingface Agents Course and learned a ton. It involved: • Late-night debugging 🧠 • Free-tier LLM hunting 🕵️ • Baby in one arm, keyboard in the other 👶⌨️ Proof that where there's a will (and Wi-Fi), there's a way. #AI #LLM #MachineLearning
26
We’re building a new static type checker for Python, from scratch, in Rust. From a technical perspective, it’s probably our most ambitious project yet. We’re about 800 PRs deep!
107
211
80
2,659
160,585
Nicolas Phung retweeted
Rome wasn't built in a day. How does Redis architecture evolve? Redis is a popular in-memory cache. How did it evolve to the architecture it is today? 🔹 2010 - Standalone Redis When Redis 1.0 was released in 2010, the architecture was quite simple. It is usually used as a cache to the business application. However, Redis stores data in memory. When we restart Redis, we will lose all the data and the traffic directly hits the database. 🔹 2013 - Persistence When Redis 2.8 was released in 2013, it addressed the previous restrictions. Redis introduced RDB in-memory snapshots to persist data. It also supports AOF (Append-Only-File), where each write command is written to an AOF file. 🔹 2013 - Replication Redis 2.8 also added replication to increase availability. The primary instance handles real-time read and write requests, while replica synchronizes the primary's data. 🔹 2013 - Sentinel Redis 2.8 introduced Sentinel to monitor the Redis instances in real time. is a system designed to help managing Redis instances. It performs the following four tasks: monitoring, notification, automatic failover and configuration provider. 🔹 2015 - Cluster In 2015, Redis 3.0 was released. It added Redis clusters. A Redis cluster is a distributed database solution that manages data through sharding. The data is divided into 16384 slots, and each node is responsible for a portion of the slot. 🔹 Looking Ahead Redis is popular because of its high performance and rich data structures that dramatically reduce the complexity of developing a business application. In 2017, Redis 5.0 was released, adding the stream data type. In 2020, Redis 6.0 was released, introducing the multi-threaded I/O in the network module. Redis model is divided into the network module and the main processing module. The Redis developers the network module tends to become a bottleneck in the system. Over to you - have you used Redis before? If so, for what use case? – Subscribe to our weekly newsletter to get a Free System Design PDF (158 pages): bit.ly/3KCnWXq
4
151
2
608
35,916
I spent many years on the road with rockstar sales teams. One of the biggest lessons I've learned is: Make your pitch, and then shut up and listen. It is very natural to want to talk more and more. Especially if the prospect looks skeptical. Resist the urge. If you listen, they will start talking. And sometimes they end up selling to themselves. Even if they don't, what you hear will help you learn their concerns, and you can discuss them. The worst mistake you can make is to keep talking with no information. You are too likely to accidentally say something that will convince them not to buy! If you know me, you know it is extremely hard for me to shut up. Especially when I get excited about a technical topic. But it is worth the mindful effort to get this right. You want to excite the customer, have them ask for more, and not bore them.
10
15
5
148
15,375
Little interview with @TechplacesFR about my experience as Machine Learning Engineer linkedin.com/posts/nsphung_i…
1
32
7
231
3
1,207
129,392
Nicolas Phung retweeted
Stupid ways to compensate programmers: I've seen every single one of these. They backfire and make working for your company a living hell. Pay your developers by the number of bugs they close. After a week, they will start committing bugs on purpose so they can fix them a day later. Pay your developers by the number of features they deliver. After a week, nobody will want to work on anything that takes more than a few minutes to complete. Pay your developers by the number of lines of code they write. After a week, you'll get triple spaces between every line of code. Pay your developers by the number of commits they make. After a week, your repository will become more useless than a screen door on a submarine. Pay your developers based on the reviews from their peers. After a week, you'll have a hostile environment, backstabbing, and politics. During the British rule in India, the government wanted to reduce the cobra population. They offered a reward for every dead cobra. Some people saw this as an opportunity to profit. They started breeding cobras to kill them and collect the reward. The British government had to stop the program. With no reward to collect, farmers set the snakes free, making the infestation much worse. Be careful what you wish for. You might get it.
121
435
46
2,192
515,564
Nicolas Phung retweeted
It takes 23 minutes to recover after an interruption 🕒 I wrote about the cost of context switching on @TheLeadDev: bit.ly/context-swtch ✍️
22
316
23
1,411
164,086
Nicolas Phung retweeted
A recipe for massive technical debt: 📉 🚫 Throw a large number of developers at an empty project...and tell them to hurry. 🚫 Don't bother with communication, planning, or collaboration. We don't have time for that. 🚫 Give them no clear technical guidelines or direction. Assume they'll figure it out. 🚫 Skip types. Assume we can move faster in a "dynamic, fast-paced environment". 🚫 Ignore key aspects of quality like security, performance, accessibility, readability, and reuse. Assume we can tack those on at the end. 🚫 Skip reviews / pairing. Assume whatever everyone writes is fine. 🚫 Don’t configure CI, source control, testing, formatting, or linting up front. Assume we’ll do these things later. Good luck.🤞
39
211
13
1,040
195,976
Nicolas Phung retweeted
This is huge: Llama-v2 is open source, with a license that authorizes commercial use! This is going to change the landscape of the LLM market. Llama-v2 is available on Microsoft Azure and will be available on AWS, Hugging Face and other providers Pretrained and fine-tuned models are available with 7B, 13B and 70B parameters. Llama-2 website: ai.meta.com/llama/ Llama-2 paper: ai.meta.com/research/publica… A number of personalities from industry and academia have endorsed our open source approach: about.fb.com/news/2023/07/ll…
379
3,326
751
14,793
4,294,788
Nicolas Phung retweeted
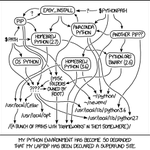
Poetry offers a powerful solution for managing #Python projects with consistent environments. In this article, we explore Poetry's unique advantages over Pip and Conda. bit.ly/42INhoP
8
73
4
402
86,391
Nicolas Phung retweeted
Coworker: Dude, wake up!. The deadline is here. We need to push change. Me: Noop. Read-only Friday.
6
194
9
1,404
132,958