
Cambridge, MA
Joined July 2023
- Tweets34
- Following287
- Followers140
- Likes98


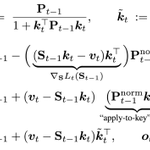


Pinned Tweet
Some say Gated DeltaNet > Mamba-2. Others say Mamba-2 > Gated DeltaNet.
But what if Gated DeltaNet = Mamba-2? 👀
Well maybe not exactly — but with least-squares preconditioning, we show that they reduce to the same recurrence!
We use this lens to design PDN, PGDN, and PKDA: preconditioned delta-style recurrences that outperform their unpreconditioned counterparts at scale 📈
📄 Paper: arxiv.org/abs/2604.21100 w/ @loo_noel @liquidai
💻 Code: github.com/ntumm120/precondi…

Neehal Tumma retweeted

Introducing 𝙻𝙵𝙼𝟹: our new generation of Liquid Foundation Models. With a new tri-hybrid architecture and new multimodal encoders, the LFM3 family is the ideal model suite for specialized intelligence.
> 6 model instances, across text, audio, vision, and omni modalities, generative and decision models.
> 𝙻𝙵𝙼𝟹-𝟷.𝟽𝙱: text, 256k context window.
> 𝙻𝙵𝙼𝟹-𝚅𝙻-𝟸𝙱: vision-language model with video-input support for spatial understanding
> 𝙻𝙵𝙼𝟹-𝙰𝚞𝚍𝚒𝚘-𝟸𝙱: tool calls, voice chat, reasoning in 18 languages.
> 𝙻𝙵𝙼𝟹-𝙾𝚖𝚗𝚒-𝟸𝙱: an omni model combines vision, audio, and language.
> 𝚍𝟷-𝟸𝙱 and 𝚍𝟷-𝙾𝚖𝚗𝚒-𝟸𝙱: decision models with typed outputs and calibrated probabilities in a single pass. Omni adds audio input.
> fine-tune on 1 GPU.
> a new tri-hybrid architecture
> architecture optimized for 14 processor classes across GPUs, CPUs, and NPUs.
> 𝙻𝙵𝙼𝟹-𝚅𝙻-𝟸𝙱 is a beast. It performs competitively with Gemma 4 12B (6x larger), and Gemini 3.5 Flash Lite, and GPT-5.6 Luna, with 1.9B parameters.
> 𝙻𝙵𝙼𝟹-𝟷.𝟽𝙱 is #1 on the Pareto frontier of device intelligence 𝚙𝚒𝚙𝚎𝚝𝚝𝚎.𝚕𝚒𝚚𝚞𝚒𝚍.𝚊𝚒
Every modality for specialized intelligence. Pick the one that fits your use case, customize it, and run it on-device.
1/ 🧵
Super interesting work applying test-time regression along the depth axis

mHC and AttnRes demonstrate that richer depth mixing improves model performance at scale. Is there a unifying perspective? 🤔
Meet our Depth Memory framework: each layer reads from a set of streams to form its input, then writes back its output.
Linear Depth Memory (LDM) equips models with a matrix-valued memory.
Neehal Tumma retweeted

Linear attention is arguably the most naive RNN, but still massively outperforms traditional RNNs by maintaining a matrix state. So... what if we use a (triadic) outer product of three vectors and maintain a three-dimensional state?
Introducing: Triadic Linear Attention 🧵

Neehal Tumma retweeted

SFT is not dead! 🥳
We found a way to make SFT rival current prevailing posttraining methods, often generalizing better and forgetting less than RL and OPSD. 🤯
Following our prior work on reasoning with sampling, we now introduce sampling to the posttraining stack.
1/n
PGDN and PKDA have been merged into FLA, check them out! github.com/fla-org/flash-lin…

Some say Gated DeltaNet > Mamba-2. Others say Mamba-2 > Gated DeltaNet.
But what if Gated DeltaNet = Mamba-2? 👀
Well maybe not exactly — but with least-squares preconditioning, we show that they reduce to the same recurrence!
We use this lens to design PDN, PGDN, and PKDA: preconditioned delta-style recurrences that outperform their unpreconditioned counterparts at scale 📈
📄 Paper: arxiv.org/abs/2604.21100 w/ @loo_noel @liquidai
💻 Code: github.com/ntumm120/precondi…
Neehal Tumma retweeted

Looped models scale compute by iterating in depth, demonstrating great potential in reasoning. But when should the looping stop, and how to keep it trainable at tens of thousands of unrolled layers? FPRM solves both. (1/7)

Cool paper showing the utility of data-dependent short convolutions.
One comparison I’d love to see: explicit filter conditioning used here vs the LFM style approach from @liquidai, where the short conv kernel is static but the local operator remains input-dependent via gates.
Basically dynamic vs gated static FIR filters.


Neehal Tumma retweeted

Excited to share SwitchCraft, our first step toward designing complex protein function through state switching (ligand responsive binders, allosteric control, biosensors, and more).
Stay tuned for wet-lab results from our amazing collaborators very soon!

Binder design has come of age thanks to generative models—but how can we access the wider array of dynamic, multistate protein functions, so elegantly employed by nature?
@mihirbafna14 and I are excited to share SwitchCraft, a framework for designing such functions. (1/7)
(13/N) But we think this only scratches the surface.
PDN/PGDN/PKDA are just three points in a larger design space: different recurrence families + different preconditioners.
There is a huge optimization literature on preconditioning that can be translated into recurrence design.
The bigger message: preconditioning is a useful new lever for designing linear recurrences.